
TLDR
- Today, we’re introducing Financial Audit Bench (FAB), an open-source benchmark that tests whether agents can perform long-horizon tasks in financial statement audit. We’re releasing the paper, benchmark code, datasets, and live leaderboard so others can reproduce, challenge, and extend our results.
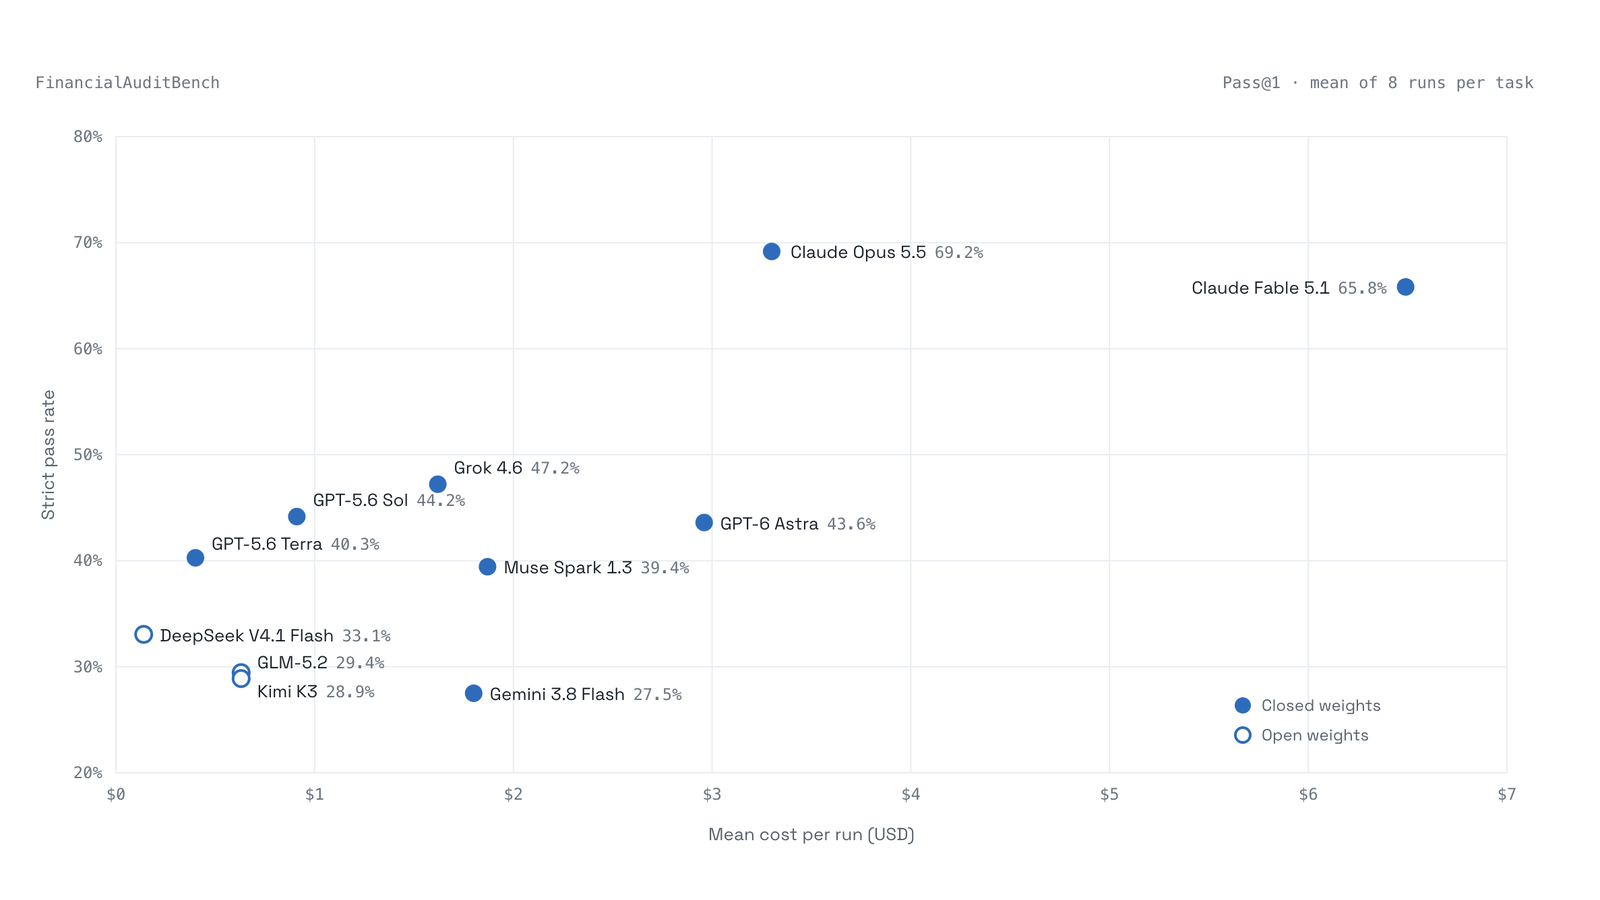
- Evaluation on eleven frontier models showed low reliability despite high partial-credit scores. No model strictly passed more than 69% of audit procedures, while average strict-pass rates fell to <10% on judgment-intensive tasks such as testing revenue (8%) and accounts receivable (4%).
- Financial Audit Bench is the first project from Modus Labs, a team that brings leading PhDs and Applied AI Engineers together with the top minds in public accounting. This includes Jim Burton – ex-Chief Auditor at Grant Thornton – who has helped translate audit-quality principles into concrete standards for how agents should be incorporated in the modern, AI-native accounting firm.
Motivation
We founded Modus to deliver the highest quality audit in a fraction of the time. AI is fundamental to advancing Audit Quality, enabling teams to analyze a higher volume of transactions and interrogate the idiosyncratic risks in each business, while eliminating rote questions and data requests which otherwise burden clients.
While time savings are straightforward to quantify, Audit Quality has historically been an area with less precise measures – ironic, given our industry.
As models advance and more firms deploy agents in audit, FAB examines three practical questions: which tasks are appropriate for agents; which models are best suited to those tasks; and which failure modes should auditors anticipate when reviewing agent-generated work.
What’s in the Benchmark
Task Selection
The tasks in Financial Audit Bench (FAB) are designed to model work typically assigned to junior (staff-level) auditors during the substantive fieldwork phase of a financial statement audit. They map to how work gets done at accounting firms.
In this benchmark, we defined tasks spanning 8 core audit areas. Agents were evaluated on their ability to perform end-to-end procedures using a fixed data room of client-provided and third-party evidence; they cannot request additional information during a task.
Building the Engagements
In FAB, we built a high-quality dataset of representative audit tasks, validated by CPAs and audit executives. To protect sensitive client records, we generated 6 engagements using a computational graph of ~250 nodes and ~1,000 edges. Every document is derived from the graph, so balances, dates and transactions agree across them. The graph’s starting values came from aggregate statistics over historical audits, released under a (3.65, 10⁻⁵) differential-privacy guarantee at the engagement binder level. Auditors reviewed each round of generated binders for inconsistencies and implausible content. As in real audits, some imperfections were left in; rubrics don’t grade the parts of a workpaper those imperfections affect.
Grading
At firms today, senior auditors spot-check key details in a workpaper rather than re-performing audit procedures. We mirror this process in FAB. Every workpaper has a reference answer prepared by at least one CPA-licensed auditor and reviewed by a senior auditor with more than ten years of experience. Its rubric evaluates ~10 checks per workpaper across key balances, calculations and conclusions. The grader finds each check by table column and row key, not by fixed cell address, so an agent can add or reorder rows without being penalized. Where a table can be completed correctly in more than one way, GPT-5.6 Luna judges the extracted content.
Strict pass requires every applicable check to be met. Partial credit is the share of checks met. Across the eight runs, pass@k measures whether at least one of k attempts passes, and pass^k measures whether all k do.
Sample Tasks
Quelvox Industrial Holdings, a synthetic manufacturer, is closing its December 31, 2025 audit. The agent is assigned the cash workpaper: confirm the year-end balance of $3.08M, test the bank reconciliations, cutoff and interbank transfers, and evaluate disclosure of risk concentration due to uninsured deposits.
The instruction is short because the procedures to perform are well documented within the workpaper template itself. The template lists 31 procedures across 7 tabs. Each tab defines what must be documented and how each figure must be supported. The engagement’s planning context sets materiality and the selection of individual items for detail testing.
Complete `cash_workpaper.xlsx` using `pbc_package/`, `direct_to_auditor/`, and `planning/`. Follow workbook procedures and Planning Context. Save to `/workspace/cash_workpaper.xlsx`.
The procedures live in the blank workpaper, not the prompt. It lists 31 of them across 7 tabs; the agent records each one's execution, evidence, result and signoff.
| Procedure | Assertions | Tab | |
|---|---|---|---|
| 1. | Obtain the cash lead sheet and agree the total to the trial balance and general ledger. | Completeness; Classification | <.1> |
| 6. | Send direct bank confirmations for ALL accounts using the full AICPA / Confirmation.com standard form covering balances, loans, lines of credit, facilities, guarantees and security interests. | Existence; Rights & Obligations; Completeness | <.2> |
| 13. | Test the reconciling items — deposits in transit, outstanding checks, transfers in transit and other items — to supporting documentation. | Valuation; Cutoff | <.3> |
| 20. | Review interaccount transfers around period-end, confirm both sides are recorded in the correct period, and prepare an inter-bank transfer (kiting) schedule. | Cutoff; Completeness | <.5> |
| 25. | Compute and disclose uninsured (above-FDIC) deposits. | Presentation & Disclosure | <.7> |
| 31. | All planned cash audit procedures above were performed; results support the recorded cash balance and related disclosures, subject to documented open items. | Overall | <.1>–<.7> |
| + 25 more procedures | |||
- Overall materiality
- $64,880
- Performance materiality
- $48,660
- Clearly trivial
- $3,244
- Sampling plan
- N/A
- 1Survey the binder
Lists every file in the workspace and reads each tab of the blank cash workpaper.
Turns 1–3 · find, openpyxl
Turn 1 · bashcd /workspace; find . -type f | head -100;
Output./planning/Materiality Memo.pdf ./planning/Cycle Materiality Allocation Register.pdf ./planning/Financial Audit Planning Inputs.pdf ./planning/Related Party Register.pdf ./planning/Engagement Calendar.pdf ./planning/Audit Selection Plan.pdf ./planning/Audit Planning Packet Index.pdf ./planning/Unadjusted Differences Register.pdf ./planning/Controls and IT-IPE Strategy.pdf ./planning/FSLI Scope Matrix.pdf ./planning/Significance Matrix.pdf ./planning/Engagement Scope and Case Facts.pdf ./planning/Significant and Fraud Risk Register.pdf ./planning/Assertion-Level Risk Assessment.pdf … 86 more lines
Turn 2 · bashcd /workspace; find . -type f | tail -n +101; find . -ipath '*cash*' -o -ipath '*bank*' cd /workspace; python3 -c " import openpyxl wb=openpyxl.load_workbook('cash_workpaper.xlsx') for ws in wb: print('=====',ws.title,ws.dimensions) for r in ws.iter_rows(): for c in r: if c.value is not None: print(c.coordinate,repr(c.value)) "Output./pbc_package/documents/payroll/Payroll Accrual Reconciliation 2025.pdf ./pbc_package/documents/payroll/Payroll Payment Detail 2025.xlsx ./pbc_package/documents/fixed_assets/Fixed Asset Impairment Assessment 2025.xlsx ./pbc_package/documents/bank_statements/MAY25 Payroll Stmt.pdf ./pbc_package/documents/bank_statements/DEC25 Payroll Stmt.pdf ./pbc_package/documents/bank_statements/JUL25 Payroll Stmt.pdf ./pbc_package/documents/bank_statements/FEB25 Operating Stmt.pdf ./pbc_package/documents/bank_statements/NOV25 Operating Stmt.pdf ./pbc_package/documents/bank_statements/FEB25 Payroll Stmt.pdf ./pbc_package/documents/bank_statements/JUL25 Operating Stmt.pdf ./pbc_package/documents/bank_statements/OCT25 Operating Stmt.pdf ./pbc_package/documents/bank_statements/AUG25 Payroll Stmt.pdf ./pbc_package/documents/bank_statements/SEP25 Operating Stmt.pdf ./pbc_package/documents/bank_statements/JAN26 Payroll Stmt.pdf … 781 more lines
Turn 3 · bashcd /workspace; python3 -c " import openpyxl wb=openpyxl.load_workbook('cash_workpaper.xlsx') print(wb.sheetnames) for ws in wb.worksheets[5:]: print('=====',ws.title,ws.dimensions) for r in ws.iter_rows(): for c in r: if c.value is not None: print(c.coordinate,repr(c.value)) "Output['Library Procedures', '<.1> Cash Lead Sheet', '<.2> Bank Confirmation', '<.3> Bank Reconciliation', '<.4> Outstanding Checks', '<.5> Cutoff Procedures', '<.6> Depository Fin Condition', '<.7> Presentation & Disclosure', 'Planning Context'] ===== <.5> Cutoff Procedures A1:I31 A1 'Cutoff Procedures' A2 'Client / Entity' B2 'Quelvox Industrial Holdings, LLC' D2 'Year-End' E2 datetime.datetime(2025, 12, 31, 0, 0) G2 'Currency' H2 'USD' A3 'Performance Materiality' B3 32500 D3 'Tolerable misstatement / testing threshold' E3 29300 A4 'Purpose:' … 186 more lines
- 2Read the planning file
Extracts the planning PDFs to text and pulls materiality, assessed risks and the selection plan.
Turns 4–10 · pdftotext, grep
Turn 4 · bashcd /workspace/planning; for f in *.pdf; do echo "=== $f"; pdftotext -layout "$f" - ; done > /tmp/planning.txt; wc -l /tmp/planning.txt; grep -n -i "cash\|WIN-\|bank" /tmp/planning.txt | head -150
Output2535 /tmp/planning.txt 149: Streams - Noncash Consideration none generated 289: Cash Existence Moderate Moderate Moderate No Substantive analytics and risk-calibrated detail testing 291: Cash Rights Moderate Moderate Moderate No Substantive analytics and risk-calibrated detail testing 293: Cash Completeness Moderate Moderate Moderate No Substantive analytics and risk-calibrated detail testing 295: Cash Accuracy Moderate Moderate Moderate No Substantive analytics and risk-calibrated detail testing 522:Payroll testing. Objective: Test employee compensation records and payroll cutoff. Population work: reconcile every payroll run to cash and the general ledger; analyze the full payroll-run 711: Cash Receipts Jan 2026.xlsx Accounts Receivable Passed Passed Not_Applicable Reliable 745: Disbursement Journal 2025.xlsx Cash Passed Passed Not_Applicable Reliable 747: Cash Account Listing and Reconciliations.xlsx Cash Failed Failed Not_Applicable Not Reliable 749: Cash Account Listing and Reconciliations.xlsx Cash Failed Failed Not_Applicable Not Reliable 751: Cash Account Listing and Reconciliations.xlsx Cash Failed Failed Not_Applicable Not Reliable 753: Cash Account Listing and Reconciliations.xlsx Cash Failed Failed Not_Applicable Not Reliable 755: Cash Account Listing and Reconciliations.xlsx Cash Failed Failed Not_Applicable Not Reliable … 28 more lines
Turn 5 · bashsed -n 690,830p /tmp/planning.txt; sed -n 920,1020p /tmp/planning.txt sed -n 1780,1830p /tmp/planning.txt; sed -n 1970,2000p /tmp/planning.txt; sed -n 2070,2110p /tmp/planning.txt; sed -n 2250,2290p /tmp/planning.txt
OutputCONTROLS AND IT-IPE STRATEGY REVIEWED BY: DATE: AUDIT STRATEGY Fully Substantive CONTROLS TESTED FOR RELIANCE 0 IPE REPORTS ASSESSED 90 IPE REPORTS CONCLUDED RELIABLE 78 A fully substantive response is required … 399 more lines
Turn 6 · bashgrep -n "^=== " /tmp/planning.txt
Output1:=== Accounting Policy Register.pdf
Turn 7 · bashcd /workspace/planning; for f in *.pdf; do echo "=== $f $(pdftotext -layout "$f" - | wc -l)"; done; pdftotext -layout "Engagement Scope and Case Facts.pdf" - | head -300
Output=== Accounting Policy Register.pdf 274 === Assertion-Level Risk Assessment.pdf 117 === Audit Planning Packet Index.pdf 51 === Audit Selection Plan.pdf 238 === Controls and IT-IPE Strategy.pdf 237 === Cycle Materiality Allocation Register.pdf 39 === Engagement Calendar.pdf 86 === Engagement Scope and Case Facts.pdf 35 === FSLI Scope Matrix.pdf 40 === Financial Audit Planning Inputs.pdf 613 === Materiality Memo.pdf 49 === Planned Procedure Register.pdf 170 === Procedure Window Register.pdf 90 === Related Party Register.pdf 15 … 39 more lines
Turn 8 · bashcd /workspace/planning; for f in "Audit Selection Plan.pdf" "Significant and Fraud Risk Register.pdf" "Related Party Register.pdf" "Unadjusted Differences Register.pdf" "Audit Planning Packet Index.pdf"; do echo "=== $f"; pdftotext -layout "$f" - | grep -v "^\s*$"; done
Output=== Audit Selection Plan.pdf Quelvox Industrial Holdings, LLC WORKPAPER REF. PL-ASP AUDIT PLANNING PREPARED BY: DATE: AUDIT SELECTION PLAN REVIEWED BY: DATE: Population analyzed is the number of records subjected to reconciliation or data analysis. It is not the number receiving detailed inspection. Detailed tests equal targeted items plus the residual sample. PROCEDURE SAMPLING UNIT POPULATION ANALYZED TARGETED RESIDUAL DETAIL REVIEW STATUS AP vouching Vendor Invoice 75 75 0 10 10 Within Guardrails Accrued expenses Accrual Category 1 1 1 0 1 Within Guardrails AR confirmations Customer Invoice Balance 83 83 0 6 6 Within Guardrails Inventory valuation Inventory Lot 21 21 0 15 15 Within Guardrails Fixed asset additions Fixed Asset 11 11 11 0 11 Within Guardrails Debt confirmations Debt Instrument 1 1 1 0 1 Within Guardrails Journal entry testing Journal Entry 1431 1431 35 9 44 Within Guardrails … 163 more lines
Turn 9 · bashcd /workspace/planning; for f in "Unadjusted Differences Register.pdf" "Audit Planning Packet Index.pdf" "FSLI Scope Matrix.pdf" "Materiality Memo.pdf"; do echo "=== $f"; pdftotext -layout "$f" - | grep -v "^\s*$"; done; pdftotext -layout "Financial Audit Planning Inputs.pdf" - | grep -v "^\s*$" | head -150
Output=== Unadjusted Differences Register.pdf Quelvox Industrial Holdings, LLC WORKPAPER REF. PL-UDR AUDIT PLANNING PREPARED BY: DATE: UNADJUSTED DIFFERENCES REGISTER REVIEWED BY: DATE: STATUS Pre-fieldwork AGGREGATE UNADJUSTED USD 0.00 DIFFERENCE No audit differences have been recorded at the planning stage. Differences identified during fieldwork must be added and evaluated by the auditor. PL-UDR | Audit planning workpaper Page 1 of 1 === Audit Planning Packet Index.pdf Quelvox Industrial Holdings, LLC WORKPAPER REF. PL-APPI AUDIT PLANNING PREPARED BY: DATE: AUDIT PLANNING PACKET INDEX REVIEWED BY: DATE: … 216 more lines
Turn 10 · bashcd /workspace/planning; pdftotext -layout "Financial Audit Planning Inputs.pdf" - | grep -v "^\s*$" | sed -n 150,400p
OutputPlanning input 16 | Tolerable and expected misstatement/error Value / assumption: Tolerable USD 32500.00; expected USD 1700.00 OWNER Auditor APPLICABILITY Applicable AVAILABILITY Provided APPLICATION Applied Planning input 17 | Projection of sample exceptions Value / assumption: ratio projection for monetary exceptions; exception-rate projection for attributes; investigate every qualitative exception OWNER Auditor APPLICABILITY Applicable AVAILABILITY Provided APPLICATION Applied ACCOUNTING POLICY Planning input 18 | Capitalization and depreciation policy … 122 more lines
- 3Pull the client's records
Reads the client's cash account listing, both trial balances and the chart of accounts.
Turns 11–13 · openpyxl
Turn 11 · bashcd /workspace/pbc_package; python3 -c " import openpyxl for f in ['documents/cash/Cash Account Listing and Reconciliations.xlsx','cash/Interbank Transfer Activity 2025.xlsx','Package Index.xlsx']: wb=openpyxl.load_workbook(f) for ws in wb: print('=====',f,ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) "Output===== documents/cash/Cash Account Listing and Reconciliations.xlsx Cash Account Listing A1:I7 ('Quelvox Industrial Holdings, LLC', None, None, None, None, None, None, None, None) ('Cash Account Listing', None, None, None, None, None, None, None, None) ('As of 2025-12-31', None, None, None, None, None, None, None, None) ('Institution', 'Account Name', 'Purpose', 'Account Number', 'Currency', 'Restriction', 'GL Account', 'Bank Balance', 'Book Balance') ('Veltford Trust', 'Operating Checking', 'Primary operating disbursements and receipts', '****0780', 'USD', 'Unrestricted', '1000 - Cash - operating', 3077758.05, 3077758.05) ('Veltford Trust', 'Payroll', 'Payroll clearing', '****4290', 'USD', 'Unrestricted', 'Clearing account', 0, 0) ===== documents/cash/Cash Account Listing and Reconciliations.xlsx Operating Checking Rec A1:B21 ('Quelvox Industrial Holdings, LLC', None) ('Operating Checking Bank Reconciliation', None) ('As of 2025-12-31', None) ('Reconciliation', 'Amount') ('Bank statement balance', 3077758.05) ('Add: deposits in transit', 0) … 124 more linesTurn 12 · bashcd /workspace/pbc_package; python3 -c " import openpyxl for f in ['Package Index.xlsx','foundational/TB 12 31 25.xlsx','foundational/TB 12 31 24.xlsx','foundational/Chart of Accounts.xlsx']: wb=openpyxl.load_workbook(f) for ws in wb: print('=====',f,ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) "; head -50 foundational/tb123125_export_12.csvOutput===== Package Index.xlsx Final Package Index A1:G172 ('Final File', 'Evidence Category', 'Purpose / Evidence Family', 'Version Status', 'Preparer', 'Reviewer', 'Package Date') ('direct_to_auditor/AR Auditor Evidence Control.xlsx', 'Package Control', 'AR Auditor Evidence Control', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/AR Confirmation - Quovixen Zaxburg Solutions Inc.pdf', 'Package Control', 'AR Confirmation - Quovixen Zaxburg Solutions Inc', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/AR Confirmation - Quoxmark Vorquex Services LLC.pdf', 'Package Control', 'AR Confirmation - Quoxmark Vorquex Services LLC', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/AR Confirmation - Zaxvento Quelvale Solutions Inc.pdf', 'Package Control', 'AR Confirmation - Zaxvento Quelvale Solutions Inc', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/Bank Confirmation 12.31.2025.pdf', 'Package Control', 'Bank Confirmation 12.31.2025', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/Inventory Count Observation 2025-12-31.pdf', 'Package Control', 'Inventory Count Observation 2025-12-31', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/Loan Confirmation 2025.pdf', 'Package Control', 'Loan Confirmation 2025', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/Audit Support Transmittal.docx', 'Package Control', 'Audit Support Transmittal', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/accounts_receivable/AR Aging 12 31 25.xlsx', 'Package Control', 'AR Aging 12 31 25', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/accounts_receivable/Allowance for Credit Losses 12 31 25.xlsx', 'Package Control', 'Allowance for Credit Losses 12 31 25', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/accounts_receivable/Cash Receipts Jan 2026.xlsx', 'Package Control', 'Cash Receipts Jan 2026', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/ap_and_accruals/2024 Accruals Paid in 2025.xlsx', 'Package Control', '2024 Accruals Paid in 2025', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) … 81 more linesTurn 13 · bashcd /workspace/pbc_package; python3 -c " import openpyxl for f in ['foundational/TB 12 31 25.xlsx','foundational/TB 12 31 24.xlsx','foundational/Chart of Accounts.xlsx']: wb=openpyxl.load_workbook(f) for ws in wb: print('=====',f,ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) " | head -150; echo; head -40 foundational/tb123125_export_12.csvOutput===== foundational/TB 12 31 25.xlsx TB 12 31 25 A1:D46 ('Quelvox Industrial Holdings, LLC', None, None, None) ('TB 12 31 25', None, None, None) ('As of December 31, 2025', None, None, None) ('Account', 'Name', 'Debit', 'Credit') ('1000', 'Cash - operating', 3077758.05, 0) ('1010', 'Accounts receivable - trade', 865294.35, 0) ('1011', 'Allowance for credit losses', 0, 71779.45) ('1014', 'Inventory in transit', 3800.4, 0) ('1015', 'Inventory', 0, 0) ('1016', 'Inventory - raw materials', 61784.27, 0) ('1017', 'Inventory - work in process', 36045.64, 0) ('1018', 'Inventory - finished goods', 29070.16, 0) ('1019', 'Reserve for excess and obsolete inventory', 0, 0) … 157 more lines - 4Read third-party evidence
Reads the bank confirmation, the loan confirmation and the executed loan agreement, and checks the confirmation PDF itself.
5 turns · pdftotext, pdfinfo, pdftoppm
Turn 14 · bashcd /workspace; pdftotext -layout "direct_to_auditor/Bank Confirmation 12.31.2025.pdf" -; pdfinfo "direct_to_auditor/Bank Confirmation 12.31.2025.pdf" | head -20
OutputVeltford Trust 6789 Commerce Lane, San Antonio, TX 78201 +1 (312) 555-0456 STANDARD FORM TO CONFIRM ACCOUNT BALANCE INFORMATION FORM DCF-100 / REV. 09/25 / CONTROL BNK-70B4C54AED Customer Quelvox Industrial Holdings, LLC Information as of 12/31/2025 CUSTOMER AUTHORIZATION We authorize the financial institution named above to disclose the information requested below to our independent auditors. R. Vixler Rebecca Vixler, Managing Member Authorization date: 12/09/2025 … 56 more linesTurn 15 · bashcd /workspace; pdftotext -layout "direct_to_auditor/Loan Confirmation 2025.pdf" -; pdftotext -layout "pbc_package/documents/debt/Debt Perfection Evidence Debt reference 001.pdf" -
OutputZarvale Bank Loan Servicing Department 01/19/2026 Hartwell & Vance, CPAs 412 Market Street, Suite 900, Philadelphia, PA 19106 RE: CONFIRMATION OF LOAN 993785604 To whom it may concern: At the request of our borrower, Quelvox Industrial Holdings, LLC, and their independent auditors, we … 70 more linesTurn 16 · bashcd /workspace/pbc_package/documents; pdftotext -layout "agreements/Quelvox Industrial - Loan Agreement 993785604 [EXECUTED].pdf" - | grep -v "^\s*$" | head -200
OutputLOAN AGREEMENT Zarvale Bank (Lender) and Quelvox Industrial Holdings, LLC (Borrower). Loan number 993785604 Agreement date 12/18/2024 Facility type Term loan Interest basis variable Payment frequency monthly Payment convention Monthly in arrears on the last calendar day of each interest period Maturity date 12/31/2042 Principal amount $378,132.14 Stated interest rate 6.00% Financial covenant Maximum loan-to-collateral ratio Requirement not greater than 65.00% Testing frequency annual … 105 more lines
Turn 24 · bashcd /tmp; pdftoppm -r 80 -png "/workspace/direct_to_auditor/Bank Confirmation 12.31.2025.pdf" bc; ls bc*
Outputbc-1.png
Turn 25 · bashcd /workspace/direct_to_auditor; pdfinfo "Bank Confirmation 12.31.2025.pdf" | head -8; python3 -c " import openpyxl wb=openpyxl.load_workbook('AR Auditor Evidence Control.xlsx') for ws in wb: print('==',ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) " | head -60OutputCustom Metadata: no Metadata Stream: no Tagged: no UserProperties: no Suspects: no Form: none JavaScript: no Pages: 1 Traceback (most recent call last): File "<string>", line 7, in <module> == Confirmation Control A1:Z8 ('Quelvox Industrial Holdings, LLC', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('Auditor-Controlled Accounts Receivable Evidence', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('As of 2025-12-31', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) … 57 more lines - 5Rebuild the balance from bank statements
Extracts opening and closing balances from all 26 monthly statements. December closes at $3,077,758.05.
4 turns · pdftotext, awk
Turn 17 · bashcd /workspace/pbc_package/documents; for f in "bank_statements/DEC25 Operating Stmt.pdf" "bank_statements/JAN26 Operating Stmt.pdf" "bank_statements/DEC25 Payroll Stmt.pdf" "bank_statements/JAN26 Payroll Stmt.pdf" "DEC25 Operating Rec.pdf" "cash/Deposit Insurance Coverage Reference 2025.pdf"; do echo "=== $f"; pdftotext -layout "$f" - | grep -v "^\s*$"; done
Output=== bank_statements/DEC25 Operating Stmt.pdf Veltford Trust 6789 Commerce Lane, San Antonio, TX 78201 Customer Service +1 (312) 555-0456 Member FDIC Account holder Quelvox Industrial Holdings, LLC Commercial Checking 9444600780 Statement Period December 01, 2025 through December 31, 2025 ACCOUNT SUMMARY INSTANCES AMOUNT Beginning Balance 2,619,622.85 Deposits and Additions 69 638,407.63 Checks Paid 0 0.00 Electronic Withdrawals 9 180,272.43 Ending Balance 3,077,758.05 … 199 more linesTurn 18 · bashcd /workspace/pbc_package/documents; for f in "bank_statements/DEC25 Payroll Stmt.pdf" "bank_statements/JAN26 Payroll Stmt.pdf" "DEC25 Operating Rec.pdf" "cash/Deposit Insurance Coverage Reference 2025.pdf"; do echo "=== $f"; pdftotext -layout "$f" - | grep -v "^\s*$" | grep -v -i "error\|funds\|business day\|amount you\|when contacting\|can why\|appeared\|law. Analysis\|have written\|complete schedule"; done
Output=== bank_statements/DEC25 Payroll Stmt.pdf V Veltford Trust 6789 Commerce Lane, San Antonio, TX 78201 Customer Service +1 (312) 555-0456 Member FDIC Account holder Quelvox Industrial Holdings, LLC Payroll Checking 6246934290 Statement Period December 01, 2025 through December 31, 2025 ACCOUNT SUMMARY INSTANCES AMOUNT Beginning Balance 0.00 Deposits and Additions 2 109,386.60 Checks Paid 0 0.00 Electronic Withdrawals 2 109,386.60 Ending Balance 0.00 … 102 more linesTurn 28 · bashcd /workspace/pbc_package/documents/bank_statements; for m in JAN25 FEB25 MAR25 APR25 MAY25 JUN25 JUL25 AUG25 SEP25 OCT25 NOV25 DEC25 JAN26; do for a in Operating Payroll; do echo -n "$m $a: "; pdftotext -layout "$m $a Stmt.pdf" - | grep -E "Beginning Balance|Ending Balance|Checks Paid |Deposits and Additions |Electronic Withdrawals " | awk '{print $NF}' | tr '\n' ' '; echo; done; doneOutputJAN25 Operating: 1,531,548.07 495,548.85 0.00 205,491.54 1,821,605.38 JAN25 Payroll: 0.00 109,386.60 0.00 109,386.60 0.00 FEB25 Operating: 1,821,605.38 261,710.03 0.00 178,406.43 1,904,908.98 FEB25 Payroll: 0.00 109,386.60 0.00 109,386.60 0.00 MAR25 Operating: 1,904,908.98 322,178.29 0.00 273,598.50 1,953,488.77 MAR25 Payroll: 0.00 109,386.60 0.00 109,386.60 0.00 APR25 Operating: 1,953,488.77 283,664.81 0.00 195,252.27 2,041,901.31 APR25 Payroll: 0.00 109,386.60 0.00 109,386.60 0.00 MAY25 Operating: 2,041,901.31 335,636.18 0.00 247,926.86 2,129,610.63 MAY25 Payroll: 0.00 109,386.60 0.00 109,386.60 0.00 JUN25 Operating: 2,129,610.63 296,376.49 0.00 209,138.71 2,216,848.41 JUN25 Payroll: 0.00 109,386.60 0.00 109,386.60 0.00 JUL25 Operating: 2,216,848.41 271,240.06 0.00 244,879.44 2,243,209.03 JUL25 Payroll: 0.00 109,386.60 0.00 109,386.60 0.00 … 12 more lines
Turn 29 · bashcd /workspace/pbc_package/documents/bank_statements; pdftotext -layout "DEC25 Operating Stmt.pdf" - | grep -E "^12/31 +ACH Credit" | awk '{gsub(",","",$NF); s+=$NF; n++} END{print n, s}'; for m in NOV25 OCT25; do pdftotext -layout "$m Operating Stmt.pdf" - | grep -E "ACH Credit" | awk -v m=$m '{print m, $1}' | sort | uniq -c | sort -rn | head -3; doneOutput26 203772 7 NOV25 11/26 4 NOV25 11/07 3 NOV25 11/17 8 OCT25 10/03 3 OCT25 10/28 3 OCT25 10/24 - 6Match interbank transfers
Matches each of the 24 scheduled transfers against both accounts' statements to check for kiting.
3 turns · openpyxl, pdftotext
Turn 19 · bashcd /workspace/pbc_package; python3 -c " import openpyxl for f in ['cash/Interbank Transfer Activity 2025.xlsx']: wb=openpyxl.load_workbook(f) for ws in wb: print('=====',f,ws.title,ws.dimensions) for r in list(ws.iter_rows(values_only=True))[20:]: if any(v is not None for v in r): print(r) "Output===== cash/Interbank Transfer Activity 2025.xlsx Interbank Transfer Schedule A1:H30 ('ACH726601666', datetime.datetime(2025, 8, 29, 0, 0), datetime.datetime(2025, 8, 29, 0, 0), datetime.datetime(2025, 8, 29, 0, 0), 'Operating Checking ****0780', 'Payroll ****4290', 54693.3, 'Karen Vovstein') ('ACH773357084', datetime.datetime(2025, 9, 12, 0, 0), datetime.datetime(2025, 9, 12, 0, 0), datetime.datetime(2025, 9, 15, 0, 0), 'Operating Checking ****0780', 'Payroll ****4290', 54693.3, 'Karen Vovstein') ('ACH286067802', datetime.datetime(2025, 9, 30, 0, 0), datetime.datetime(2025, 9, 30, 0, 0), datetime.datetime(2025, 9, 30, 0, 0), 'Operating Checking ****0780', 'Payroll ****4290', 54693.3, 'Karen Vovstein') ('ACH832760584', datetime.datetime(2025, 10, 15, 0, 0), datetime.datetime(2025, 10, 15, 0, 0), datetime.datetime(2025, 10, 15, 0, 0), 'Operating Checking ****0780', 'Payroll ****4290', 54693.3, 'Karen Vovstein') ('ACH156511302', datetime.datetime(2025, 10, 31, 0, 0), datetime.datetime(2025, 10, 31, 0, 0), datetime.datetime(2025, 10, 31, 0, 0), 'Operating Checking ****0780', 'Payroll ****4290', 54693.3, 'Karen Vovstein') ('ACH676255150', datetime.datetime(2025, 11, 12, 0, 0), datetime.datetime(2025, 11, 13, 0, 0), datetime.datetime(2025, 11, 14, 0, 0), 'Operating Checking ****0780', 'Payroll ****4290', 54693.3, 'Karen Vovstein') ('ACH347969381', datetime.datetime(2025, 11, 26, 0, 0), datetime.datetime(2025, 11, 26, 0, 0), datetime.datetime(2025, 11, 26, 0, 0), 'Operating Checking ****0780', 'Payroll ****4290', 54693.3, 'Karen Vovstein') ('ACH128405552', datetime.datetime(2025, 12, 15, 0, 0), datetime.datetime(2025, 12, 15, 0, 0), datetime.datetime(2025, 12, 15, 0, 0), 'Operating Checking ****0780', 'Payroll ****4290', 54693.3, 'Karen Vovstein') ('ACH957662248', datetime.datetime(2025, 12, 31, 0, 0), datetime.datetime(2025, 12, 31, 0, 0), datetime.datetime(2025, 12, 31, 0, 0), 'Operating Checking ****0780', 'Payroll ****4290', 54693.3, 'Karen Vovstein') ('Total', None, None, None, None, None, '=SUM(G6:G29)', None)Turn 31 · bashcd /workspace/pbc_package/documents/bank_statements; for m in JAN25 FEB25 MAR25 APR25 MAY25 JUN25 JUL25 AUG25 SEP25 OCT25 NOV25 DEC25 JAN26; do pdftotext -layout "$m Operating Stmt.pdf" - | grep -E "ZARVALE|EFTPS|CHECK #|Transfer" | sed "s/^/$m /"; done
OutputJAN25 01/15 Online Transfer to Payroll Chk ****4290 67857646 54,693.30 JAN25 01/22 ACH Debit EFTPS Tax Pymt 17686292 6,016.30 JAN25 01/31 PAYMENT ZARVALE BANK AUTODEBIT 2,866.86 JAN25 01/31 Online Transfer to Payroll Chk ****4290 00579479 54,693.30 FEB25 02/05 ACH Debit EFTPS Tax Pymt 72116034 6,016.26 FEB25 02/14 Online Transfer to Payroll Chk ****4290 39998022 54,693.30 FEB25 02/19 ACH Debit EFTPS Tax Pymt 65617138 5,985.86 FEB25 02/28 PAYMENT ZARVALE BANK AUTODEBIT 2,866.86 FEB25 02/28 Online Transfer to Payroll Chk ****4290 20828330 54,693.30 MAR25 03/05 ACH Debit EFTPS Tax Pymt 21341662 5,812.62 MAR25 03/14 Online Transfer to Payroll Chk ****4290 41649655 54,693.30 MAR25 03/19 ACH Debit EFTPS Tax Pymt 12524571 5,686.61 MAR25 03/31 PAYMENT ZARVALE BANK AUTODEBIT 2,866.86 MAR25 03/31 Online Transfer to Payroll Chk ****4290 55692139 54,693.30 … 45 more lines
Turn 35 · bashcd /workspace/pbc_package; python3 - <<'EOF' import openpyxl,subprocess,re wb=openpyxl.load_workbook('cash/Interbank Transfer Activity 2025.xlsx') ws=wb.active sched=[r for r in ws.iter_rows(min_row=5,values_only=True) if r[0] and r[0].startswith('ACH')] op=[];pr=[] for m in 'JAN25 FEB25 MAR25 APR25 MAY25 JUN25 JUL25 AUG25 SEP25 OCT25 NOV25 DEC25'.split(): t=subprocess.run(['pdftotext','-layout',f'documents/bank_statements/{m} Operating Stmt.pdf','-'],capture_output=True,text=True).stdout op+= re.findall(r'(\d\d/\d\d)\s+Online Transfer to Payroll',t) t=subprocess.run(['pdftotext','-layout',f'documents/bank_statements/{m} Payroll Stmt.pdf','-'],capture_output=True,text=True).stdout pr+= re.findall(r'(\d\d/\d\d)\s+Transfer from Operating',t) for s,o,p in zip(sched,op,pr): sd=s[2].strftime('%m/%d'); rd=s[3].strftime('%m/%d') flag='' if (sd==o and rd==p) else '<<' … 3 more linesOutputACH331839950 01/14 01/14 01/15 | bank op 01/15 payroll 01/15 << ACH752695401 01/31 01/31 01/31 | bank op 01/31 payroll 01/31 ACH054926251 02/14 02/14 02/14 | bank op 02/14 payroll 02/14 ACH746666345 02/28 02/28 02/28 | bank op 02/28 payroll 02/28 ACH677589709 03/13 03/13 03/14 | bank op 03/14 payroll 03/14 << ACH925245927 03/31 03/31 03/31 | bank op 03/31 payroll 03/31 ACH321200734 04/14 04/15 04/15 | bank op 04/15 payroll 04/15 ACH404595443 04/30 04/30 04/30 | bank op 04/30 payroll 04/30 ACH838433968 05/14 05/14 05/15 | bank op 05/15 payroll 05/15 << ACH015310009 05/30 05/30 05/30 | bank op 05/30 payroll 05/30 ACH678938867 06/13 06/13 06/13 | bank op 06/13 payroll 06/13 ACH328211105 06/30 06/30 06/30 | bank op 06/30 payroll 06/30 ACH570900938 07/14 07/14 07/15 | bank op 07/15 payroll 07/15 << ACH784030805 07/30 07/31 07/31 | bank op 07/31 payroll 07/31 … 11 more lines
- 7Test subsequent activity
Reviews January 2026 payments, receipts and payroll, plus the notes, balance sheet and cash flow statement.
6 turns · openpyxl, python-docx
Turn 20 · bashcd /workspace/pbc_package; python3 -c " import openpyxl for f in ['ap_and_accruals/Payments - January 2026.xlsx','accounts_receivable/Cash Receipts Jan 2026.xlsx']: wb=openpyxl.load_workbook(f) for ws in wb: print('=====',f,ws.title,ws.dimensions) for r in list(ws.iter_rows(values_only=True))[:40]: if any(v is not None for v in r): print(r) "Output===== ap_and_accruals/Payments - January 2026.xlsx Subsequent Disbursements A1:L11 ('Quelvox Industrial Holdings, LLC', None, None, None, None, None, None, None, None, None, None, None) ('Subsequent Disbursements', None, None, None, None, None, None, None, None, None, None, None) ('Report parameters: 2026-01-01 through 2026-03-01 (settlement date)', None, None, None, None, None, None, None, None, None, None, None) ('Payment ID', 'Payment Date', 'Bank Clearing Date', 'Method', 'Payment Reference', 'Payee', 'Invoice', 'Invoice Date', 'Receipt / Service Date', 'GL Account', 'Amount', 'Source Bank Account') ('Pay 2026 reference 001', datetime.datetime(2026, 1, 5, 0, 0), datetime.datetime(2026, 1, 6, 0, 0), 'ACH', 'ACH-2026000001', 'Vultixor Quorland Group, LLC', '453473', datetime.datetime(2025, 12, 3, 0, 0), datetime.datetime(2025, 12, 3, 0, 0), '2000', 7600.8, 'Operating Checking ****0780') ('Pay 2026 reference 002', datetime.datetime(2026, 1, 9, 0, 0), datetime.datetime(2026, 1, 12, 0, 0), 'ACH', 'ACH-2026000002', 'Quelvox Vultane Solutions, Inc.', '2025-0416', datetime.datetime(2025, 12, 3, 0, 0), datetime.datetime(2025, 12, 3, 0, 0), '2000', 15807.53, 'Operating Checking ****0780') ('Pay 2026 reference 003', datetime.datetime(2026, 1, 15, 0, 0), datetime.datetime(2026, 1, 16, 0, 0), 'Check', '41001', 'Quovixen Vorquix Services, LLC', 'QVS-10897', datetime.datetime(2025, 12, 3, 0, 0), datetime.datetime(2025, 12, 3, 0, 0), '2000', 18242.41, 'Operating Checking ****0780') ('Pay 2026 reference 004', datetime.datetime(2026, 1, 16, 0, 0), datetime.datetime(2026, 1, 20, 0, 0), 'ACH', 'ACH-2026000004', 'Vultixor Quorland Group, LLC', 'VQ-202601-01', datetime.datetime(2026, 1, 10, 0, 0), datetime.datetime(2025, 12, 26, 0, 0), '2000', 3800.4, 'Operating Checking ****0780') ('Pay 2026 reference 005', datetime.datetime(2026, 1, 23, 0, 0), datetime.datetime(2026, 1, 26, 0, 0), 'ACH', 'ACH-2026000005', 'Quexford Quotane Holdings, Inc.', '92123', datetime.datetime(2025, 12, 3, 0, 0), datetime.datetime(2025, 12, 3, 0, 0), '2000', 19523.94, 'Operating Checking ****0780') ('Total', 5, None, None, None, None, None, None, None, None, '=SUM(K6:K10)', None) ===== ap_and_accruals/Payments - January 2026.xlsx Bank Debit Control A1:J23 ('Quelvox Industrial Holdings, LLC', None, None, None, None, None, None, None, None, None) ('Bank Debit Control', None, None, None, None, None, None, None, None, None) … 72 more linesTurn 21 · bashcd /workspace/pbc_package/documents; pdftotext -layout "payroll/Subsequent Payroll Report 2026.pdf" - | grep -v "^\s*$" | head -60; python3 -c " import openpyxl wb=openpyxl.load_workbook('Disbursement Journal 2025.xlsx') for ws in wb: rows=list(ws.iter_rows(values_only=True)) print(ws.title,ws.dimensions) for r in rows[:6]+rows[-15:]: print(r) "OutputSUBSEQUENT PAYROLL AND ACCRUAL REVERSAL REPORT Quelvox Industrial Holdings, LLC First payroll following 12/31/2025 Source year-end payroll run Pr 2025 reference 024 Subsequent payroll period 01/01/2026 through 01/15/2026 Subsequent payment date 01/15/2026 Subsequent regular payroll gross 54,693.30 Subsequent payroll net payment 54,693.30 Year-end earned-but-unpaid wage accrual reversed 0.00 Accrual reversal reference N/A-zero-earned-unpaid-days Payroll bank/EFT reference EFT-SUBSEQ-PAYROLL-01-NET Subsequent register reference SUBSEQ-PAYROLL-REGISTER-01 YEAR-END LIABILITY SETTLEMENTS Source run Type Settlement Amount Bank / EFT reference Return / provider reference … 27 more linesTurn 22 · bashcd /workspace/pbc_package; python3 -c " import docx d=docx.Document('Audit Support Transmittal.docx') for p in d.paragraphs: if p.text.strip(): print(p.text) for t in d.tables: for r in t.rows: print([c.text for c in r.cells]) "; pdftotext -layout "documents/Audited Financial Statements 12.31.2024.pdf" - | grep -v "^\s*$" | grep -i -B2 -A2 "cash\|fdic\|insur\|concentrat\|pledg\|collateral" | head -80OutputAudit Support Transmittal Quelvox Industrial Holdings, LLC Year ended December 31, 2025 Attached please find the requested schedules and support for the areas below: Accounts payable and accruals Accounts receivable Cash Debt Equity Fixed assets Inventory Journal entries Payroll Prepaid expenses … 32 more lines
Turn 23 · bashcd /workspace/pbc_package/documents; python3 -c " import openpyxl for f in ['Notes to Financial Statements.xlsx','Balance Sheet.xlsx']: wb=openpyxl.load_workbook(f) for ws in wb: print('=====',f,ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) "Output===== Notes to Financial Statements.xlsx Notes to Financial Statements A1:B98 ('Quelvox Industrial Holdings, LLC', None) ('Notes to Financial Statements', None) ('Report parameters: 2026-01-01 through 2026-03-01 (event date)', None) ('Note 1 — Organization and basis of presentation', None) ('The accompanying statements are management-prepared, accrual-basis financial statements for the year ended December 31, 2025.', None) ('Note 2 — Significant accounting policies', None) ('Cash equivalents include demand deposits and money-market balances available for current operations.', None) ('Raw material, work in process, and finished goods are stated at the lower of FIFO cost and net realizable value.', None) ('FIFO cost includes dated supplier layers and documented direct labor and production overhead incurred at each conversion stage.', None) ('Revenue is recognized when finished goods ship under the applicable customer terms.', None) ('Note 3 — Balance-sheet detail', 'December 31 balance') ('Cash and cash equivalents', 3077758.05) ('Gross receivables', 865294.35) … 96 more linesTurn 30 · bashcd /workspace/pbc_package/documents; python3 -c " import openpyxl for f in ['Statement of Cash Flows.xlsx']: wb=openpyxl.load_workbook(f) for ws in wb: for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) "Output('Quelvox Industrial Holdings, LLC', None) ('Statement of Cash Flows', None) ('For the year ended December 31, 2025', None) ('Operating activities', 1558251.95) ('Investing activities', 0) ('Financing activities', -12041.97) ('Net increase (decrease) in cash', 1546209.98) ('Cash at beginning of year', 1531548.07) ('Cash at end of year', '=B9+B8') ('Cash-flow statement ending cash', 3077758.05)Turn 32 · bashcd /workspace/pbc_package; python3 -c " import openpyxl wb=openpyxl.load_workbook('ap_and_accruals/AP Aging (2025-12-31).xlsx') for ws in wb: print(ws.title) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) " | head -30OutputTraceback (most recent call last): File "<string>", line 7, in <module> BrokenPipeError: [Errno 32] Broken pipe AP-to-GL Reconciliation ('Quelvox Industrial Holdings, LLC', None, None, None, None) ('AP-to-GL Reconciliation', None, None, None, None) ('As of December 31, 2025', None, None, None, None) ('Account', 'Subledger', 'GL Balance (Credit)', 'Difference', 'Conclusion') ('2000', 61174.68, -61174.68, '=B6+C6', 'Reconciled') AP Aging Detail ('Quelvox Industrial Holdings, LLC', None, None, None, None, None, None, None, None, None, None) ('AP Aging Detail', None, None, None, None, None, None, None, None, None, None) ('As of December 31, 2025', None, None, None, None, None, None, None, None, None, None) ('Line', 'Vendor', 'Invoice', 'Invoice Date', 'Due Date', 'Original Amount', 'Open Balance', 'Aging Bucket', 'GL Account', 'PO Number', 'Support Status') … 19 more lines - 8Search for unlisted accounts
Scans every spreadsheet in the binder for bank accounts missing from the client's listing.
Turns 26–27 · openpyxl, re
Turn 26 · bashcd /workspace; for f in $(find pbc_package direct_to_auditor -name "*.xlsx"); do python3 - "$f" <<'EOF' import openpyxl,sys wb=openpyxl.load_workbook(sys.argv[1]) for ws in wb: for r in ws.iter_rows(): for c in r: if isinstance(c.value,str) and ('Bank account 00' in c.value or 'lockbox' in c.value.lower() or 'money market' in c.value.lower() or 'savings' in c.value.lower() or 'reserve' in c.value.lower() and 'cash' in c.value.lower()): print(sys.argv[1],ws.title,c.coordinate,c.value[:200]) EOF done; for f in $(find pbc_package direct_to_auditor -name "*.pdf"); do pdftotext "$f" - 2>/dev/null | grep -i -H --label="$f" "Bank account 00\|lockbox\|money.market\|savings\|sweep" ; doneOutputTraceback (most recent call last): File "<stdin>", line 2, in <module> File "/usr/local/lib/python3.12/site-packages/openpyxl/reader/excel.py", line 346, in load_workbook reader = ExcelReader(filename, read_only, keep_vba, ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "/usr/local/lib/python3.12/site-packages/openpyxl/reader/excel.py", line 123, in __init__ self.archive = _validate_archive(fn) ^^^^^^^^^^^^^^^^^^^^^ File "/usr/local/lib/python3.12/site-packages/openpyxl/reader/excel.py", line 93, in _validate_archive raise InvalidFileException(msg) openpyxl.utils.exceptions.InvalidFileException: openpyxl does not support file format, please check you can open it with Excel first. Supported formats are: .xlsx,.xlsm,.xltx,.xltm Traceback (most recent call last): File "<stdin>", line 2, in <module> File "/usr/local/lib/python3.12/site-packages/openpyxl/reader/excel.py", line 346, in load_workbook … 285 more linesTurn 27 · bashcd /workspace; python3 - <<'EOF' import openpyxl,glob,re pat=re.compile(r'Bank account 00|lockbox|money.market|savings|sweep|Bank account 002',re.I) for f in glob.glob('pbc_package/**/*.xlsx',recursive=True)+glob.glob('direct_to_auditor/*.xlsx'): wb=openpyxl.load_workbook(f) for ws in wb: for r in ws.iter_rows(): for c in r: if isinstance(c.value,str) and pat.search(c.value): print(f,ws.title,c.coordinate,c.value[:150]) EOF find pbc_package direct_to_auditor -name "*.pdf" -print0 | while IFS= read -r -d '' f; do pdftotext "$f" - 2>/dev/null | grep -i -H --label="$f" "Bank account 00\|lockbox\|money.market\|savings\|sweep"; done | sort | uniq -c | head -30Outputpbc_package/documents/Notes to Financial Statements.xlsx Notes to Financial Statements A9 Cash equivalents include demand deposits and money-market balances available for current operations. pbc_package/documents/cash/Cash Account Listing and Reconciliations.xlsx Deposit Insurance Coverage E6 Bank account 001, Bank account 003 pbc_package/documents/cash/Cash Account Listing and Reconciliations.xlsx P&D Procedure Register B12 Merchant clearing / lockbox pbc_package/documents/cash/Cash Account Listing and Reconciliations.xlsx P&D Procedure Register D12 0 merchant/lockbox/clearing account record(s) pbc_package/documents/cash/Cash Account Listing and Reconciliations.xlsx P&D Procedure Register F12 Reconcile merchant or lockbox clearing where applicable. pbc_package/documents/cash/Cash Account Listing and Reconciliations.xlsx Kiting Cutoff Population F6 Bank account 001 pbc_package/documents/cash/Cash Account Listing and Reconciliations.xlsx Kiting Cutoff Population G6 Bank account 003 pbc_package/documents/cash/Cash Account Listing and Reconciliations.xlsx Kiting Cutoff Population F7 Bank account 001 pbc_package/documents/cash/Cash Account Listing and Reconciliations.xlsx Kiting Cutoff Population G7 Bank account 003 pbc_package/documents/cash/Cash Account Listing and Reconciliations.xlsx Kiting Cutoff Population F8 Bank account 001 pbc_package/documents/cash/Cash Account Listing and Reconciliations.xlsx Kiting Cutoff Population G8 Bank account 003 pbc_package/documents/cash/Cash Account Listing and Reconciliations.xlsx Kiting Cutoff Population F9 Bank account 001 pbc_package/documents/cash/Cash Account Listing and Reconciliations.xlsx Kiting Cutoff Population G9 Bank account 003 pbc_package/documents/cash/Cash Account Listing and Reconciliations.xlsx Kiting Cutoff Population F10 Bank account 001 … 39 more lines
- 9Fill and verify the workpaper
Writes the procedures, evidence citations and open issues, then recalculates in LibreOffice to check the totals.
4 turns · openpyxl, libreoffice
Turn 33 · bashcd /workspace; python3 -c " import openpyxl wb=openpyxl.load_workbook('cash_workpaper.xlsx') for ws in wb: print(ws.title, ws.data_validations.dataValidation[:5] if ws.data_validations else None, ws.merged_cells.ranges) ws=wb['Library Procedures'] print(ws['A7'].font.name, ws['A7'].alignment.wrap_text, ws.column_dimensions['Q'].width) "OutputLibrary Procedures [<openpyxl.worksheet.datavalidation.DataValidation object> Parameters: sqref=<MultiCellRange [A7 A8 A9 A10 A11 A13 A14 A15 A16 A17 A19 A20 A21 A22 A24 A25 A26 A28 A29 A30 A31 A33 A34 A36 A37 A38 A39 A40 A42 A43 A45]>, showDropDown=False, showInputMessage=False, showErrorMessage=False, allowBlank=False, errorTitle=None, error=None, promptTitle=None, prompt=None, type='list', errorStyle=None, imeMode=None, operator=None, formula1='"Applicable,Not Applicable - Fact Driven"', formula2=None, <openpyxl.worksheet.datavalidation.DataValidation object> Parameters: sqref=<MultiCellRange [B7 B8 B9 B10 B11 B13 B14 B15 B16 B17 B19 B20 B21 B22 B24 B25 B26 B28 B29 B30 B31 B33 B34 B36 B37 B38 B39 B40 B42 B43 B45]>, showDropDown=False, showInputMessage=False, showErrorMessage=False, allowBlank=False, errorTitle=None, error=None, promptTitle=None, prompt=None, type='list', errorStyle=None, imeMode=None, operator=None, formula1='"Required,Recommended"', formula2=None, <openpyxl.worksheet.datavalidation.DataValidation object> Parameters: sqref=<MultiCellRange [C7 C8 C9 C10 C11 C13 C14 C15 C16 C17 C19 C20 C21 C22 C24 C25 C26 C28 C29 C30 C31 C33 C34 C36 C37 C38 C39 C40 C42 C43 C45]>, showDropDown=False, showInputMessage=False, showErrorMessage=False, allowBlank=False, errorTitle=None, error=None, promptTitle=None, prompt=None, type='list', errorStyle=None, imeMode=None, operator=None, formula1='"Not Started,In Progress,Performed,Not Performed"', formula2=None, <openpyxl.worksheet.datavalidation.DataValidation object> Parameters: sqref=<MultiCellRange [D7 D8 D9 D10 D11 D13 D14 D15 D16 D17 D19 D20 D21 D22 D24 D25 D26 D28 D29 D30 D31 D33 D34 D36 D37 D38 D39 D40 D42 D43 D45]>, showDropDown=False, showInputMessage=False, showErrorMessage=False, allowBlank=False, errorTitle=None, error=None, promptTitle=None, prompt=None, type='list', errorStyle=None, imeMode=None, operator=None, formula1='"Sufficient,Missing,Unreadable,Unreliable,Contradictory,Not Required"', formula2=None, <openpyxl.worksheet.datavalidation.DataValidation object> Parameters: sqref=<MultiCellRange [E7 E8 E9 E10 E11 E13 E14 E15 E16 E17 E19 E20 E21 E22 E24 E25 E26 E28 E29 E30 E31 E33 E34 E36 E37 E38 E39 E40 E42 E43 E45]>, showDropDown=False, showInputMessage=False, showErrorMessage=False, allowBlank=False, errorTitle=None, error=None, promptTitle=None, prompt=None, type='list', errorStyle=None, imeMode=None, operator=None, formula1='"No Exception,Exception Identified,Unable to Conclude"', formula2=None] {<MergedCellRange I6:Q6>, <MergedCellRange I32:Q32>, <MergedCellRange I41:Q41>, <MergedCellRange A3:Q3>, <MergedCellRange I27:Q27>, <MergedCellRange I23:Q23>, <MergedCellRange I18:Q18>, <MergedCellRange I44:Q44>, <MergedCellRange I35:Q35>, <MergedCellRange I12:Q12>} <.1> Cash Lead Sheet None {<MergedCellRange A37:J37>, <MergedCellRange B6:J6>, <MergedCellRange B5:J5>, <MergedCellRange B4:J4>} <.2> Bank Confirmation None {<MergedCellRange B4:R4>, <MergedCellRange B19:D19>, <MergedCellRange B23:D23>, <MergedCellRange A16:R16>, <MergedCellRange B22:D22>, <MergedCellRange B6:R6>, <MergedCellRange B21:D21>, <MergedCellRange A27:R27>, <MergedCellRange B25:D25>, <MergedCellRange B5:R5>, <MergedCellRange B24:D24>, <MergedCellRange B20:D20>} <.3> Bank Reconciliation None {<MergedCellRange B4:L4>, <MergedCellRange A16:L16>, <MergedCellRange B19:D19>, <MergedCellRange B6:L6>, <MergedCellRange B23:D23>, <MergedCellRange B22:D22>, <MergedCellRange B5:L5>, <MergedCellRange B21:D21>, <MergedCellRange A27:L27>, <MergedCellRange B25:D25>, <MergedCellRange B24:D24>, <MergedCellRange B20:D20>} … 6 more linesTurn 34 · bashcd /workspace; python3 -c " import openpyxl wb=openpyxl.load_workbook('cash_workpaper.xlsx') ws=wb['Library Procedures'] for dv in ws.data_validations.dataValidation: print(str(dv.sqref)[:10], dv.formula1) "OutputA7 A8 A9 A "Applicable,Not Applicable - Fact Driven" B7 B8 B9 B "Required,Recommended" C7 C8 C9 C "Not Started,In Progress,Performed,Not Performed" D7 D8 D9 D "Sufficient,Missing,Unreadable,Unreliable,Contradictory,Not Required" E7 E8 E9 E "No Exception,Exception Identified,Unable to Conclude" F7 F8 F9 F "None,Open,Adjusted,Passed,Resolved,Superseded" G7 G8 G9 G "Unsigned,Prepared,Reviewed,Superseded"
Turn 36 · bashmkdir -p /tmp/w && cat > /tmp/w/fill.py <<'EOF' import openpyxl, datetime as dt, copy from openpyxl.styles import Alignment, Font wb=openpyxl.load_workbook('/workspace/cash_workpaper.xlsx') D=dt.datetime(2026,1,23) PREP='Audit Senior B377' wrap=Alignment(wrap_text=True, vertical='top') # ---------- materiality per Planning Context for n in wb.sheetnames[1:8]: ws=wb[n]; ws['B3']=48660; ws['E3']=48660 ws['B3'].number_format='#,##0'; ws['E3'].number_format='#,##0' EV={ … 280 more linesOutputsaved
Turn 37 · bashcd /tmp/w && rm -rf out && libreoffice --headless --convert-to xlsx --outdir out /workspace/cash_workpaper.xlsx >/dev/null 2>&1; python3 -c " import openpyxl wb=openpyxl.load_workbook('out/cash_workpaper.xlsx',data_only=True) for s,cells in [('<.1> Cash Lead Sheet',['H9','I9','F19','G19','H19','B24','C24','B26','C26','B27']),('<.2> Bank Confirmation',['H9','H10','F14','G14','H14']),('<.3> Bank Reconciliation',['J9','K9','J10','K10','K14']),('<.4> Outstanding Checks',['C31']),('<.6> Depository Fin Condition',['D9']),('<.7> Presentation & Disclosure',['E10','E20','E21','E25'])]: print(s,[ (c,wb[s][c].value) for c in cells]) "Output<.1> Cash Lead Sheet [('H9', 1546209.98), ('I9', 1.00957326138643), ('F19', 3077758.05), ('G19', 1531548.07), ('H19', 1546209.98), ('B24', 3077758.05), ('C24', 1531548.07), ('B26', 0), ('C26', 0), ('B27', 2827758.05)] <.2> Bank Confirmation [('H9', 0), ('H10', 0), ('F14', 3077758.05), ('G14', 3077758.05), ('H14', 0)] <.3> Bank Reconciliation [('J9', 3077758.05), ('K9', 0), ('J10', 0), ('K10', 0), ('K14', 0)] <.4> Outstanding Checks [('C31', 122426.95)] <.6> Depository Fin Condition [('D9', 2827758.05)] <.7> Presentation & Disclosure [('E10', 2827758.05), ('E20', 2827758.05), ('E21', 0), ('E25', 2827758.05)]
The completed workpaper, tab by tab. Highlighted cells were graded.
Summarize the cash population and tie the recorded balance to the trial balance; compute CY/PY movement and uninsured exposure.
| Account | Description | Bank | CY balance | PY balance | Change |
|---|---|---|---|---|---|
| 1000 | Cash – operating (Operating Checking) | Veltford Trust ****0780 | 3,077,758.05 | 1,531,548.07 | 1,546,209.98 |
| n/a – no GL (ZBA) | Payroll checking – zero-balance payroll funding account | Veltford Trust ****4290 | 0.00 | 0.00 | 0.00 |
| 3,077,758.05 | 1,531,548.07 | 1,546,209.98 |
Confirm balances and facilities directly with depositories, control the confirmation process, follow up on non-responses, and test the authenticity of confirmations.
| Account | Bank | Per GL | Per confirmation | Follow-up | Response |
|---|---|---|---|---|---|
| ****0780 | Veltford Trust | 3,077,758.05 | 3,077,758.05 | Not evidenced (PL-EC planned 12/24/2025) | Y – received 01/08/2026 (bank completed 01/02/2026) |
| ****4290 | Veltford Trust | 0.00 | 0.00 | Not evidenced (PL-EC planned 12/24/2025) | Y – received 01/08/2026 |
| Loan 993785604 | Zarvale Bank | Not required | Y – received 01/19/2026 | ||
| 3,077,758.05 | 3,077,758.05 |
Test each account's year-end bank reconciliation: agree the bank balance and book balance, test the reconciling items, and recompute.
| Bank | GL | Per bank | Deposits in transit | Outstanding checks | Reconciled | Difference |
|---|---|---|---|---|---|---|
| Veltford Trust ****0780 | 3,077,758.05 | 3,077,758.05 | 0.00 | 0.00 | 3,077,758.05 | 0.00 |
| Veltford Trust ****4290 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
| 3,077,758.05 | 3,077,758.05 | 0.00 | 0.00 | 3,077,758.05 | 0.00 |
Test outstanding checks in two directions: existence (list → bank statement) on a sample basis, and completeness (bank statement → list) for at least 5–10 items regardless of population.
| Cleared in January | Cleared | Amount | On YE list | Proper period | Comments |
|---|---|---|---|---|---|
CHECK # 41001 – Quovixen Vorquix Services, LLC | 2026-01-16 | 18,242.41 | N | Y | Check dated 01/15/2026 (Pay 2026 ref 003) paying inv QVS-10897 carried in YE AP; ISI item (>16,300). Properly a 2026 disbursement. |
ACH – Zarvale Bank autodebit | 2026-01-02 | 2,866.86 | N | Y | 2026 debt service; loan confirmation: interest paid through 12/31/2025, accrued 0.00. |
ACH Payment – Vultixor Quorland Group, LLC | 2026-01-06 | 7,600.80 | N | Y | Initiated 01/05/2026 (Pay 2026 ref 001); inv 453473 in YE AP. |
ACH Payment – Quelvox Vultane Solutions, Inc. | 2026-01-12 | 15,807.53 | N | Y | Initiated 01/09/2026 (ref 002); inv 2025-0416 in YE AP. |
Online transfer to Payroll ****4290 | 2026-01-16 | 54,585.01 | N | Y | 2026 payroll funding. Amount/date conflict with payroll stmt (01/15/2026, 54,693.30) – CASH-ISS-04. |
Total January 2026 debits tested (100% of population, EV-08 / EV-12) | 122,426.95 | Agrees to Jan26 statement debits 122,426.95 (1 check 18,242.41 + 6 electronic 104,184.54). No 2025-issued item cleared in January; O/S list completeness supported. |
Obtain the complete subsequent-period cutoff bank statement and test that period-end reconciling items and interaccount transfers are recorded in the proper period.
| Procedure | Date | Amount | Result | Comments |
|---|---|---|---|---|
| Outstanding check cutoff | 2025-12-31 | 0.00 | No Exception | Nil O/S checks at YE (EV-10). Only check clearing in Jan (#41001, 18,242.41, cleared 01/16/2026) is dated 01/15/2026 – 2026 item. See <.4>. |
| Deposit-in-transit cutoff | 2025-12-31 | 0.00 | No Exception | No DIT. All December receipts credited by bank by 12/31 (26 credits 203,772.00 on 12/31); zero deposits in Jan 2026. Unusual Dec volume referred to Revenue/AR cutoff (CASH-REF-01). |
| Interaccount transfer cutoff (both sides) | 2025-12-31 | 54,693.30 | No Exception | ACH957662248: debit operating 12/31 and credit payroll 12/31 (EV-07); ACH128405552 12/15 both sides. No transfer in transit. |
| Inter-bank transfer / kiting schedule | 2025-12-31 | 1,312,639.20 | No Exception | 24 transfers x 54,693.30 (EV-11) traced to both statements. YE-window: 12/15 and 12/31 same-day both sides -> no float/kiting. 6 transfers (Jan, Mar, May, Jul, Sep, Nov) show schedule sending date 1-3 days before bank debit date; intra-month only, no YE effect. |
| Interaccount transfer cutoff (January payroll funding) | 2026-01-16 | 54,585.01 | Exception Identified | Interaccount transfer (January): operating stmt debit 01/16/2026 54,585.01 vs payroll stmt credit 01/15/2026 54,693.30 and net pay 54,693.30 (EV-13). Difference 108.29 and 1 day; contradictory bank documents – obtain bank-direct statements/online access (CASH-ISS-04). |
| Subsequent-period activity scan (payroll tax settlement) | 2026-01-07 | 4,183.97 | Exception Identified | Subsequent-period scan: YE payroll withholdings 4,183.97 reported settled 01/07/2026 (EFT-PAYROLL-24-TAX, EV-13) – not on either Jan statement; second Jan payroll (~01/30/2026) also not observed. Possible unlisted account or inaccurate report (CASH-ISS-05). |
Assess the financial condition / creditworthiness of each depository, especially where uninsured balances are significant, and evaluate recoverability and concentration risk.
| Bank | Balance | Uninsured | Credit rating | Risk assessment |
|---|---|---|---|---|
| Veltford Trust (Member FDIC per statements) | 3,077,758.05 | 2,827,758.05 | Not obtained | Elevated – 100% concentration, 2,827,758.05 uninsured (58x PM) |
Document cash presentation/disclosure matters: concentration, uninsured deposits, restricted/pledged cash, classification, overdrafts, compensating balances and merchant/lockbox accounts.
| Area | Amount | Conclusion |
|---|---|---|
| Bank concentration | 3,077,758.05 | Evaluated – 100% of cash at 1 institution; disclosed in Note 8. Credit-risk wording to be re-assessed after CASH-ISS-01. |
| Uninsured deposits (FDIC) | 2,827,758.05 | Recomputed 2,827,758.05 agrees to Note 8 "estimated deposits above the standard coverage limit: 2827758.05". No difference. |
| Pledged / restricted cash | 0.00 | No restricted cash. Cash falls within Zarvale blanket lien (all business assets / proceeds) but no control agreement, hold or escrow – available for operations; classified unrestricted. Blanket lien disclosed in Note 4; recommend cross-reference in Note 8. |
| Bank overdrafts (reclassify) | 0.00 | None – no negative YE balances; no reclassification to liabilities. |
| Compensating balances | 0.00 | None – agreement silent; corroborated on controlled bank form (Veltford sec. 4 none reported). Lender full-form corroboration pending CASH-ISS-03. |
Agent’s closing summary
I've completed the cash workpaper and saved it to /workspace/cash_workpaper.xlsx. The year-end cash balance of $3,077,758.05 ties out with no misstatement found, but I haven't signed off the overall conclusion (procedure 31) because five issues are still open. Formulas recalculate without errors when the file is opened in LibreOffice. Preparer is Audit Senior B377; the Audit Manager 4104 review sign-off is still blank.
What ties out
- Balance: $3,077,758.05 agrees across the trial balance, the balance sheet, the cash flow statement, the notes, the Veltford Trust bank confirmation and the December bank statement. The prior year of $1,531,548.07 agrees to the prior-year audited statements.
- Movement: cash rose $1,546,209.98 (+101%), which matches the net increase on the cash flow statement.
- Reconciliation: there are no reconciling items. The client's cash listing and reconciliations were assessed as not reliable at planning, so I rebuilt every figure from bank statements, the confirmation and the trial balance.
- Uninsured deposits: $2,827,758.05 ($3,077,758.05 less the $250,000 FDIC limit, applied once for the single institution). This matches the note disclosure.
- Outstanding checks and cutoff: there were no outstanding checks at year end, so the existence test is marked not applicable. I tested all 7 January debits ($122,426.95) instead; none were issued in 2025. The year-end transfers between the operating and payroll accounts were recorded on both sides the same day, with no sign of kiting.
- Restricted cash, overdrafts, compensating balances: none. Cash falls under the lender's blanket lien but isn't restricted. I recommend the cash note cross-reference the lien, which is already disclosed in the debt note.
- Not applicable: merchant/lockbox reconciliation (no such accounts) and non-response follow-up (both confirmations came back).
Open issues
- CASH-ISS-01 – Bank financial condition: there's no evidence on Veltford Trust's financial condition, yet 92% of cash is uninsured at that one bank. Procedures 22–23 are marked unable to conclude.
- CASH-ISS-02 – Confirmation control: nothing on file shows the bank's address was checked independently or that the 12/24 follow-up was sent. The bank's phone number (Chicago area code, San Antonio address) is copied from the client's statements rather than sourced independently. The Zarvale Bank loan confirmation came by email with no sender-domain check or independent call-back.
- CASH-ISS-03 – Lender form: Zarvale Bank, the lender, only sent a loan letter. It hasn't been sent the full standard bank confirmation form.
- CASH-ISS-04 – Conflicting January statements: the operating statement shows the payroll transfer as $54,585.01 on 01/16. The payroll statement shows $54,693.30 on 01/15. The $108.29 gap is trivial, but two of the client's bank statements contradict each other.
- CASH-ISS-05 – Possible unlisted account: the $4,183.97 payroll tax payment reported as made on 01/07/2026 doesn't appear on either January statement, and the second January payroll is also missing. There may be a bank account that isn't on the listing.
I also referred one item to the Revenue/AR team (CASH-REF-01). December deposits were about twice the monthly average, with $203,772 credited on 12/31, followed by no deposits at all in January. This doesn't affect the cash balance, since the bank confirmed it.
Other changes to the template
- Materiality: I replaced the template's $32,500 / $29,300 with $48,660 for both performance materiality and tolerable misstatement, per the Planning Context tab.
- New Evidence Index tab: it lists the source evidence (EV-01 to EV-20) and the issue log that the procedure citations point to.
- Extra rows: two January exception rows on the cutoff tab, the Zarvale Bank loan on the confirmation tab, and total rows on the outstanding-checks and disclosure tabs.
- Unchanged: all columns, headers and the existing procedure and window references (PROC:, WINDOW:). I also added SAMPLE:SAMPLE-CASH (the sampling plan ID from the Planning Context tab) to the two outstanding-check tests (procedures 15–16).
Graded by the released grader: exact checks on key balances, and a GPT-5.6 Luna judge where equivalent answers are allowed. A task passes only if every criterion does.
Amounts are rightKey balances and dates agree to the evidence.7/7
- Tie operating cash to the trial balancePassed
The lead sheet records $3,077,758.05 for operating cash (GL 1000), matching the trial balance.
- Record the confirmed operating balancePassed
The bank confirmation for account ****0780 is recorded at $3,077,758.05.
- Record the confirmed payroll balancePassed
The zero-balance payroll account ****4290 is recorded as confirmed at $0.00.
- Reconcile deposits in transitPassed
Deposits in transit on the operating account are $0.00; the December bank balance equals the GL.
- Trace a cleared check back to the listPassed
Check 41001 is recorded as clearing the bank on 2026-01-16.
- Quantify bank concentrationPassed
All $3,077,758.05 of cash is held at a single institution.
- Compute uninsured depositsPassed
Uninsured exposure is $2,827,758.05: the balance less the $250,000 FDIC limit.
Professional judgmentClaims stay within what the evidence supports.3/3
- Don't claim an unsupported follow-upPassed
The follow-up is marked “Not evidenced,” with 12/24/2025 identified as a planned date, not a dispatch.
- Keep the overall conclusion openPassed
The conclusion is withheld pending evidence on the bank's financial condition, rather than signed off as complete.
- Describe the January statements accuratelyPassed
Both January statements are recorded as obtained, with the conflict between them flagged as an open issue.
Traceable documentationA reviewer can tie every comment to a record.3/3
- Tie lead-sheet comments to recordsPassed
Every comment on the lead sheet sits on an identifiable account row.
- Tie confirmation comments to recordsPassed
Every comment on the confirmation tab sits on an identifiable account row.
- Tie reconciliation comments to recordsPassed
Every comment on the reconciliation tab sits on an identifiable account row.
Quelvox Industrial Holdings, a synthetic manufacturer, is closing its December 31, 2025 audit. The agent is assigned the accounts receivable workpaper: agree gross receivables of $865K to the trial balance, re-age the open invoices, recompute the expected allowance for credit losses, and confirm significant customer balances, vouching non-replies to third-party cash receipt evidence.
The instruction is short because the procedures to perform are well documented within the workpaper template itself. The template lists 31 procedures across 8 tabs. Each tab defines what must be documented and how each figure must be supported. The engagement’s planning context sets materiality and the selection of individual items for detail testing.
Complete `accounts_receivable_workpaper.xlsx` using `pbc_package/`, `direct_to_auditor/`, and `planning/`. Follow workbook procedures and Planning Context. Save to `/workspace/accounts_receivable_workpaper.xlsx`.
The procedures live in the blank workpaper, not the prompt. It lists 31 of them across 8 tabs; the agent records each one's execution, evidence, result and signoff.
| Procedure | Assertions | Tab | |
|---|---|---|---|
| 2. | Obtain the AR lead sheet and agree gross AR, allowance and net AR to the trial balance and general ledger. | Existence; Completeness; Rights & Obligations | <.1> |
| 7. | Re-age open items from invoice/due date and recompute the aging-bucket classification; investigate where bucket labels contradict invoice dates. | Accuracy; Valuation & Allocation | <.3> |
| 14. | Recompute the expected credit loss using pooled aging x historical loss rates and compare to the recorded allowance. | Valuation & Allocation | <.5> |
| 17. | Send external positive AR confirmations to significant customers; maintain a confirmation control log (sent / method / follow-up / received / exceptions) with a response-rate summary. | Existence; Rights & Obligations | <.6> |
| 20. | For non-replies (or as alternative procedures), vouch open AR to subsequent bank-cleared cash receipts — agreeing the amount, the date of deposit into the bank, and the receipt reference. | Existence; Valuation & Allocation | <.6> |
| 31. | All planned AR audit procedures above were performed; results support the recorded gross AR, allowance and net AR and related disclosures, subject to documented open items. | Overall | <.0>–<.7> |
| + 25 more procedures | |||
- Overall materiality
- $64,880
- Performance materiality
- $48,660
- Clearly trivial
- $3,244
- Sampling plan
- 6 invoices
- 1Survey the binder
Lists every file in the workspace and dumps each tab of the blank receivables workpaper.
Turns 1–4 · find, openpyxl
Turn 1 · bashcd /workspace; find . -type f | head -100;
Output./accounts_receivable_workpaper.xlsx ./planning/Materiality Memo.pdf ./planning/Cycle Materiality Allocation Register.pdf ./planning/Financial Audit Planning Inputs.pdf ./planning/Related Party Register.pdf ./planning/Engagement Calendar.pdf ./planning/Audit Selection Plan.pdf ./planning/Audit Planning Packet Index.pdf ./planning/Unadjusted Differences Register.pdf ./planning/Controls and IT-IPE Strategy.pdf ./planning/FSLI Scope Matrix.pdf ./planning/Significance Matrix.pdf ./planning/Engagement Scope and Case Facts.pdf ./planning/Significant and Fraud Risk Register.pdf … 86 more lines
Turn 2 · bashcd /workspace; find . -type f | tail -n +101;
Output./pbc_package/documents/payroll/Payroll Accrual Reconciliation 2025.pdf ./pbc_package/documents/payroll/Payroll Payment Detail 2025.xlsx ./pbc_package/documents/fixed_assets/Fixed Asset Impairment Assessment 2025.xlsx ./pbc_package/documents/bank_statements/MAY25 Payroll Stmt.pdf ./pbc_package/documents/bank_statements/DEC25 Payroll Stmt.pdf ./pbc_package/documents/bank_statements/JUL25 Payroll Stmt.pdf ./pbc_package/documents/bank_statements/FEB25 Operating Stmt.pdf ./pbc_package/documents/bank_statements/NOV25 Operating Stmt.pdf ./pbc_package/documents/bank_statements/FEB25 Payroll Stmt.pdf ./pbc_package/documents/bank_statements/JUL25 Operating Stmt.pdf ./pbc_package/documents/bank_statements/OCT25 Operating Stmt.pdf ./pbc_package/documents/bank_statements/AUG25 Payroll Stmt.pdf ./pbc_package/documents/bank_statements/SEP25 Operating Stmt.pdf ./pbc_package/documents/bank_statements/JAN26 Payroll Stmt.pdf … 77 more lines
Turn 3 · bashcd /workspace; python3 -c " import openpyxl wb=openpyxl.load_workbook('accounts_receivable_workpaper.xlsx') for ws in wb: print('=====',ws.title,ws.dimensions) for r in ws.iter_rows(): for c in r: if c.value is not None: print(c.coordinate,repr(c.value)) "Output===== Library Procedures A1:Q48 A1 'Accounts Receivable — Library of Audit Procedures' A2 'Client / Entity: Quelvox Industrial Holdings, LLC' A3 'Prepared by: Audit Senior B377 (assigned) Reviewed by: Audit Manager 4104 (assigned)' A4 'For every procedure, record applicability, requirement, execution, evidence, result, issue, and signoff states. Performed procedures require a W/P reference, preparer, date, result, and exact Evidence Index citation. Fact-driven N/A requires a FACT:/ JSON-Pointer citation and rationale; missing evidence remains Open. Preserve the assigned PROC: and WINDOW: dependency tokens.' A6 'Applicability' B6 'Requirement' C6 'Execution state' D6 'Evidence state' E6 'Result state' F6 'Issue state' G6 'Signoff state' H6 'Derived outcome' I6 'Procedure' … 669 more lines
Turn 4 · bashcd /workspace; python3 -c " import openpyxl wb=openpyxl.load_workbook('accounts_receivable_workpaper.xlsx') print(wb.sheetnames) for ws in wb.worksheets[5:]: print('=====',ws.title,ws.dimensions) for r in ws.iter_rows(): for c in r: if c.value is not None: print(c.coordinate,repr(c.value)) "Output['Library Procedures', '<.0> Source Index', '<.1> AR Lead Sheet', '<.2> Aging Tie-Out', '<.3> Aging Bucket Testing', '<.4> Allowance for Doubtful', '<.5> CECL Expected Credit Loss', '<.6> Confirmation & Clearance', '<.7> Ratios & Disclosures', 'Planning Context'] ===== <.4> Allowance for Doubtful A1:H48 A1 'Allowance for Doubtful Accounts' A2 'Client / Entity' B2 'Quelvox Industrial Holdings, LLC' D2 'Year-End' E2 datetime.datetime(2025, 12, 31, 0, 0) G2 'Currency' H2 'USD' A3 'Performance Materiality' B3 32500 D3 'Tolerable misstatement / testing threshold' E3 29300 A4 'Purpose:' … 384 more lines
- 2Read the planning file
Extracts the planning PDFs to text and pulls materiality, assessed risks and the confirmation selection plan.
Turns 5–9 · pdftotext, grep
Turn 5 · bashcd /workspace/planning; for f in *.pdf; do echo "######## $f"; pdftotext -layout "$f" - ; done > /tmp/planning.txt; wc -l /tmp/planning.txt; head -400 /tmp/planning.txt sed -n 400,900p /tmp/planning.txt
Output2535 /tmp/planning.txt ######## Accounting Policy Register.pdf Quelvox Industrial Holdings, LLC WORKPAPER REF. PL-APR AUDIT PLANNING PREPARED BY: DATE: ACCOUNTING POLICY REGISTER REVIEWED BY: DATE: FIXED ASSETS APPLICABLE Yes … 707 more lines
Turn 6 · bashgrep -n -i -E "receivable|AR |allowance|credit loss|confirm|customer|INV-5|6008|1100|1200" /tmp/planning.txt | sed -n 1,300p
Output106: CREDIT LOSSES 117: APPLIES TO ar allowance policy, ar allowance estimate 130: APPLIES TO revenue detail, customer invoice, fulfillment event, general ledger account 139: Streams - Contract Balance Policy consideration billed before performance is deferred; earned unbilled amounts are contract assets or receivables 141: Streams - Contract Population customer contract 143: Streams - Cutoff Policy recognize only fulfillment through the fiscal year end 194: Payroll - Day Count Convention actual calendar days 252: Methodologies - Assumptions goods received before year end; vendor invoice arrives after close at the purchase-order price 262: Methodologies - Recognition Basis probable obligation for goods, services, or employee effort received through year end 297: Accounts receivable Existence Moderate Moderate Moderate No Substantive analytics and risk-calibrated detail testing 299: Accounts receivable Rights Moderate Moderate Moderate No Substantive analytics and risk-calibrated detail testing 301: Accounts receivable Valuation Moderate Moderate Moderate No Substantive analytics and risk-calibrated detail testing 303: Accounts receivable Cutoff Moderate Moderate Moderate No Substantive analytics and risk-calibrated detail testing 366: Revenue Occurrence High Moderate High No detail, cutoff, and confirmation or alternatives … 101 more lines
Turn 7 · bashsed -n 690,740p /tmp/planning.txt; sed -n 920,1110p /tmp/planning.txt sed -n 1110,1140p /tmp/planning.txt; sed -n 1300,1720p /tmp/planning.txt sed -n 1720,2135p /tmp/planning.txt; sed -n 2230,2535p /tmp/planning.txt | grep -v "^\s*$" | head -150
OutputCONTROLS AND IT-IPE STRATEGY REVIEWED BY: DATE: AUDIT STRATEGY Fully Substantive CONTROLS TESTED FOR RELIANCE 0 IPE REPORTS ASSESSED 90 IPE REPORTS CONCLUDED RELIABLE 78 A fully substantive response is required … 906 more lines
Turn 8 · bashsed -n 1970,2000p /tmp/planning.txt; sed -n 2080,2100p /tmp/planning.txt; sed -n 2310,2535p /tmp/planning.txt | grep -v "^\s*$" | head -120
OutputPurpose: defines the eligible evidence periods, cutoff boundaries, and look- forward horizons used by planned procedures. A registered window does not indicate that fieldwork has been performed. INTERIM PROCEDURES PERFORMED No - planning windows only PROCEDURE FAMILY TESTING PERIOD POPULATION DATE FIELD EVIDENCE STATUS REGISTERED SOURCES Interim Testing 11/14/2025 - 12/31/2025 Posting Date Complete journal entry.posting date (298 in window; observed through 2026-03-11) Confirmations 12/10/2025 - 02/19/2026 Received Date Document Control Required Milestone/document control … 149 more linesTurn 9 · bashcd /workspace; grep -n -A30 "Related Party Register.pdf" /tmp/planning.txt | head -40; python3 - <<'EOF' import openpyxl,glob for f in glob.glob('pbc_package/accounts_receivable/*.xlsx')+['direct_to_auditor/AR Auditor Evidence Control.xlsx','pbc_package/Package Index.xlsx']: wb=openpyxl.load_workbook(f) for ws in wb: print('=====',f,ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) EOFOutput2053: ######## Related Party Register.pdf 2054- Quelvox Industrial Holdings, LLC WORKPAPER REF. PL-RPR 2055- 2056- AUDIT PLANNING PREPARED BY: DATE: 2057- 2058- RELATED PARTY REGISTER REVIEWED BY: DATE: 2059- 2060- 2061- 2062- 2063- ASSESSMENT No related parties identified through management inquiry and review of available transaction records 2064- 2065- … 165 more lines
- 3Pull the client's records
Reads the aging, the allowance workbook, the confirmation control file, the package index and both trial balances.
Turns 10–17 · openpyxl
Turn 10 · bashcd /workspace; python3 - <<'EOF' import openpyxl,glob wb=openpyxl.load_workbook('pbc_package/accounts_receivable/AR Aging 12 31 25.xlsx') print(wb.sheetnames) ws=wb['AR Aging Detail'] for r in ws.iter_rows(min_row=60,values_only=True): if any(v is not None for v in r): print(r) for ws in wb.worksheets[2:]: print('=====',ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) EOFOutput['AR-to-GL Reconciliation', 'AR Aging Detail'] ('Vixolent Voxford Solutions, Inc.', 'INV-53167', datetime.datetime(2025, 11, 23, 0, 0), datetime.datetime(2026, 1, 7, 0, 0), 'net 45', '0', 11271.77, 11271.77, 'current', 'USD', '1010', 'Industrial Sales') ('Vixolent Voxford Solutions, Inc.', 'INV-53154', datetime.datetime(2025, 11, 23, 0, 0), datetime.datetime(2026, 1, 7, 0, 0), 'net 45', '0', 10337.02, 10337.02, 'current', 'USD', '1010', 'Industrial Sales') ('Zixmantel Veltman Holdings, Inc.', 'INV-53241', datetime.datetime(2025, 12, 23, 0, 0), datetime.datetime(2026, 1, 7, 0, 0), 'net 15', '0', 15457.18, 15457.18, 'current', 'USD', '1010', 'Industrial Sales') ('Quotivex Quozzer Solutions, Inc.', 'INV-53177', datetime.datetime(2025, 11, 23, 0, 0), datetime.datetime(2026, 1, 7, 0, 0), 'net 45', '0', 18337.44, 18337.44, 'current', 'USD', '1010', 'Industrial Sales') ('Zaxvento Vixler Holdings, Inc.', 'INV-53164', datetime.datetime(2025, 11, 23, 0, 0), datetime.datetime(2025, 12, 23, 0, 0), 'net 30', '8', 16135.38, 16135.38, '1-30', 'USD', '1010', 'Industrial Sales') ('Zephirax Vorquix Solutions, Inc.', 'INV-53112', datetime.datetime(2025, 10, 23, 0, 0), datetime.datetime(2025, 12, 22, 0, 0), 'net 60', '9', 7046.05, 7046.05, '1-30', 'USD', '1010', 'Industrial Sales') ('Zaxvento Vixler Holdings, Inc.', 'INV-53186', datetime.datetime(2025, 11, 23, 0, 0), datetime.datetime(2025, 12, 23, 0, 0), 'net 30', '8', 15771.15, 15771.15, '1-30', 'USD', '1010', 'Industrial Sales') ('Volvexian Quizmute Solutions, Inc.', 'INV-53182', datetime.datetime(2025, 11, 23, 0, 0), datetime.datetime(2025, 12, 23, 0, 0), 'net 30', '8', 11744.18, 11744.18, '1-30', 'USD', '1010', 'Industrial Sales') ('Zaxvento Quelvale Solutions, Inc.', 'INV-53221', datetime.datetime(2025, 11, 23, 0, 0), datetime.datetime(2025, 12, 23, 0, 0), 'net 30', '8', 6343.27, 6343.27, '1-30', 'USD', '1010', 'Industrial Sales') ('Zixtrova Vexholm Group, LLC', 'INV-53226', datetime.datetime(2025, 11, 23, 0, 0), datetime.datetime(2025, 12, 23, 0, 0), 'net 30', '8', 21646.86, 21646.86, '1-30', 'USD', '1010', 'Industrial Sales') ('Vorquine Quoxley Services, LLC', 'INV-53170', datetime.datetime(2025, 11, 23, 0, 0), datetime.datetime(2025, 12, 23, 0, 0), 'net 30', '8', 10328.87, 10328.87, '1-30', 'USD', '1010', 'Industrial Sales') ('Vexmultix Quorland Services, LLC', 'INV-53189', datetime.datetime(2025, 11, 23, 0, 0), datetime.datetime(2025, 12, 23, 0, 0), 'net 30', '8', 5325.27, 5325.27, '1-30', 'USD', '1010', 'Industrial Sales') ('Vixolent Voxford Solutions, Inc.', 'INV-53116', datetime.datetime(2025, 10, 23, 0, 0), datetime.datetime(2025, 12, 7, 0, 0), 'net 45', '24', 6626.51, 6626.51, '1-30', 'USD', '1010', 'Industrial Sales') … 19 more linesTurn 11 · bashcd /workspace; python3 - <<'EOF' import openpyxl,glob for f in ['pbc_package/accounts_receivable/Allowance for Credit Losses 12 31 25.xlsx','direct_to_auditor/AR Auditor Evidence Control.xlsx','pbc_package/Package Index.xlsx','pbc_package/foundational/TB 12 31 25.xlsx','pbc_package/foundational/TB 12 31 24.xlsx','pbc_package/foundational/Chart of Accounts.xlsx']: wb=openpyxl.load_workbook(f) for ws in wb: print('=====',f,ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) EOF cat pbc_package/foundational/tb123125_export_12.csvOutput===== pbc_package/accounts_receivable/Allowance for Credit Losses 12 31 25.xlsx Methodology A1:B13 ('Quelvox Industrial Holdings, LLC', None) ('Allowance Methodology', None) ('As of December 31, 2025', None) ('Estimate objective', 'Estimate expected credit losses on year-end trade receivables') ('Methodology', 'historical loss rates by aging pool; specific reserves when identified') ('Aging basis', 'Due date') ('Historical lookback', '2022-01-01 through 2024-12-31') ('Forward-looking factors', 'Current-year conditions did not require a qualitative overlay') ('Specific reserve rule', 'No customer-specific reserve was identified') ('Policy effective date', datetime.datetime(2025, 1, 1, 0, 0)) ('Management owner', 'Controller') ('Approval status', 'Approved') ===== pbc_package/accounts_receivable/Allowance for Credit Losses 12 31 25.xlsx Data Validation A1:B10 … 104 more linesTurn 12 · bashcd /workspace; python3 - <<'EOF' import openpyxl,glob wb=openpyxl.load_workbook('pbc_package/accounts_receivable/Allowance for Credit Losses 12 31 25.xlsx') print(wb.sheetnames) ws=wb['Specific Reserves'] for r in ws.iter_rows(min_row=5,values_only=True): if r[5] and 'no customer-specific' not in str(r[5]) or (r[7] not in (0,None)): print(r) print(ws.max_row, list(ws.iter_rows(min_row=ws.max_row-2,values_only=True))) for ws in wb.worksheets[wb.sheetnames.index('Specific Reserves')+1:]: print('=====',ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) EOFOutput['Methodology', 'Data Validation', 'Loss Rates by Pool', 'Historical Exposure', 'Historical Loss Events', 'Specific Reserves', 'Rollforward', 'Write-Off Detail', 'Subsequent Collections', 'Sensitivity'] ('Customer', 'Invoice', 'Exposure', 'Subsequent Receipts', 'Remaining Exposure', 'Risk Indicators', 'Direct Support Reference', 'Reserve', 'Conclusion') ('Quexford Quozzer Holdings, Inc.', 'INV-53005', 3586.75, 3586.75, 0, 'delinquency captured by the aging pool; no bankruptcy, dispute, or cessation indicator', 'Confirmation reference Specific Risk 2025 005', 0, 'pooled reserve is appropriate; no incremental specific reserve') ('Quotivex Quozzer Solutions, Inc.', 'INV-52948', 6837.38, 6837.38, 0, 'delinquency captured by the aging pool; no bankruptcy, dispute, or cessation indicator', 'Confirmation reference Specific Risk 2025 005', 0, 'pooled reserve is appropriate; no incremental specific reserve') ('Quilmaven Vorquex Group, LLC', 'INV-52990', 4475.21, 4475.21, 0, 'delinquency captured by the aging pool; no bankruptcy, dispute, or cessation indicator', 'Confirmation reference Specific Risk 2025 005', 0, 'pooled reserve is appropriate; no incremental specific reserve') ('Zaxvento Quelvale Solutions, Inc.', 'INV-52662', 6722.42, 0, 6722.42, 'delinquency captured by the aging pool; no bankruptcy, dispute, or cessation indicator', 'Confirmation reference Specific Risk 2025 005', 0, 'pooled reserve is appropriate; no incremental specific reserve') ('Vultixor Zemvaux Solutions, Inc.', 'INV-52679', 5961.76, 5961.76, 0, 'delinquency captured by the aging pool; no bankruptcy, dispute, or cessation indicator', 'Confirmation reference Specific Risk 2025 005', 0, 'pooled reserve is appropriate; no incremental specific reserve') ('Vixolent Voxford Solutions, Inc.', 'INV-52664', 6391.98, 6391.98, 0, 'delinquency captured by the aging pool; no bankruptcy, dispute, or cessation indicator', 'Confirmation reference Specific Risk 2025 005', 0, 'pooled reserve is appropriate; no incremental specific reserve') ('Zephirax Vorquix Solutions, Inc.', 'INV-52674', 6271.1, 0, 6271.1, 'delinquency captured by the aging pool; no bankruptcy, dispute, or cessation indicator', 'Confirmation reference Specific Risk 2025 005', 0, 'pooled reserve is appropriate; no incremental specific reserve') 88 [('Vultixor Zemvaux Solutions, Inc.', 'INV-52679', 5961.76, 5961.76, 0, 'delinquency captured by the aging pool; no bankruptcy, dispute, or cessation indicator', 'Confirmation reference Specific Risk 2025 005', 0, 'pooled reserve is appropriate; no incremental specific reserve'), ('Vixolent Voxford Solutions, Inc.', 'INV-52664', 6391.98, 6391.98, 0, 'delinquency captured by the aging pool; no bankruptcy, dispute, or cessation indicator', 'Confirmation reference Specific Risk 2025 005', 0, 'pooled reserve is appropriate; no incremental specific reserve'), ('Zephirax Vorquix Solutions, Inc.', 'INV-52674', 6271.1, 0, 6271.1, 'delinquency captured by the aging pool; no bankruptcy, dispute, or cessation indicator', 'Confirmation reference Specific Risk 2025 005', 0, 'pooled reserve is appropriate; no incremental specific reserve')] ===== Rollforward A1:B10 ('Quelvox Industrial Holdings, LLC', None) ('Rollforward', None) ('As of December 31, 2025', None) … 31 more linesTurn 13 · bashcd /workspace; python3 - <<'EOF' import openpyxl,glob for f in ['direct_to_auditor/AR Auditor Evidence Control.xlsx','pbc_package/Package Index.xlsx','pbc_package/foundational/TB 12 31 25.xlsx','pbc_package/foundational/TB 12 31 24.xlsx']: wb=openpyxl.load_workbook(f) for ws in wb: print('=====',f,ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) EOFOutput===== direct_to_auditor/AR Auditor Evidence Control.xlsx Confirmation Control A1:Z8 ('Quelvox Industrial Holdings, LLC', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('Auditor-Controlled Accounts Receivable Evidence', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('As of 2025-12-31', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('Confirmation control id', 'Subject id', 'Subject name', 'Balance date', 'Book balance', 'Selection basis', 'Validated destination', 'Address validation source', 'Address validation date', 'Address validation result', 'Authorized date', 'Sent date', 'Send method', 'Send log reference', 'Follow up date', 'Response date', 'Received date', 'Response medium', 'Direct receipt', 'Response reference', 'Response result', 'Response amount', 'Difference amount', 'Exception resolution', 'Electronic authenticity applicability', 'Electronic authenticity result') ('Confirmation reference 5F007F37B2', 'Zaxvento Quelvale Solutions, Inc.', 'Zaxvento Quelvale Solutions, Inc.', datetime.datetime(2025, 12, 31, 0, 0), 69102.87, 'largest positive non-government customer balances', 'Accounts Receivable Department, Zaxvento Quelvale Solutions, Inc.', 'independent customer website plus switchboard callback', datetime.datetime(2026, 1, 7, 0, 0), 'matched', datetime.datetime(2026, 1, 7, 0, 0), datetime.datetime(2026, 1, 8, 0, 0), 'auditor-controlled email', 'Confirmation reference Send 001', datetime.datetime(2026, 1, 19, 0, 0), datetime.datetime(2026, 2, 4, 0, 0), datetime.datetime(2026, 2, 5, 0, 0), 'Paper mail', True, 'Confirmation reference Reply 001', 'agree', 69102.87, 0, 'Not required', 'Not applicable proven paper', 'not applicable - proven paper reply; independent AVT completed') ('Confirmation reference B9D5586C7E', 'Quoxmark Vorquex Services, LLC', 'Quoxmark Vorquex Services, LLC', datetime.datetime(2025, 12, 31, 0, 0), 57414.08, 'largest positive non-government customer balances', 'Accounts Receivable Department, Quoxmark Vorquex Services, LLC', 'independent customer website plus switchboard callback', datetime.datetime(2026, 1, 6, 0, 0), 'matched', datetime.datetime(2026, 1, 6, 0, 0), datetime.datetime(2026, 1, 7, 0, 0), 'auditor-controlled email', 'Confirmation reference Send 002', datetime.datetime(2026, 1, 19, 0, 0), datetime.datetime(2026, 1, 30, 0, 0), datetime.datetime(2026, 2, 2, 0, 0), 'Paper fax', True, 'Confirmation reference Reply 002', 'agree', 57414.08, 0, 'Not required', 'Not applicable proven paper', 'not applicable - proven paper reply; independent AVT completed') ('Confirmation reference 6A36B133Ca', 'Quovixen Zaxburg Solutions, Inc.', 'Quovixen Zaxburg Solutions, Inc.', datetime.datetime(2025, 12, 31, 0, 0), 48342.94, 'largest positive non-government customer balances', 'Accounts Receivable Department, Quovixen Zaxburg Solutions, Inc.', 'independent customer website plus switchboard callback', datetime.datetime(2026, 1, 5, 0, 0), 'matched', datetime.datetime(2026, 1, 5, 0, 0), datetime.datetime(2026, 1, 6, 0, 0), 'auditor-controlled email', 'Confirmation reference Send 003', datetime.datetime(2026, 1, 16, 0, 0), datetime.datetime(2026, 2, 3, 0, 0), datetime.datetime(2026, 2, 3, 0, 0), 'Email attachment', True, 'Confirmation reference Reply 003', 'agree', 48342.94, 0, 'Not required', 'applicable', 'passed') ===== direct_to_auditor/AR Auditor Evidence Control.xlsx Coverage Summary A1:D10 ('Quelvox Industrial Holdings, LLC', None, None, None) ('Mutually Exclusive Evidence Coverage', None, None, None) ('Evidence Bucket', 'Invoice Count', 'Amount', 'Percent of Gross AR') ('confirmed', 15, 174859.89, 0.2020813957701215) ('Alternative bank cleared', 56, 591966.62, 0.6841216748959472) … 66 more linesTurn 14 · bashcd /workspace; python3 - <<'EOF' import openpyxl,glob wb=openpyxl.load_workbook('direct_to_auditor/AR Auditor Evidence Control.xlsx') print(wb.sheetnames) ws=wb['Coverage Detail'] for r in ws.iter_rows(min_row=60,values_only=True): if any(v is not None for v in r): print(r[1],r[2],r[4],r[5],r[7],r[8],r[9]) for n in wb.sheetnames[3:]: ws=wb[n]; print('=====',n,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) EOFOutput['Confirmation Control', 'Coverage Summary', 'Coverage Detail', 'Library Procedure Contract', 'IPE Reliability', 'Direct Allowance Support', 'CECL Reperformance', 'Sensitivity vs Difference', 'Presentation & Disclosure', 'Subsequent Credits', 'Subsequent Credit Detail', 'Revenue Cutoff', 'Procedure Contract'] INV-53186 Zaxvento Vixler Holdings, Inc. 15771.15 Alternative document only Invoice line 0060, Fulfillment record 0060, PO-25-7060, QT-25-1060, Shp Mo 2511 reference 016 (0.68 tons), SO-2025-30060 2025-11-23 00:00:00 none INV-53182 Volvexian Quizmute Solutions, Inc. 11744.18 Alternative bank cleared ACH-7442299 2026-02-17 00:00:00 none INV-53221 Zaxvento Quelvale Solutions, Inc. 6343.27 confirmed Confirmation reference Reply 001 2026-02-05 00:00:00 none INV-53226 Zixtrova Vexholm Group, LLC 21646.86 Alternative bank cleared ACH-1453926 2026-02-17 00:00:00 none INV-53170 Vorquine Quoxley Services, LLC 10328.87 Alternative bank cleared ACH-5510368 2026-02-17 00:00:00 none INV-53189 Vexmultix Quorland Services, LLC 5325.27 Alternative bank cleared ACH-5832329 2026-02-17 00:00:00 none INV-53116 Vixolent Voxford Solutions, Inc. 6626.51 Alternative bank cleared ACH-3997185 2026-02-17 00:00:00 none INV-53149 Zephirax Zixwater Holdings, Inc. 13417.43 Alternative bank cleared ACH-9581238 2026-02-17 00:00:00 none INV-53142 Zenvoque Zenvard Group, LLC 4691.53 Alternative document only Invoice line 0068, Fulfillment record 0068, PO-25-7068, QT-25-1068, Shp Mo 2510 reference 014 (0.36 tons), SO-2025-30068 2025-10-23 00:00:00 none INV-53144 Zaxvento Quelvale Solutions, Inc. 12471.68 confirmed Confirmation reference Reply 001 2026-02-05 00:00:00 none INV-53137 Quoxmark Vorquex Services, LLC 18860.89 confirmed Confirmation reference Reply 002 2026-02-02 00:00:00 none INV-53139 Zixmantel Vaquite Solutions, Inc. 11730.96 Alternative bank cleared ACH-2136486 2026-02-17 00:00:00 none INV-53178 Zenvoque Vorzane Services, LLC 2759.81 Alternative bank cleared ACH-2489477 2026-02-17 00:00:00 none … 63 more lines
Turn 15 · bashcd /workspace; python3 - <<'EOF' import openpyxl,glob wb=openpyxl.load_workbook('direct_to_auditor/AR Auditor Evidence Control.xlsx') for n in wb.sheetnames[7:]: ws=wb[n]; print('=====',n,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) EOFOutput===== Sensitivity vs Difference A1:O6 ('Ar allowance sensitivity id', 'Aging pool', 'Scenario name', 'Scenario type', 'Exposure amount', 'Baseline rate', 'Alternative rate', 'Baseline reserve', 'Scenario reserve', 'Sensitivity delta', 'Known best estimate difference', 'Difference classification', 'Adjusting entry required', 'Support reference', 'As of date') ('Confirmation reference Sens 001', 'current', 'selected loss rate plus sensitivity increment', 'Judgmental range', 571578.33, '0.0000', '0.0100', 0, 5715.78, 5715.78, 0, 'Judgmental range not misstatement', False, 'Confirmation reference History Ledger 2025 001; Confirmation reference Specific Risk 2025 001; Confirmation reference Economic Overlay 2025', datetime.datetime(2025, 12, 31, 0, 0)) ('Confirmation reference Sens 002', '1-30', 'selected loss rate plus sensitivity increment', 'Judgmental range', 151874, '0.0500', '0.0600', 7593.7, 9112.44, 1518.74, 0, 'Judgmental range not misstatement', False, 'Confirmation reference History Ledger 2025 002; Confirmation reference Specific Risk 2025 002; Confirmation reference Economic Overlay 2025', datetime.datetime(2025, 12, 31, 0, 0)) ('Confirmation reference Sens 003', '31-60', 'selected loss rate plus sensitivity increment', 'Judgmental range', 89528.55, '0.2000', '0.2100', 17905.71, 18801, 895.29, 0, 'Judgmental range not misstatement', False, 'Confirmation reference History Ledger 2025 003; Confirmation reference Specific Risk 2025 003; Confirmation reference Economic Overlay 2025', datetime.datetime(2025, 12, 31, 0, 0)) ('Confirmation reference Sens 004', '61-90', 'selected loss rate plus sensitivity increment', 'Judgmental range', 12066.87, '0.5000', '0.5100', 6033.44, 6154.1, 120.66, 0, 'Judgmental range not misstatement', False, 'Confirmation reference History Ledger 2025 004; Confirmation reference Specific Risk 2025 004; Confirmation reference Economic Overlay 2025', datetime.datetime(2025, 12, 31, 0, 0)) ('Confirmation reference Sens 005', 'over-90', 'selected loss rate plus sensitivity increment', 'Judgmental range', 40246.6, '1.0000', '1.0100', 40246.6, 40649.07, 402.47, 0, 'Judgmental range not misstatement', False, 'Confirmation reference History Ledger 2025 005; Confirmation reference Specific Risk 2025 005; Confirmation reference Economic Overlay 2025', datetime.datetime(2025, 12, 31, 0, 0)) ===== Presentation & Disclosure A1:M5 ('Ar presentation assessment id', 'topic', 'Authoritative source', 'Source reference', 'Population count', 'Population amount', 'Threshold or rule', 'Condition present', 'Required disclosure', 'Final note reference', 'conclusion', 'Clearance status', 'As of date') ('Confirmation reference Pres 001', 'Customer concentration', 'complete invoice-level AR aging', 'Confirmation reference 01 / customer master', '1', 69102.87, 'disclose customers at or above 10 percent of gross AR', False, False, 'not required - condition absent', 'Zaxvento Quelvale Solutions, Inc. represents 8.0% of gross AR', 'Cleared not applicable', datetime.datetime(2025, 12, 31, 0, 0)) ('Confirmation reference Pres 002', 'Pledged factored or assigned receivables', 'complete debt agreements and lender-confirmation scope', 'AGREEMENT-Debt reference 001', '1', 865294.35, 'disclose any pledge, factoring, assignment, or blanket lien', True, True, 'Notes to Financial Statements.xlsx - Receivables / Pledged / factored / assigned AR', 'receivables are within documented collateral terms', 'Cleared to final notes', datetime.datetime(2025, 12, 31, 0, 0)) ('Confirmation reference Pres 003', 'Related party receivables', 'complete customer master and related-party register', 'customer.Related party', '0', 0, 'separately present and disclose related-party receivables', False, False, 'not required - condition absent', 'no related-party customer identified', 'Cleared not applicable', datetime.datetime(2025, 12, 31, 0, 0)) ('Confirmation reference Pres 004', 'Credit balances', 'complete invoice-level AR aging and customer receipt population', 'Confirmation reference 01 Open amount / Customer cash receipt.Unapplied amount', '0', 0, 'reclassify customer credit balances to liabilities', False, False, 'not required - condition absent', 'no customer credit balance identified', 'Cleared not applicable', datetime.datetime(2025, 12, 31, 0, 0)) ===== Subsequent Credits A1:I2 … 16 more linesTurn 16 · bashcd /workspace; python3 - <<'EOF' import openpyxl,glob for f in ['pbc_package/Package Index.xlsx','pbc_package/foundational/TB 12 31 25.xlsx','pbc_package/foundational/TB 12 31 24.xlsx']: wb=openpyxl.load_workbook(f) for ws in wb: print('=====',f,ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) EOF cat pbc_package/foundational/tb123125_export_12.csv | head -80Output===== pbc_package/Package Index.xlsx Final Package Index A1:G172 ('Final File', 'Evidence Category', 'Purpose / Evidence Family', 'Version Status', 'Preparer', 'Reviewer', 'Package Date') ('direct_to_auditor/AR Auditor Evidence Control.xlsx', 'Package Control', 'AR Auditor Evidence Control', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/AR Confirmation - Quovixen Zaxburg Solutions Inc.pdf', 'Package Control', 'AR Confirmation - Quovixen Zaxburg Solutions Inc', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/AR Confirmation - Quoxmark Vorquex Services LLC.pdf', 'Package Control', 'AR Confirmation - Quoxmark Vorquex Services LLC', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/AR Confirmation - Zaxvento Quelvale Solutions Inc.pdf', 'Package Control', 'AR Confirmation - Zaxvento Quelvale Solutions Inc', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/Bank Confirmation 12.31.2025.pdf', 'Package Control', 'Bank Confirmation 12.31.2025', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/Inventory Count Observation 2025-12-31.pdf', 'Package Control', 'Inventory Count Observation 2025-12-31', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/Loan Confirmation 2025.pdf', 'Package Control', 'Loan Confirmation 2025', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/Audit Support Transmittal.docx', 'Package Control', 'Audit Support Transmittal', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/accounts_receivable/AR Aging 12 31 25.xlsx', 'Package Control', 'AR Aging 12 31 25', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/accounts_receivable/Allowance for Credit Losses 12 31 25.xlsx', 'Package Control', 'Allowance for Credit Losses 12 31 25', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/accounts_receivable/Cash Receipts Jan 2026.xlsx', 'Package Control', 'Cash Receipts Jan 2026', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/ap_and_accruals/2024 Accruals Paid in 2025.xlsx', 'Package Control', '2024 Accruals Paid in 2025', 'Final - authoritative', 'Joshua Zixford', 'Karen Vovstein', datetime.datetime(2025, 12, 31, 0, 0)) … 81 more linesTurn 17 · bashcd /workspace; python3 - <<'EOF' import openpyxl,glob for f in ['pbc_package/foundational/TB 12 31 25.xlsx','pbc_package/foundational/TB 12 31 24.xlsx','pbc_package/foundational/Chart of Accounts.xlsx']: wb=openpyxl.load_workbook(f) for ws in wb: print('=====',f,ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) EOF cat pbc_package/foundational/tb123125_export_12.csv | head -80Output===== pbc_package/foundational/TB 12 31 25.xlsx TB 12 31 25 A1:D46 ('Quelvox Industrial Holdings, LLC', None, None, None) ('TB 12 31 25', None, None, None) ('As of December 31, 2025', None, None, None) ('Account', 'Name', 'Debit', 'Credit') ('1000', 'Cash - operating', 3077758.05, 0) ('1010', 'Accounts receivable - trade', 865294.35, 0) ('1011', 'Allowance for credit losses', 0, 71779.45) ('1014', 'Inventory in transit', 3800.4, 0) ('1015', 'Inventory', 0, 0) ('1016', 'Inventory - raw materials', 61784.27, 0) ('1017', 'Inventory - work in process', 36045.64, 0) ('1018', 'Inventory - finished goods', 29070.16, 0) ('1019', 'Reserve for excess and obsolete inventory', 0, 0) … 158 more lines - 4Read the confirmation replies
Reads the three customer replies, then inspects each PDF to see which box the customer ticked.
Turns 18–22 · pdftotext, pdftoppm, pdfplumber
Turn 18 · bashcd /workspace; for f in direct_to_auditor/*.pdf; do echo "######## $f"; pdftotext -layout "$f" - ; done 2>&1 | grep -v "^\s*$" | head -300
Output######## direct_to_auditor/AR Confirmation - Quovixen Zaxburg Solutions Inc.pdf Quelvox Industrial Holdings, LLC ACCOUNTS RECEIVABLE CONFIRMATION Customer Quovixen Zaxburg Solutions, Inc. Address 789 Commerce Drive, Atlanta, GA 30303 Customer account 17656 Date of request 01/06/2026 Balance as of 12/31/2025 Our auditors, Hartwell & Vance, CPAs, are conducting an audit of our financial statements. Please compare the invoice detail and balance below with your records and complete the response section. This is not a request for payment. Please complete and return this form directly to our auditors: Hartwell & Vance, CPAs 412 Market Street, Suite 900, Philadelphia, PA 19106 Mail, or fax to +1 (617) 555-0723 … 208 more lines
Turn 19 · bashcd /tmp; for f in /workspace/direct_to_auditor/AR*.pdf; do n=$(basename "$f" .pdf | tr ' ' '_'); pdftoppm -r 60 -png "$f" "/tmp/$n"; done; ls /tmp/*.png
Output/tmp/AR_Confirmation_-_Quovixen_Zaxburg_Solutions_Inc-1.png /tmp/AR_Confirmation_-_Quoxmark_Vorquex_Services_LLC-1.png /tmp/AR_Confirmation_-_Zaxvento_Quelvale_Solutions_Inc-1.png
Turn 20 · bashcd /workspace; python3 - <<'EOF' import pdfplumber,glob for f in glob.glob('direct_to_auditor/AR*.pdf'): with pdfplumber.open(f) as p: pg=p.pages[0] words=pg.extract_words() for w in words: if w['text'] in ('X','AGREE.','DISAGREE.','✓','x'): print(f[-40:],w['text'],round(w['x0']),round(w['top'])) print('rects',[(round(r['x0']),round(r['top']),round(r['width'])) for r in pg.rects if r['width']<20]) print('chars non-ascii',set(c['text'] for c in pg.chars if ord(c['text'][0])>127)) EOFOutputon - Zaxvento Quelvale Solutions Inc.pdf AGREE. 72 302 on - Zaxvento Quelvale Solutions Inc.pdf DISAGREE. 72 308 rects [(5, 5, 2), (56, 303, 8), (56, 309, 8)] chars non-ascii set() ion - Quovixen Zaxburg Solutions Inc.pdf AGREE. 72 295 ion - Quovixen Zaxburg Solutions Inc.pdf X 58 299 ion - Quovixen Zaxburg Solutions Inc.pdf DISAGREE. 72 302 rects [(56, 296, 8), (56, 303, 8)] chars non-ascii set() tion - Quoxmark Vorquex Services LLC.pdf AGREE. 72 259 tion - Quoxmark Vorquex Services LLC.pdf X 58 262 tion - Quoxmark Vorquex Services LLC.pdf DISAGREE. 72 265 rects [(5, 5, 2), (56, 260, 8), (56, 266, 8)] chars non-ascii set()
Turn 21 · bashcd /workspace; python3 - <<'EOF' import pdfplumber,glob for f in glob.glob('direct_to_auditor/AR*.pdf'): with pdfplumber.open(f) as p: pg=p.pages[0] for c in pg.chars: if c['text']=='X' and c['x0']<65: print(f[-30:],c['top'],c['bottom'],c['size']) for r in pg.rects: if r['width']<20 and r['x0']>50: print(' rect',r['top'],r['bottom']) for w in pg.extract_words(): if w['text'] in ('AGREE.','DISAGREE.'): print(' ',w['text'],w['top'],w['bottom']) EOFOutputrect 302.65 311.15 rect 309.15 317.65 AGREE. 301.72999999999996 308.97999999999996 DISAGREE. 308.22999999999996 315.47999999999996 ixen Zaxburg Solutions Inc.pdf 299.0 306.25 7.25 rect 296.15 304.65 rect 302.65 311.15 AGREE. 295.22999999999996 302.47999999999996 DISAGREE. 301.72999999999996 308.97999999999996 xmark Vorquex Services LLC.pdf 262.5 269.75 7.25 rect 259.65 268.15 rect 266.15 274.65 AGREE. 258.73 265.98 DISAGREE. 265.23 272.48
Turn 22 · bashcd /workspace; python3 - <<'EOF' import pdfplumber,glob for f in glob.glob('direct_to_auditor/AR*.pdf'): with pdfplumber.open(f) as p: pg=p.pages[0] print(f[-35:], 'lines',len(pg.lines),'curves',len(pg.curves),'images',len(pg.images)) for l in pg.lines+pg.curves: if l['top']>240 and l['top']<330 and l['x0']<80: print(' ',round(l['x0']),round(l['top']),round(l['x1']),round(l['bottom'])) for im in pg.images: print(' img',round(im['x0']),round(im['top']),round(im['x1']),round(im['bottom'])) EOFOutputZaxvento Quelvale Solutions Inc.pdf lines 7 curves 1 images 0 48 289 564 289 57 304 64 310 58 304 64 311 Quovixen Zaxburg Solutions Inc.pdf lines 5 curves 1 images 0 48 283 564 283 - Quoxmark Vorquex Services LLC.pdf lines 5 curves 1 images 0 48 246 564 246 56 325 258 325 - 5Read the CECL memo and bank statements
Reads management's credit-loss memo and the December and January bank statements. January shows no deposits.
Turns 23–24 · pdftotext
Turn 23 · bashcd /workspace/pbc_package/documents; pdftotext -layout "CECL Methodology Memo 2025.pdf" - | grep -v "^\s*$"; pdftotext -layout "AR Aging 2025.pdf" - | grep -v "^\s*$" | head -60
OutputQuelvox Industrial Holdings, LLC MEMORANDUM To Audit file From Joshua Zixford, Controller Date 01/30/2026 Re Allowance for credit losses under ASC 326 - 12/31/2025 1. SCOPE AND POOLING This memo documents management's estimate of expected credit losses on trade receivables as of 12/31/2025. Receivables share similar risk characteristics within aging bands, so the portfolio is pooled by days past due: current, 1-30, 31-60, 61-90, over-90. Balances are aged from the due date. 2. METHODOLOGY Expected loss rates are applied to each pool's open exposure. The rates reflect the collection history of each aging band, with older receivables carrying progressively higher expected loss content, and are reviewed annually against subsequent collections, write-offs, and recoveries retained by aging cohort. The prior-year reserve and sensitivity columns below are the annual back-test controls. Receivables … 165 more lines
Turn 24 · bashcd /workspace/pbc_package/documents/bank_statements; pdftotext -layout "JAN26 Operating Stmt.pdf" - | grep -v "^\s*$" | head -80; pdftotext -layout "DEC25 Operating Stmt.pdf" - | grep -v "^\s*$" | head -30
OutputVeltford Trust 6789 Commerce Lane, San Antonio, TX 78201 Customer Service +1 (312) 555-0456 Member FDIC Account holder Quelvox Industrial Holdings, LLC Commercial Checking 9444600780 Statement Period January 01, 2026 through January 31, 2026 ACCOUNT SUMMARY INSTANCES AMOUNT Beginning Balance 3,077,758.05 Deposits and Additions 0 0.00 Checks Paid 1 18,242.41 Electronic Withdrawals 6 104,184.54 Ending Balance 2,955,331.10 CHECKS PAID … 76 more lines - 6Match invoices to support and receipts
Joins the aging to invoices, shipments and the client's cash-receipts listing: $714,357.58 received, every item dated February 17, 2026.
Turns 25–31 · pandas, openpyxl
Turn 25 · bashcd /workspace; python3 - <<'EOF' import openpyxl,glob for f in sorted(glob.glob('pbc_package/revenue/*.xlsx')): wb=openpyxl.load_workbook(f) for ws in wb: print('=====',f,ws.title,ws.dimensions) for i,r in enumerate(ws.iter_rows(values_only=True)): if i>12: break if any(v is not None for v in r): print(r) EOFOutput===== pbc_package/revenue/Credit Memo Register 2025.xlsx Credit Memo Register A1:K24 ('Quelvox Industrial Holdings, LLC', None, None, None, None, None, None, None, None, None, None) ('Credit Memo Register', None, None, None, None, None, None, None, None, None, None) ('For the year ended December 31, 2025', None, None, None, None, None, None, None, None, None, None) ('Ref', 'Customer', 'Customer account', 'Date', 'Amount', 'Reason', 'Related invoice', 'Approval', 'Accounting period', 'Settlement status', 'Post-year-end') ('CM-2753', 'Vaquilex Veltyne Solutions, Inc.', 'Vaquilex Veltyne Solutions, Inc.', datetime.datetime(2025, 7, 24, 0, 0), 540.83, 'returned goods', 'INV-52958', 'Approved', '2025-07', 'Applied', 'No') ('CM-2741', 'Volvexian Quizmute Solutions, Inc.', 'Volvexian Quizmute Solutions, Inc.', datetime.datetime(2025, 3, 22, 0, 0), 1936.4, 'damaged in transit', 'INV-52810', 'Approved', '2025-03', 'Applied', 'No') ('CM-2774', 'Quilmaven Vorquex Group, LLC', 'Quilmaven Vorquex Group, LLC', datetime.datetime(2025, 12, 13, 0, 0), 931.93, 'pricing concession', 'INV-53231', 'Approved', '2025-12', 'Applied', 'No') ('CM-2768', 'Quizmere Quixley Services, LLC', 'Quizmere Quixley Services, LLC', datetime.datetime(2025, 10, 28, 0, 0), 1948.93, 'damaged in transit', 'INV-53122', 'Approved', '2025-10', 'Applied', 'No') ('CM-2771', 'Zephirax Zixwater Holdings, Inc.', 'Zephirax Zixwater Holdings, Inc.', datetime.datetime(2025, 11, 16, 0, 0), 1677.63, 'billing correction', 'INV-53151', 'Approved', '2025-11', 'Applied', 'No') ('CM-2777', 'Vexmultix Quorland Services, LLC', 'Vexmultix Quorland Services, LLC', datetime.datetime(2025, 12, 16, 0, 0), 947.42, 'pricing concession', 'INV-53244', 'Approved', '2025-12', 'Applied', 'No') ('CM-2756', 'Vultixor Zemvaux Solutions, Inc.', 'Vultixor Zemvaux Solutions, Inc.', datetime.datetime(2025, 8, 6, 0, 0), 583.89, 'returned goods', 'INV-52974', 'Approved', '2025-08', 'Applied', 'No') ('CM-2759', 'Quotivex Quozzer Solutions, Inc.', 'Quotivex Quozzer Solutions, Inc.', datetime.datetime(2025, 8, 6, 0, 0), 392.6, 'pricing concession', 'INV-52980', 'Approved', '2025-08', 'Applied', 'No') ===== pbc_package/revenue/Customer Invoice Register 2025.xlsx Sales Invoice Register A1:Q462 … 81 more linesTurn 26 · bashcd /workspace; python3 - <<'EOF' import openpyxl wb=openpyxl.load_workbook('pbc_package/revenue/Credit Memo Register 2025.xlsx') for ws in wb: for r in ws.iter_rows(values_only=True): print(r) for f in ['pbc_package/revenue/Shipment and Delivery Log 2025.xlsx','pbc_package/revenue/Revenue to GL Recon 12 31 25.xlsx']: wb=openpyxl.load_workbook(f) for ws in wb: print('=====',f,ws.title,ws.dimensions) for i,r in enumerate(ws.iter_rows(values_only=True)): if i>10 and 'Shipment' in f: break print(r) wb=openpyxl.load_workbook('pbc_package/revenue/Revenue Detail 2025.xlsx'); print(wb.sheetnames) EOFOutput('Quelvox Industrial Holdings, LLC', None, None, None, None, None, None, None, None, None, None) ('Credit Memo Register', None, None, None, None, None, None, None, None, None, None) ('For the year ended December 31, 2025', None, None, None, None, None, None, None, None, None, None) (None, None, None, None, None, None, None, None, None, None, None) ('Ref', 'Customer', 'Customer account', 'Date', 'Amount', 'Reason', 'Related invoice', 'Approval', 'Accounting period', 'Settlement status', 'Post-year-end') ('CM-2753', 'Vaquilex Veltyne Solutions, Inc.', 'Vaquilex Veltyne Solutions, Inc.', datetime.datetime(2025, 7, 24, 0, 0), 540.83, 'returned goods', 'INV-52958', 'Approved', '2025-07', 'Applied', 'No') ('CM-2741', 'Volvexian Quizmute Solutions, Inc.', 'Volvexian Quizmute Solutions, Inc.', datetime.datetime(2025, 3, 22, 0, 0), 1936.4, 'damaged in transit', 'INV-52810', 'Approved', '2025-03', 'Applied', 'No') ('CM-2774', 'Quilmaven Vorquex Group, LLC', 'Quilmaven Vorquex Group, LLC', datetime.datetime(2025, 12, 13, 0, 0), 931.93, 'pricing concession', 'INV-53231', 'Approved', '2025-12', 'Applied', 'No') ('CM-2768', 'Quizmere Quixley Services, LLC', 'Quizmere Quixley Services, LLC', datetime.datetime(2025, 10, 28, 0, 0), 1948.93, 'damaged in transit', 'INV-53122', 'Approved', '2025-10', 'Applied', 'No') ('CM-2771', 'Zephirax Zixwater Holdings, Inc.', 'Zephirax Zixwater Holdings, Inc.', datetime.datetime(2025, 11, 16, 0, 0), 1677.63, 'billing correction', 'INV-53151', 'Approved', '2025-11', 'Applied', 'No') ('CM-2777', 'Vexmultix Quorland Services, LLC', 'Vexmultix Quorland Services, LLC', datetime.datetime(2025, 12, 16, 0, 0), 947.42, 'pricing concession', 'INV-53244', 'Approved', '2025-12', 'Applied', 'No') ('CM-2756', 'Vultixor Zemvaux Solutions, Inc.', 'Vultixor Zemvaux Solutions, Inc.', datetime.datetime(2025, 8, 6, 0, 0), 583.89, 'returned goods', 'INV-52974', 'Approved', '2025-08', 'Applied', 'No') ('CM-2759', 'Quotivex Quozzer Solutions, Inc.', 'Quotivex Quozzer Solutions, Inc.', datetime.datetime(2025, 8, 6, 0, 0), 392.6, 'pricing concession', 'INV-52980', 'Approved', '2025-08', 'Applied', 'No') ('CM-2765', 'Vorquine Quoxley Services, LLC', 'Vorquine Quoxley Services, LLC', datetime.datetime(2025, 10, 26, 0, 0), 1810.36, 'returned goods', 'INV-53115', 'Approved', '2025-10', 'Applied', 'No') … 39 more linesTurn 27 · bashcd /workspace; python3 - <<'EOF' import pandas as pd, datetime as dt ag=pd.read_excel('pbc_package/accounts_receivable/AR Aging 12 31 25.xlsx',sheet_name='AR Aging Detail',header=5) ag=ag[ag['Invoice'].notna()] print(len(ag), ag['Open Balance'].sum()) ye=pd.Timestamp('2025-12-31') ag['dpd']=(ye-ag['Due Date']).dt.days.clip(lower=0) ag['dsi']=(ye-ag['Invoice Date']).dt.days def b(d): return 'current' if d<=0 else '1-30' if d<=30 else '31-60' if d<=60 else '61-90' if d<=90 else 'over-90' ag['rb']=ag['dpd'].apply(b) ag['DPDrep']=ag['Days Past Due'].astype(int) print(ag[(ag.rb!=ag['Aging Bucket'])|(ag.dpd!=ag.DPDrep)][['Invoice','Invoice Date','Due Date','Terms','DPDrep','dpd','Aging Bucket','rb']]) # terms check … 16 more linesOutputTraceback (most recent call last): File "/usr/local/lib/python3.12/site-packages/pandas/core/indexes/base.py", line 3641, in get_loc return self._engine.get_loc(casted_key) ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "pandas/_libs/index.pyx", line 168, in pandas._libs.index.IndexEngine.get_loc File "pandas/_libs/index.pyx", line 197, in pandas._libs.index.IndexEngine.get_loc File "pandas/_libs/hashtable_class_helper.pxi", line 7668, in pandas._libs.hashtable.PyObjectHashTable.get_item File "pandas/_libs/hashtable_class_helper.pxi", line 7676, in pandas._libs.hashtable.PyObjectHashTable.get_item KeyError: 'Invoice' The above exception was the direct cause of the following exception: Traceback (most recent call last): File "<stdin>", line 3, in <module> … 6 more linesTurn 28 · bashcd /workspace; python3 - <<'EOF' import pandas as pd, datetime as dt, openpyxl ws=openpyxl.load_workbook('pbc_package/accounts_receivable/AR Aging 12 31 25.xlsx')['AR Aging Detail'] rows=list(ws.iter_rows(values_only=True)) hi=[i for i,r in enumerate(rows) if r[0]=='Customer'][0] ag=pd.DataFrame([r for r in rows[hi+1:] if r[1]],columns=rows[hi]) print(len(ag), ag['Open Balance'].sum()) ye=pd.Timestamp('2025-12-31') ag['Invoice Date']=pd.to_datetime(ag['Invoice Date']);ag['Due Date']=pd.to_datetime(ag['Due Date']) ag['dpd']=(ye-ag['Due Date']).dt.days.clip(lower=0) ag['dsi']=(ye-ag['Invoice Date']).dt.days def b(d): return 'current' if d<=0 else '1-30' if d<=30 else '31-60' if d<=60 else '61-90' if d<=90 else 'over-90' ag['rb']=ag['dpd'].apply(b) … 12 more linesOutput83 865294.35 Empty DataFrame Columns: [Invoice, Invoice Date, Due Date, Terms, DPDrep, dpd, Aging Bucket, rb] Index: [] Empty DataFrame Columns: [Invoice, Invoice Date, Due Date, Terms, due_calc] Index: [] sum count Aging Bucket 1-30 151874.00 14 31-60 89528.55 8 61-90 12066.87 2 current 571578.33 52 over-90 40246.60 7 … 18 more linesTurn 29 · bashcd /workspace; python3 - <<'EOF' import pandas as pd, openpyxl ag=pd.read_pickle('/tmp/ag.pkl') def load(f,s,key): ws=openpyxl.load_workbook(f)[s]; rows=list(ws.iter_rows(values_only=True)) hi=[i for i,r in enumerate(rows) if r[0]==key][0] return pd.DataFrame([r for r in rows[hi+1:] if r[0] is not None and r[1] is not None],columns=rows[hi]) rd=load('pbc_package/revenue/Revenue Detail 2025.xlsx','Annual Revenue Detail','Source Line ID') cr=load('pbc_package/accounts_receivable/Cash Receipts Jan 2026.xlsx','Subsequent Cash Receipts','#') sl=load('pbc_package/revenue/Shipment and Delivery Log 2025.xlsx','Shipment and Delivery Log','Support reference') ir=load('pbc_package/revenue/Customer Invoice Register 2025.xlsx','Sales Invoice Register','Invoice') print(len(rd),len(cr),len(sl),len(ir)) print('receipts total',cr['Amount'].sum()) m=ag.merge(cr,left_on='Invoice',right_on='Invoice applied',how='left') … 23 more linesOutput424 67 456 456 receipts total 714357.58 receipts not in aging set() Empty DataFrame Columns: [Invoice, Open Balance, Amount] Index: [] uncollected Invoice Customer Open Balance Aging Bucket 0 INV-53307 Vorquine Quilmont Group, LLC 7703.86 current 5 INV-53312 Quaxinov Zaxmoor Services, LLC 4486.45 current 11 INV-53330 Zixmantel Veltman Holdings, Inc. 4158.77 current 13 INV-53275 Zaxvento Quelvale Solutions, Inc. 10166.52 current 29 INV-53291 Vorquine Quilmont Group, LLC 3704.11 current 30 INV-53287 Zaxvento Quelvale Solutions, Inc. 15229.08 current 35 INV-53297 Voraxive Zixford Services, LLC 8862.14 current … 64 more lines
Turn 30 · bashcd /workspace; python3 - <<'EOF' import pandas as pd ag=pd.read_pickle('/tmp/ag.pkl'); cr=pd.read_pickle('/tmp/cr.pkl') m=ag.merge(cr,left_on='Invoice',right_on='Invoice applied',how='left') conf=['Zaxvento Quelvale Solutions, Inc.','Quoxmark Vorquex Services, LLC','Quovixen Zaxburg Solutions, Inc.'] big=m[m['Open Balance']>=16300].sort_values('Open Balance',ascending=False) pd.set_option('display.width',250) print(big[['Invoice','Customer','Open Balance','Aging Bucket','Amount','Bank reference']].assign(conf=big.Customer.isin(conf))) cb=ag.groupby('Customer')['Open Balance'].agg(['sum','count']).sort_values('sum',ascending=False) cb['pct']=cb['sum']/ag['Open Balance'].sum() print(cb) EOFOutputInvoice Customer ... Bank reference conf 61 INV-53226 Zixtrova Vexholm Group, LLC ... ACH-1453926 False 40 INV-53320 Quovalize Zaxburg Holdings, Inc. ... ACH-9295349 False 27 INV-53284 Vorquine Quoxley Services, LLC ... ACH-6794726 False 20 INV-53187 Voraxive Quaxvote Group, LLC ... ACH-8874313 False 10 INV-53278 Zarvexion Zaxvole Services, LLC ... ACH-1374640 False 41 INV-53310 Quoxmark Vorquex Services, LLC ... NaN True 44 INV-53336 Zixmantel Veltman Holdings, Inc. ... ACH-8939972 False 50 INV-53150 Quovixen Zaxburg Solutions, Inc. ... ACH-5811581 True 68 INV-53137 Quoxmark Vorquex Services, LLC ... ACH-5771952 True 55 INV-53177 Quotivex Quozzer Solutions, Inc. ... ACH-1023678 False 12 INV-53303 Zaxvento Quelvale Solutions, Inc. ... ACH-9591325 True 31 INV-53295 Vultixor Zemvaux Solutions, Inc. ... ACH-5331274 False 23 INV-53298 Vaquilex Veltyne Solutions, Inc. ... ACH-4703508 False … 35 more lines
Turn 31 · bashcd /workspace; python3 - <<'EOF' import pandas as pd, openpyxl pd.set_option('display.width',300); pd.set_option('display.max_columns',30); pd.set_option('display.max_colwidth',60) ag=pd.read_pickle('/tmp/ag.pkl'); rd=pd.read_pickle('/tmp/rd.pkl'); cr=pd.read_pickle('/tmp/cr.pkl') ws=openpyxl.load_workbook('pbc_package/revenue/Shipment and Delivery Log 2025.xlsx').active rows=list(ws.iter_rows(values_only=True)); sl=pd.DataFrame([r for r in rows[5:] if r[0]],columns=rows[4]) sel=['INV-53304','INV-53323','INV-53299','INV-53221','INV-53186','INV-53291'] isi=ag[ag['Open Balance']>=16300].Invoice.tolist() for inv in sel+isi+['INV-52662','INV-52674','INV-52679','INV-52664']: a=ag[ag.Invoice==inv].iloc[0] r=rd[rd.Invoice==inv] s=sl[sl['Invoice link']==inv] c=cr[cr['Invoice applied']==inv] print(inv,a.Customer,a['Invoice Date'].date(),a['Open Balance'],a['Aging Bucket'],'|', … 3 more linesOutputINV-53304 Vexmultix Quorland Services, LLC 2025-12-23 5070.9 current | ('PO-25-7004', 'SO-2025-30004', np.float64(0.22), Timestamp('2025-12-23 00:00:00'), 'Shp Mo 2512 reference 013 (0.22 tons)', 'POD-25-8004') | [['Shp Mo 2512 reference 013 (0.22 tons)', Timestamp('2025-12-23 00:00:00'), 0.22, 'signed proof of delivery']] | [[Timestamp('2026-02-17 00:00:00'), 5070.9, 'ACH-2923406']] INV-53323 Voraxive Zixford Services, LLC 2025-12-23 11084.84 current | ('PO-25-7033', 'SO-2025-30033', np.float64(0.5), Timestamp('2025-12-23 00:00:00'), 'Shp Mo 2512 reference 017 (0.5 tons)', 'POD-25-8033') | [['Shp Mo 2512 reference 017 (0.5 tons)', Timestamp('2025-12-23 00:00:00'), 0.5, 'signed proof of delivery']] | [[Timestamp('2026-02-17 00:00:00'), 11084.84, 'ACH-8927994']] INV-53299 Vaxilume Vultane Group, LLC 2025-12-23 8552.75 current | ('PO-25-7035', 'SO-2025-30035', np.float64(0.36), Timestamp('2025-12-23 00:00:00'), 'Shp Mo 2512 reference 017 (0.36 tons)', 'POD-25-8035') | [['Shp Mo 2512 reference 017 (0.36 tons)', Timestamp('2025-12-23 00:00:00'), 0.36, 'signed proof of delivery']] | [[Timestamp('2026-02-17 00:00:00'), 8552.75, 'ACH-7648413']] INV-53221 Zaxvento Quelvale Solutions, Inc. 2025-11-23 6343.27 1-30 | ('PO-25-7062', 'SO-2025-30062', np.float64(0.28), Timestamp('2025-11-23 00:00:00'), 'Shp Mo 2511 reference 016 (0.28 tons)', 'POD-25-8062') | [['Shp Mo 2511 reference 016 (0.28 tons)', Timestamp('2025-11-23 00:00:00'), 0.28, 'signed proof of delivery']] | [[Timestamp('2026-02-17 00:00:00'), 6343.27, 'ACH-7598083']] INV-53186 Zaxvento Vixler Holdings, Inc. 2025-11-23 15771.15 1-30 | ('PO-25-7060', 'SO-2025-30060', np.float64(0.68), Timestamp('2025-11-23 00:00:00'), 'Shp Mo 2511 reference 016 (0.68 tons)', 'POD-25-8060') | [['Shp Mo 2511 reference 016 (0.68 tons)', Timestamp('2025-11-23 00:00:00'), 0.68, 'signed proof of delivery']] | [] INV-53291 Vorquine Quilmont Group, LLC 2025-12-23 3704.11 current | ('PO-25-7030', 'SO-2025-30030', np.float64(0.16), Timestamp('2025-12-23 00:00:00'), 'Shp Mo 2512 reference 016 (0.16 tons)', 'POD-25-8030') | [['Shp Mo 2512 reference 016 (0.16 tons)', Timestamp('2025-12-23 00:00:00'), 0.16, 'signed proof of delivery']] | [] INV-53278 Zarvexion Zaxvole Services, LLC 2025-12-23 20488.94 current | ('PO-25-7011', 'SO-2025-30011', np.float64(0.88), Timestamp('2025-12-23 00:00:00'), 'Shp Mo 2512 reference 014 (0.88 tons)', 'POD-25-8011') | [['Shp Mo 2512 reference 014 (0.88 tons)', Timestamp('2025-12-23 00:00:00'), 0.88, 'signed proof of delivery']] | [[Timestamp('2026-02-17 00:00:00'), 20488.94, 'ACH-1374640']] INV-53303 Zaxvento Quelvale Solutions, Inc. 2025-12-23 18169.9 current | ('PO-25-7013', 'SO-2025-30013', np.float64(0.83), Timestamp('2025-12-23 00:00:00'), 'Shp Mo 2512 reference 015 (0.83 tons)', 'POD-25-8013') | [['Shp Mo 2512 reference 015 (0.83 tons)', Timestamp('2025-12-23 00:00:00'), 0.83, 'signed proof of delivery']] | [[Timestamp('2026-02-17 00:00:00'), 18169.9, 'ACH-9591325']] INV-53187 Voraxive Quaxvote Group, LLC 2025-11-23 20507.76 current | ('PO-25-7021', 'SO-2025-30021', np.float64(0.89), Timestamp('2025-11-23 00:00:00'), 'Shp Mo 2511 reference 013 (0.89 tons)', 'POD-25-8021') | [['Shp Mo 2511 reference 013 (0.89 tons)', Timestamp('2025-11-23 00:00:00'), 0.89, 'signed proof of delivery']] | [[Timestamp('2026-02-17 00:00:00'), 20507.76, 'ACH-8874313']] INV-53298 Vaquilex Veltyne Solutions, Inc. 2025-12-23 17359.8 current | ('PO-25-7024', 'SO-2025-30024', np.float64(0.77), Timestamp('2025-12-23 00:00:00'), 'Shp Mo 2512 reference 016 (0.77 tons)', 'POD-25-8024') | [['Shp Mo 2512 reference 016 (0.77 tons)', Timestamp('2025-12-23 00:00:00'), 0.77, 'signed proof of delivery']] | [[Timestamp('2026-02-17 00:00:00'), 17359.8, 'ACH-4703508']] INV-53280 Vaquilex Zelvane Holdings, Inc. 2025-12-23 16841.34 current | ('PO-25-7027', 'SO-2025-30027', np.float64(0.71), Timestamp('2025-12-23 00:00:00'), 'Shp Mo 2512 reference 016 (0.71 tons)', 'POD-25-8027') | [['Shp Mo 2512 reference 016 (0.71 tons)', Timestamp('2025-12-23 00:00:00'), 0.71, 'signed proof of delivery']] | [[Timestamp('2026-02-17 00:00:00'), 16841.34, 'ACH-5601443']] INV-53284 Vorquine Quoxley Services, LLC 2025-12-23 20871.57 current | ('PO-25-7028', 'SO-2025-30028', np.float64(0.88), Timestamp('2025-12-23 00:00:00'), 'Shp Mo 2512 reference 016 (0.88 tons)', 'POD-25-8028') | [['Shp Mo 2512 reference 016 (0.88 tons)', Timestamp('2025-12-23 00:00:00'), 0.88, 'signed proof of delivery']] | [[Timestamp('2026-02-17 00:00:00'), 20871.57, 'ACH-6794726']] INV-53295 Vultixor Zemvaux Solutions, Inc. 2025-12-23 17867.98 current | ('PO-25-7032', 'SO-2025-30032', np.float64(0.82), Timestamp('2025-12-23 00:00:00'), 'Shp Mo 2512 reference 017 (0.82 tons)', 'POD-25-8032') | [['Shp Mo 2512 reference 017 (0.82 tons)', Timestamp('2025-12-23 00:00:00'), 0.82, 'signed proof of delivery']] | [[Timestamp('2026-02-17 00:00:00'), 17867.98, 'ACH-5331274']] INV-53320 Quovalize Zaxburg Holdings, Inc. 2025-12-23 21610.61 current | ('PO-25-7041', 'SO-2025-30041', np.float64(0.9), Timestamp('2025-12-23 00:00:00'), 'Shp Mo 2512 reference 017 (0.43 tons) / Shp Mo 2512 reference 018 (0.47 tons)', 'POD-25-8041') | [['Shp Mo 2512 reference 017 (0.43 tons) / Shp Mo 2512 reference 018 (0.47 tons)', Timestamp('2025-12-23 00:00:00'), 0.9, 'signed proof of delivery']] | [[Timestamp('2026-02-17 00:00:00'), 21610.61, 'ACH-9295349']] … 10 more lines - 7Check the ledger and disclosures
Reads the prior-year statements, the notes, the journal entry population and the planning file's reliability ratings.
Turns 32–36 · pdftotext, openpyxl, python-docx
Turn 32 · bashcd /workspace/pbc_package; pdftotext -layout "documents/Audited Financial Statements 12.31.2024.pdf" - | grep -v "^\s*$" | grep -i -E -B2 -A4 "receivable|allowance|credit loss|revenue|sales" | head -80; python3 -c " import docx;d=docx.Document('Audit Support Transmittal.docx') for p in d.paragraphs: print(p.text) for t in d.tables: for r in t.rows: print([c.text for c in r.cells]) "OutputASSETS Cash - operating $1,531,548 Accounts receivable - trade $497,600 Allowance for credit losses $(46,510) Inventory - raw materials $58,931 Inventory - work in process $30,584 Inventory - finished goods $31,447 Prepaid expenses $32,104 -- STATEMENT OF INCOME For the Year Ended December 31, 2024 Revenue $4,127,815 Operating and other expenses $3,790,938 NET INCOME $336,877 … 40 more linesTurn 33 · bashcd /workspace/pbc_package/documents; python3 - <<'EOF' import openpyxl for f in ['Notes to Financial Statements.xlsx','Balance Sheet.xlsx','Income Statement.xlsx']: wb=openpyxl.load_workbook(f) for ws in wb: print('=====',f,ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): if any(v is not None for v in r): print(r) EOF pdftotext -layout "agreements/Quelvox Industrial - Loan Agreement 993785604 [EXECUTED].pdf" - | grep -i -E -B2 -A3 "receivable|collateral|lien|security" | head -50; pdftotext -layout "debt/Debt Perfection Evidence Debt reference 001.pdf" - | grep -v "^\s*$" | head -40Output===== Notes to Financial Statements.xlsx Notes to Financial Statements A1:B98 ('Quelvox Industrial Holdings, LLC', None) ('Notes to Financial Statements', None) ('Report parameters: 2026-01-01 through 2026-03-01 (event date)', None) ('Note 1 — Organization and basis of presentation', None) ('The accompanying statements are management-prepared, accrual-basis financial statements for the year ended December 31, 2025.', None) ('Note 2 — Significant accounting policies', None) ('Cash equivalents include demand deposits and money-market balances available for current operations.', None) ('Raw material, work in process, and finished goods are stated at the lower of FIFO cost and net realizable value.', None) ('FIFO cost includes dated supplier layers and documented direct labor and production overhead incurred at each conversion stage.', None) ('Revenue is recognized when finished goods ship under the applicable customer terms.', None) ('Note 3 — Balance-sheet detail', 'December 31 balance') ('Cash and cash equivalents', 3077758.05) ('Gross receivables', 865294.35) … 161 more linesTurn 34 · bashcd /workspace; python3 - <<'EOF' import openpyxl, pandas as pd wb=openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx') print(wb.sheetnames) for ws in wb: rows=list(ws.iter_rows(values_only=True)) print(ws.title, ws.dimensions); for r in rows[:6]: print(r) EOFOutput['Complete Journal Entry', 'Population Controls', 'Account Reconciliation', 'Account Component Map', 'User Access Listing'] Complete Journal Entry A1:AC3240 ('Quelvox Industrial Holdings, LLC', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('Complete Journal Entry Population', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('Report parameters: 2025-11-14 through 2025-12-31 (posting date)', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) (None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('Entry number', 'Line', 'Line ID', 'Parent line ID', 'Posting date', 'Document number', 'Source', 'Type', 'Post-close', 'Top-side', 'Consolidation/elimination', 'Estimate', 'Ordinary period-end', 'Counterparty', 'Memo', 'Account', 'Debit', 'Credit', 'Posting type', 'Preparer', 'Entered at', 'Approver', 'Approved at', 'Approval basis', 'Posted at', 'Timestamp zone', 'Status', 'Support', 'Reverses entry') ('JE-285291614009', 1, 'JEL-BA0176747AFD048C95BDEECF-C11B0FA2CF871FC39', 'JEL-BA0176747AFD048C95BDEECF', '01/01/2025', None, 'General Journal', 'System', 'No', 'No', 'No', 'No', 'No', None, 'Opening balances carried forward from prior-year close', '1000 Cash - operating', 1531548.07, None, 'Ledger', 'SYSTEM', '2025-01-01T05:19:19', 'Karen Vovstein', '2025-01-02T09:00:00', 'Automated posting under annual control authorization', '2025-01-01T05:19:19', 'CT (UTC-06:00; UTC-05:00 daylight)', 'posted', 'Prior-year trial balance', None) Population Controls A1:F25 ('Population stage', 'Entry count', 'Line count', 'Debit total', 'Credit total', 'Control status') ('Source', 1431, '3227', 20510522.17, 20510522.17, 'Tied') ('Raw', 1431, '3229', 20510522.17, 20510522.17, 'Tied') ('Working', 1431, '3229', 20510522.17, 20510522.17, 'Tied') (None, None, None, None, None, None) … 20 more linesTurn 35 · bashcd /workspace; python3 - <<'EOF' import openpyxl, pandas as pd ws=openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx')['Complete Journal Entry'] rows=list(ws.iter_rows(values_only=True)) df=pd.DataFrame(rows[5:],columns=rows[4]); df=df[df['Entry number'].notna()] df['acct']=df['Account'].astype(str).str[:4] ar=df[df.acct.isin(['1010','1011','6062'])] ents=set(ar['Entry number']) sub=df[df['Entry number'].isin(ents)] combo=sub.groupby('Entry number')['acct'].apply(lambda s:'/'.join(sorted(set(s)))) print(combo.value_counts()) for e,c in combo.items(): if c not in ('1000/1010','1010/2037/4010','1010/4010'): print(sub[sub['Entry number']==e][['Entry number','Posting date','Memo','Account','Debit','Credit','Counterparty']].to_string()) … 3 more linesOutputacct 1000/1010 423 1010/2037/4010 306 1010/4010 134 1000/1010/1011/1016/1017/1018/1030/1050/1051/2041/3030 1 1011/6062 1 Name: count, dtype: int64 Entry number Posting date Memo Account Debit Credit Counterparty 0 JE-285291614009 01/01/2025 Opening balances carried forward from prior-year close 1000 Cash - operating 1531548.07 NaN NaN 1 JE-285291614009 01/01/2025 Opening balances carried forward from prior-year close 1010 Accounts receivable - trade 497599.56 NaN NaN 2 JE-285291614009 01/01/2025 Opening balances carried forward from prior-year close 1016 Inventory - raw materials 58931.35 NaN NaN 3 JE-285291614009 01/01/2025 Opening balances carried forward from prior-year close 1017 Inventory - work in process 30583.68 NaN NaN 4 JE-285291614009 01/01/2025 Opening balances carried forward from prior-year close 1018 Inventory - finished goods 31446.87 NaN NaN 5 JE-285291614009 01/01/2025 Opening balances carried forward from prior-year close 1030 Prepaid expenses 32104.11 NaN NaN … 16 more linesTurn 36 · bashcd /workspace; pdftotext -layout "planning/Controls and IT-IPE Strategy.pdf" - | grep -v "^\s*$" | sed -n 30,200p
OutputCash Account Listing and Reconciliations.xlsx Cash Failed Failed Not_Applicable Not Reliable Cash Account Listing and Reconciliations.xlsx Cash Failed Failed Not_Applicable Not Reliable Cash Account Listing and Reconciliations.xlsx Cash Failed Failed Not_Applicable Not Reliable Cash Account Listing and Reconciliations.xlsx Cash Failed Failed Not_Applicable Not Reliable Interbank Transfer Activity 2025.xlsx Cash Passed Passed Not_Applicable Reliable Cash Account Listing and Reconciliations.xlsx Cash Failed Failed Not_Applicable Not Reliable Cash Account Listing and Reconciliations.xlsx Cash Failed Failed Not_Applicable Not Reliable Disbursement Journal 2025.xlsx Cash Passed Passed Not_Applicable Reliable Debt Schedule 12 31 25.xlsx Debt Passed Passed Not_Applicable Reliable Note Payable Rollforward and Amort Schedule 2025.xlsx Debt Passed Passed Not_Applicable Reliable Debt Maturity Schedule 12 31 25.xlsx Debt Passed Passed Not_Applicable Reliable Interest Accrued and Paid by Note Payable for 2025.xlsx Debt Passed Passed Not_Applicable Reliable Amortization Schedule.xlsx Debt Passed Passed Not_Applicable Reliable Debt Support Schedules 2025.xlsx Debt Passed Passed Not_Applicable Reliable … 72 more lines
- 8Review loss history and billings
Recomputes historical loss rates from the cohort data and finds a November–December billing spike.
Turns 37–39 · pandas
Turn 37 · bashcd /workspace; python3 - <<'EOF' import openpyxl, pandas as pd wb=openpyxl.load_workbook('pbc_package/accounts_receivable/Allowance for Credit Losses 12 31 25.xlsx') rows=list(wb['Historical Loss Events'].iter_rows(values_only=True)) ev=pd.DataFrame(rows[4:],columns=rows[3]); ev=ev[ev['Aging Pool'].notna()] ev['Recovery']=ev['Recovery'].astype(float); ev['yr']=ev['Write-Off Date'].apply(lambda d:d.year) print(ev.groupby(['yr'])[['Original Amount','Write-Off','Recovery','Net Loss']].sum()) print(ev.groupby(['Aging Pool'])[['Original Amount','Write-Off','Recovery','Net Loss']].sum()) print(ev.groupby(['Aging Pool','yr'])[['Original Amount','Write-Off','Recovery','Net Loss']].sum()) ev['chk']=ev['Write-Off']-ev['Recovery']-ev['Net Loss']; print(ev.chk.abs().max()) print(ev[ev['Recovery']>ev['Write-Off']][['Aging Pool','Invoice','Write-Off','Recovery','Net Loss']]) print(ev[ev['Write-Off']>ev['Original Amount']]) rows=list(wb['Historical Exposure'].iter_rows(values_only=True)) he=pd.DataFrame(rows[4:],columns=rows[3]); he=he[he['Aging Pool'].notna()] … 2 more linesOutputTraceback (most recent call last): File "/usr/local/lib/python3.12/site-packages/pandas/core/indexes/base.py", line 3641, in get_loc return self._engine.get_loc(casted_key) ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "pandas/_libs/index.pyx", line 168, in pandas._libs.index.IndexEngine.get_loc File "pandas/_libs/index.pyx", line 192, in pandas._libs.index.IndexEngine.get_loc File "pandas/_libs/index.pyx", line 235, in pandas._libs.index.IndexEngine._get_loc_duplicates File "pandas/_libs/index.pyx", line 243, in pandas._libs.index.IndexEngine._maybe_get_bool_indexer File "pandas/_libs/index.pyx", line 135, in pandas._libs.index._unpack_bool_indexer KeyError: 'Aging Pool' The above exception was the direct cause of the following exception: Traceback (most recent call last): … 7 more linesTurn 38 · bashcd /workspace; python3 - <<'EOF' import openpyxl, pandas as pd wb=openpyxl.load_workbook('pbc_package/accounts_receivable/Allowance for Credit Losses 12 31 25.xlsx') def ld(s): rows=[r for r in wb[s].iter_rows(values_only=True) if any(v is not None for v in r)] hi=[i for i,r in enumerate(rows) if r[0]=='Aging Pool'][0] return pd.DataFrame(rows[hi+1:],columns=rows[hi]) ev=ld('Historical Loss Events') ev['Recovery']=ev['Recovery'].astype(float); ev['yr']=ev['Write-Off Date'].apply(lambda d:d.year) print(ev.groupby(['yr'])[['Original Amount','Write-Off','Recovery','Net Loss']].sum()) print(ev.groupby(['Aging Pool'])[['Original Amount','Write-Off','Recovery','Net Loss']].sum()) ev['chk']=ev['Write-Off']-ev['Recovery']-ev['Net Loss']; print('chk',ev.chk.abs().max()) print(ev[ev['Recovery']>ev['Write-Off']][['Aging Pool','Invoice','Write-Off','Recovery','Net Loss']]) he=ld('Historical Exposure') … 5 more linesOutputOriginal Amount Write-Off Recovery Net Loss yr 2022 606321.70 343800.0 262500.0 81300.0 2023 658433.88 429750.0 218750.0 211000.0 2024 732332.15 515700.0 175000.0 340700.0 Original Amount Write-Off Recovery Net Loss Aging Pool 1-30 71862.63 49750.0 18750.0 31000.0 31-60 250682.10 167000.0 75000.0 92000.0 61-90 512836.50 317500.0 187500.0 130000.0 over-90 1161706.50 755000.0 375000.0 380000.0 chk 1.8189894035458565e-12 Aging Pool Invoice Write-Off Recovery Net Loss 7 31-60 Hist Inv 2022 reference 003-02 19149.33 19500.0 -350.67 … 22 more linesTurn 39 · bashcd /workspace; python3 - <<'EOF' import pandas as pd rd=pd.read_pickle('/tmp/rd.pkl') rd['m']=pd.to_datetime(rd['Invoice Date']).dt.to_period('M') print(rd.groupby('m').agg(n=('Invoice','nunique'),tot=('Invoice Total','sum'),gross=('Gross','sum'))) print(rd['Invoice Date'].min(), rd['Invoice Date'].max(), rd.Invoice.nunique()) print(rd['Invoice Total'].sum()) ag=pd.read_pickle('/tmp/ag.pkl') print(ag.groupby(ag['Invoice Date'].dt.to_period('M'))['Open Balance'].agg(['sum','count'])) d=rd[rd.m=='2025-12']; print('dec inv dates',d['Invoice Date'].value_counts()) EOFOutputn tot gross m 2025-01 27 299063.21 299541.93 2025-02 25 290437.83 291788.36 2025-03 30 327657.69 331851.03 2025-04 29 326030.12 328417.48 2025-05 26 292630.82 292794.16 2025-06 28 317865.81 317852.66 2025-07 31 331618.12 335999.75 2025-08 33 308229.70 309663.45 2025-09 32 322571.58 323034.52 2025-10 38 396321.50 395244.65 2025-11 62 680235.58 683408.76 2025-12 62 664824.13 663896.59 … 15 more lines
- 9Inspect the template
Checks the template's tables, validations and conditional formatting so the fill preserves them.
Turns 40–45 · zipfile
Turn 40 · bashcd /workspace; mkdir -p /tmp/x; cd /tmp/x; unzip -o -q /workspace/accounts_receivable_workpaper.xlsx; ls xl/worksheets; grep -o '<dataValidation[^>]*>.\{0,300\}' xl/worksheets/sheet1.xml | head; grep -c dataValidation xl/worksheets/*.xml; ls xl; cat xl/workbook.xml | head -50Outputbash: line 1: unzip: command not found ls: cannot access 'xl/worksheets': No such file or directory grep: xl/worksheets/sheet1.xml: No such file or directory grep: xl/worksheets/*.xml: No such file or directory ls: cannot access 'xl': No such file or directory cat: xl/workbook.xml: No such file or directory
Turn 41 · bashcd /tmp/x; python3 -c " import zipfile;z=zipfile.ZipFile('/workspace/accounts_receivable_workpaper.xlsx');z.extractall('.');print(z.namelist())"; grep -o '<dataValidation .\{0,400\}' xl/worksheets/sheet1.xml | head -20; grep -o 'definedName.\{0,200\}' xl/workbook.xml; grep -o '<comment.\{0,300\}' -r xl | headOutput['xl/theme/theme1.xml', 'xl/worksheets/sheet1.xml', 'xl/worksheets/sheet2.xml', 'xl/worksheets/sheet3.xml', 'xl/worksheets/sheet4.xml', 'xl/worksheets/sheet5.xml', 'xl/worksheets/sheet6.xml', 'xl/worksheets/sheet7.xml', 'xl/worksheets/sheet8.xml', 'xl/tables/table1.xml', 'xl/worksheets/_rels/sheet8.xml.rels', 'xl/worksheets/sheet9.xml', 'xl/worksheets/sheet10.xml', 'xl/styles.xml', '_rels/.rels', 'xl/workbook.xml', 'xl/_rels/workbook.xml.rels', '[Content_Types].xml', 'xl/', 'xl/worksheets/'] <dataValidation sqref="A8 A10 A11 A12 A13 A15 A17 A18 A20 A21 A22 A23 A25 A26 A27 A28 A30 A31 A32 A33 A34 A35 A37 A38 A39 A40 A42 A43 A45 A46 A48" showDropDown="0" showInputMessage="0" showErrorMessage="0" allowBlank="0" type="list"><formula1>"Applicable,Not Applicable - Fact Driven"</formula1></dataValidation><dataValidation sqref="B8 B10 B11 B12 B13 B15 B17 B18 B20 B21 B22 B23 B25 B26 B27 B28 B30 B31 B32 B33 B3 <dataValidation sqref="C8 C10 C11 C12 C13 C15 C17 C18 C20 C21 C22 C23 C25 C26 C27 C28 C30 C31 C32 C33 C34 C35 C37 C38 C39 C40 C42 C43 C45 C46 C48" showDropDown="0" showInputMessage="0" showErrorMessage="0" allowBlank="0" type="list"><formula1>"Not Started,In Progress,Performed,Not Performed"</formula1></dataValidation><dataValidation sqref="D8 D10 D11 D12 D13 D15 D17 D18 D20 D21 D22 D23 D25 D26 D27 D28 D30 D31 D3 <dataValidation sqref="E8 E10 E11 E12 E13 E15 E17 E18 E20 E21 E22 E23 E25 E26 E27 E28 E30 E31 E32 E33 E34 E35 E37 E38 E39 E40 E42 E43 E45 E46 E48" showDropDown="0" showInputMessage="0" showErrorMessage="0" allowBlank="0" type="list"><formula1>"No Exception,Exception Identified,Unable to Conclude"</formula1></dataValidation><dataValidation sqref="F8 F10 F11 F12 F13 F15 F17 F18 F20 F21 F22 F23 F25 F26 F27 F28 F30 F <dataValidation sqref="G8 G10 G11 G12 G13 G15 G17 G18 G20 G21 G22 G23 G25 G26 G27 G28 G30 G31 G32 G33 G34 G35 G37 G38 G39 G40 G42 G43 G45 G46 G48" showDropDown="0" showInputMessage="0" showErrorMessage="0" allowBlank="0" type="list"><formula1>"Unsigned,Prepared,Reviewed,Superseded"</formula1></dataValidation></dataValidations><printOptions horizontalCentered="0" verticalCentered="0"/><pageMargins left="0.25" righ definedNames><definedName name="WP_PLAN_S002_0_SOURCE_INDEX_ENTITY_NAME">'<.0> Source Index'!$B$2</definedName><definedName name="WP_PLAN_S002_0_SOURCE_INDEX_FINANCIAL_STATEMENT_DATE">'<.0> Source In definedName><definedName name="WP_PLAN_S002_0_SOURCE_INDEX_REPORTING_CURRENCY">'<.0> Source Index'!$H$2</definedName><definedName name="WP_PLAN_S002_0_SOURCE_INDEX_PERFORMANCE_MATERIALITY">'<.0> Sour definedName><definedName name="WP_PLAN_S002_0_SOURCE_INDEX_TOLERABLE_MISSTATEMENT">'<.0> Source Index'!$E$3</definedName><definedName name="WP_PLAN_S003_1_AR_LEAD_SHEET_ENTITY_NAME">'<.1> AR Lead She definedName><definedName name="WP_PLAN_S003_1_AR_LEAD_SHEET_FINANCIAL_STATEMENT_DATE">'<.1> AR Lead Sheet'!$E$2</definedName><definedName name="WP_PLAN_S003_1_AR_LEAD_SHEET_REPORTING_CURRENCY">'<.1> definedName><definedName name="WP_PLAN_S003_1_AR_LEAD_SHEET_PERFORMANCE_MATERIALITY">'<.1> AR Lead Sheet'!$B$3</definedName><definedName name="WP_PLAN_S003_1_AR_LEAD_SHEET_TOLERABLE_MISSTATEMENT">'<.1&g definedName><definedName name="WP_PLAN_S004_2_AGING_TIE_OUT_ENTITY_NAME">'<.2> Aging Tie-Out'!$B$2</definedName><definedName name="WP_PLAN_S004_2_AGING_TIE_OUT_FINANCIAL_STATEMENT_DATE">'<.2> Aging T definedName><definedName name="WP_PLAN_S004_2_AGING_TIE_OUT_REPORTING_CURRENCY">'<.2> Aging Tie-Out'!$H$2</definedName><definedName name="WP_PLAN_S004_2_AGING_TIE_OUT_PERFORMANCE_MATERIALITY">'<.2> A definedName><definedName name="WP_PLAN_S004_2_AGING_TIE_OUT_TOLERABLE_MISSTATEMENT">'<.2> Aging Tie-Out'!$E$3</definedName><definedName name="WP_PLAN_S005_3_AGING_BUCKET_TESTING_ENTITY_NAME">'<.3> Ag definedName><definedName name="WP_PLAN_S005_3_AGING_BUCKET_TESTING_FINANCIAL_STATEMENT_DATE">'<.3> Aging Bucket Testing'!$E$2</definedName><definedName name="WP_PLAN_S005_3_AGING_BUCKET_TESTING_REPORTING_C … 77 more lines
Turn 42 · bashcd /tmp/x; cat xl/tables/table1.xml; cat xl/worksheets/_rels/sheet8.xml.rels; for i in 1 2 3 4 5 6 7 8 9 10; do echo "sheet$i: $(grep -o '<mergeCell [^>]*>' xl/worksheets/sheet$i.xml | tr '\n' ' ' | head -c 600) DV:$(grep -c '<dataValidation ' xl/worksheets/sheet$i.xml) CF:$(grep -c conditionalFormatting xl/worksheets/sheet$i.xml)"; done
Output<table id="1" name="WP_AR_CONFIRMATIONS" displayName="WP_AR_CONFIRMATIONS" ref="A8:AG23" headerRowCount="1" xmlns="http://schemas.openxmlformats.org/spreadsheetml/2006/main"><autoFilter ref="A8:AG23"/><tableColumns count="33"><tableColumn id="1" name="Conf. Control #"/><tableColumn id="2" name="Customer (name)"/><tableColumn id="3" name="Contact name"/><tableColumn id="4" name="Email (if any)"/><tableColumn id="5" name="Addr. validation tested (Y/N)"/><tableColumn id="6" name="AVT result"/><tableColumn id="7" name="Invoice #"/><tableColumn id="8" name="Invoice date"/><tableColumn id="9" name="Amount to confirm"/><tableColumn id="10" name="Date request sent"/><tableColumn id="11" name="Method sent (email/physical/Confirmation.com)"/><tableColumn id="12" name="Follow-up date(s)"/><tableColumn id="13" name="Response received (Y/N)"/><tableColumn id="14" name="Hard-copy ref"/><tableColumn id="15" name="Electronic ref"/><tableColumn id="16" name="Reliability/authenticity tested (Y/N)"/><tableColumn id="17" name="Amount per confirmation"/><tableColumn id="18" name="Exception (diff)"/><tableColumn id="19" name="Resolution of exception"/><tableColumn id="20" name="Amount per subsequent receipt"/><tableColumn id="21" name="Applied to this invoice"/><tableColumn id="22" name="Credit memos / discounts"/><tableColumn id="23" name="Date of subsequent receipt"/><tableColumn id="24" name="Receipt reference #"/><tableColumn id="25" name="Date of deposit into bank"/><tableColumn id="26" name="Agreed to bank (Y/N)"/><tableColumn id="27" name="Amount per support (invoice)"/><tableColumn id="28" name="PO reference"/><tableColumn id="29" name="PO date"/><tableColumn id="30" name="BOL / Sea Waybill reference"/><tableColumn id="31" name="BOL / Waybill date"/><tableColumn id="32" name="Quantity agreed (Y/N)"/><tableColumn id="33" name="Conclusion / ET notes"/></tableColumns></table><Relationships xmlns="http://schemas.openxmlformats.org/package/2006/relationships"><Relationship Type="http://schemas.openxmlformats.org/officeDocument/2006/relationships/table" Target="/xl/tables/table1.xml" Id="rId1"/></Relationships>sheet1: <mergeCell ref="I47:Q47"/> <mergeCell ref="I16:Q16"/> <mergeCell ref="I7:Q7"/> <mergeCell ref="I24:Q24"/> <mergeCell ref="I41:Q41"/> <mergeCell ref="I19:Q19"/> <mergeCell ref="A4:Q4"/> <mergeCell ref="I36:Q36"/> <mergeCell ref="I14:Q14"/> <mergeCell ref="I9:Q9"/> <mergeCell ref="I44:Q44"/> <mergeCell ref="I29:Q29"/> DV:1 CF:1 sheet2: <mergeCell ref="A32:G32"/> <mergeCell ref="B28:D28"/> <mergeCell ref="B5:G5"/> <mergeCell ref="B23:D23"/> <mergeCell ref="B22:D22"/> <mergeCell ref="B26:D26"/> <mergeCell ref="B27:D27"/> <mergeCell ref="B4:G4"/> <mergeCell ref="B30:D30"/> <mergeCell ref="B29:D29"/> <mergeCell ref="B25:D25"/> <mergeCell ref="B24:D24"/> <mergeCell ref="B6:G6"/> DV:0 CF:0 sheet3: <mergeCell ref="B33:D33"/> <mergeCell ref="B28:D28"/> <mergeCell ref="B36:D36"/> <mergeCell ref="B34:D34"/> <mergeCell ref="B4:K4"/> <mergeCell ref="B31:D31"/> <mergeCell ref="B35:D35"/> <mergeCell ref="B32:D32"/> <mergeCell ref="A38:K38"/> <mergeCell ref="B30:D30"/> <mergeCell ref="B6:K6"/> <mergeCell ref="B29:D29"/> <mergeCell ref="B5:K5"/> DV:0 CF:0 sheet4: <mergeCell ref="B33:D33"/> <mergeCell ref="B28:D28"/> <mergeCell ref="B34:D34"/> <mergeCell ref="B4:K4"/> <mergeCell ref="B31:D31"/> <mergeCell ref="B32:D32"/> <mergeCell ref="B26:D26"/> <mergeCell ref="B27:D27"/> <mergeCell ref="B30:D30"/> <mergeCell ref="B6:K6"/> <mergeCell ref="A36:K36"/> <mergeCell ref="B29:D29"/> <mergeCell ref="B5:K5"/> DV:0 CF:0 sheet5: <mergeCell ref="B33:D33"/> <mergeCell ref="B36:D36"/> <mergeCell ref="B5:J5"/> <mergeCell ref="B37:D37"/> <mergeCell ref="B31:D31"/> <mergeCell ref="B35:D35"/> <mergeCell ref="B32:D32"/> <mergeCell ref="A39:J39"/> <mergeCell ref="B30:D30"/> <mergeCell ref="B4:J4"/> <mergeCell ref="A26:J26"/> <mergeCell ref="B29:D29"/> <mergeCell ref="B6:J6"/> <mergeCell ref="B34:D34"/> DV:0 CF:0 sheet6: <mergeCell ref="B42:D42"/> <mergeCell ref="B45:D45"/> <mergeCell ref="B5:G5"/> <mergeCell ref="B41:D41"/> <mergeCell ref="B46:D46"/> <mergeCell ref="A48:G48"/> <mergeCell ref="B40:D40"/> <mergeCell ref="B4:G4"/> <mergeCell ref="B44:D44"/> <mergeCell ref="B43:D43"/> <mergeCell ref="B39:D39"/> <mergeCell ref="B38:D38"/> <mergeCell ref="B6:G6"/> DV:0 CF:0 sheet7: <mergeCell ref="B42:D42"/> <mergeCell ref="A46:J46"/> <mergeCell ref="B36:D36"/> <mergeCell ref="B37:D37"/> <mergeCell ref="B5:J5"/> <mergeCell ref="B41:D41"/> <mergeCell ref="B40:D40"/> <mergeCell ref="B38:D38"/> <mergeCell ref="B44:D44"/> <mergeCell ref="B4:J4"/> <mergeCell ref="B43:D43"/> <mergeCell ref="B39:D39"/> <mergeCell ref="B6:J6"/> DV:0 CF:0 sheet8: <mergeCell ref="B33:D33"/> <mergeCell ref="B36:D36"/> <mergeCell ref="B37:D37"/> <mergeCell ref="B5:AG5"/> <mergeCell ref="B31:D31"/> <mergeCell ref="A39:AG39"/> <mergeCell ref="A7:K7"/> <mergeCell ref="B35:D35"/> <mergeCell ref="A26:AG26"/> <mergeCell ref="B32:D32"/> <mergeCell ref="B4:AG4"/> <mergeCell ref="Z7:AF7"/> <mergeCell ref="B30:D30"/> <mergeCell ref="L7:R7"/> <mergeCell ref="B29:D29"/> <mergeCell ref="S7:Y7"/> <mergeCell ref="B6:AG6"/> <mergeCell ref="B34:D34"/> DV:0 CF:0 sheet9: <mergeCell ref="B42:D42"/> <mergeCell ref="B36:D36"/> <mergeCell ref="B37:D37"/> <mergeCell ref="B4:E4"/> <mergeCell ref="B41:D41"/> <mergeCell ref="B6:E6"/> <mergeCell ref="B40:D40"/> <mergeCell ref="A46:E46"/> <mergeCell ref="B44:D44"/> <mergeCell ref="B5:E5"/> <mergeCell ref="B43:D43"/> <mergeCell ref="B39:D39"/> <mergeCell ref="B38:D38"/> DV:0 CF:0 sheet10: DV:0 CF:0
Turn 43 · bashcd /tmp/x; grep -o '<conditionalFormatting.*</conditionalFormatting>' xl/worksheets/sheet1.xml | head -c 3000; echo; grep -o '<dataValidation .\{0,300\}' xl/worksheets/sheet1.xml | grep -o 'formula1>[^<]*'Output<conditionalFormatting sqref="A8:Q48"><cfRule type="expression" priority="1" dxfId="0"><formula>AND($F8="Open",$P8<>"")</formula></cfRule><cfRule type="expression" priority="2" dxfId="1"><formula>OR($H8="Blocked",AND($F8="Open",$P8=""))</formula></cfRule><cfRule type="expression" priority="3" dxfId="2"><formula>$H8="Passed"</formula></cfRule><cfRule type="expression" priority="4" dxfId="3"><formula>OR($H8="Valid N/A",$H8="Recommended - Not Performed")</formula></cfRule></conditionalFormatting> formula1>"Applicable,Not Applicable - Fact Driven" formula1> formula1>"Not Started,In Progress,Performed,Not Performed" formula1> formula1>"Sufficient,Missing,Unreadable,Unreliable,Contradictory,Not Required" formula1>"No Exception,Exception Identified,Unable to Conclude" formula1> formula1>"None,Open,Adjusted,Passed,Resolved,Superseded" formula1> formula1>"Unsigned,Prepared,Reviewed,Superseded" formula1>
Turn 44 · bashcd /tmp/x; grep -o '<dataValidation .\{0,200\}' xl/worksheets/sheet1.xml | sed 's/sqref="\([A-Z]*\)[0-9].\{0,150\}formula1>/\1 => /' | cut -c1-200Output<dataValidation sqref="A8 A10 A11 A12 A13 A15 A17 A18 A20 A21 A22 A23 A25 A26 A27 A28 A30 A31 A32 A33 A34 A35 A37 A38 A39 A40 A42 A43 A45 A46 A48" showDropDown="0" showInputMessage="0" showErrorMessag <dataValidation sqref="B8 B10 B11 B12 B13 B15 B17 B18 B20 B21 B22 B23 B25 B26 B27 B28 B30 B31 B32 B33 B34 B35 B37 B38 B39 B40 B42 B43 B45 B46 B48" showDropDown="0" showInputMessage="0" showErrorMessag <dataValidation sqref="C8 C10 C11 C12 C13 C15 C17 C18 C20 C21 C22 C23 C25 C26 C27 C28 C30 C31 C32 C33 C34 C35 C37 C38 C39 C40 C42 C43 C45 C46 C48" showDropDown="0" showInputMessage="0" showErrorMessag <dataValidation sqref="D8 D10 D11 D12 D13 D15 D17 D18 D20 D21 D22 D23 D25 D26 D27 D28 D30 D31 D32 D33 D34 D35 D37 D38 D39 D40 D42 D43 D45 D46 D48" showDropDown="0" showInputMessage="0" showErrorMessag <dataValidation sqref="E8 E10 E11 E12 E13 E15 E17 E18 E20 E21 E22 E23 E25 E26 E27 E28 E30 E31 E32 E33 E34 E35 E37 E38 E39 E40 E42 E43 E45 E46 E48" showDropDown="0" showInputMessage="0" showErrorMessag <dataValidation sqref="F8 F10 F11 F12 F13 F15 F17 F18 F20 F21 F22 F23 F25 F26 F27 F28 F30 F31 F32 F33 F34 F35 F37 F38 F39 F40 F42 F43 F45 F46 F48" showDropDown="0" showInputMessage="0" showErrorMessag <dataValidation sqref="G8 G10 G11 G12 G13 G15 G17 G18 G20 G21 G22 G23 G25 G26 G27 G28 G30 G31 G32 G33 G34 G35 G37 G38 G39 G40 G42 G43 G45 G46 G48" showDropDown="0" showInputMessage="0" showErrorMessag
Turn 45 · bashcd /tmp/x; python3 -c " import re s=open('xl/worksheets/sheet1.xml').read() for m in re.finditer(r'<dataValidation sqref=\"([A-Z])8.*?</dataValidation>',s): f=re.search(r'<formula1>(.*?)</formula1>',m.group(0)); print(m.group(1), f.group(1) if f else None) "OutputA "Applicable,Not Applicable - Fact Driven" B "Required,Recommended" C "Not Started,In Progress,Performed,Not Performed" D "Sufficient,Missing,Unreadable,Unreliable,Contradictory,Not Required" E "No Exception,Exception Identified,Unable to Conclude" F "None,Open,Adjusted,Passed,Resolved,Superseded" G "Unsigned,Prepared,Reviewed,Superseded"
- 10Recompute the reserve
Nets the client's February receipts out of each aging pool before applying management's loss rates, so the 1–30 day pool falls from $151,874 to $15,771.
Turns 46–47 · pandas
Turn 46 · bashcd /workspace; python3 - <<'EOF' import pandas as pd ag=pd.read_pickle('/tmp/ag.pkl'); cr=pd.read_pickle('/tmp/cr.pkl') m=ag.merge(cr[['Invoice applied','Amount']],left_on='Invoice',right_on='Invoice applied',how='left').fillna({'Amount':0}) rates={'current':0,'1-30':.05,'31-60':.2,'61-90':.5,'over-90':1} g=m.groupby('Aging Bucket').agg(exp=('Open Balance','sum'),col=('Amount','sum')) g['res']=g.exp-g.col; g['rate']=g.index.map(rates); g['mg']=(g.exp*g.rate).round(2); g['low']=(g.res*g.rate).round(2); g['cap']=g[['mg','res']].min(axis=1) print(g, g.sum()) # re-age residual at 2/17 d=pd.Timestamp('2026-02-17') r=m[m.Amount==0].copy(); r['dpd2']=(d-r['Due Date']).dt.days.clip(lower=0) b=lambda x:'current' if x<=0 else '1-30' if x<=30 else '31-60' if x<=60 else '61-90' if x<=90 else 'over-90' r['b2']=r.dpd2.apply(b); r['res2']=r['Open Balance']*r.b2.map(rates) print(r[['Invoice','Open Balance','Aging Bucket','dpd2','b2','res2']]); print(r.res2.sum()) … 1 more linesOutputexp col res ... mg low cap Aging Bucket ... 1-30 151874.00 136102.85 15771.15 ... 7593.70 788.56 7593.70 31-60 89528.55 84837.02 4691.53 ... 17905.71 938.31 4691.53 61-90 12066.87 8895.51 3171.36 ... 6033.44 1585.68 3171.36 current 571578.33 457269.12 114309.21 ... 0.00 0.00 0.00 over-90 40246.60 27253.08 12993.52 ... 40246.60 12993.52 12993.52 [5 rows x 7 columns] exp 865294.35 col 714357.58 res 150936.77 rate 1.75 mg 71779.45 low 16306.07 … 20 more lines
Turn 47 · bashcd /workspace; python3 - <<'EOF' import pandas as pd ag=pd.read_pickle('/tmp/ag.pkl'); cr=pd.read_pickle('/tmp/cr.pkl') m=ag.merge(cr[['Invoice applied','Amount']],left_on='Invoice',right_on='Invoice applied',how='left').fillna({'Amount':0}) rates={'current':0,'1-30':.05,'31-60':.2,'61-90':.5,'over-90':1} d=pd.Timestamp('2026-02-17') r=m[m.Amount==0].copy(); r['dpd2']=(d-r['Due Date']).dt.days.clip(lower=0) b=lambda x:'current' if x<=0 else '1-30' if x<=30 else '31-60' if x<=60 else '61-90' if x<=90 else 'over-90' r['b2']=r.dpd2.apply(b); r['res2']=r['Open Balance']*r.b2.map(rates); r['low']=r['Open Balance']*r['Aging Bucket'].map(rates) g=r.groupby('Aging Bucket')[['Open Balance','low','res2']].sum(); g['G']=g.res2-g.low; print(g.round(2)); print(g.sum().round(2)) EOFOutputOpen Balance low res2 G Aging Bucket 1-30 15771.15 788.56 3154.23 2365.67 31-60 4691.53 938.31 2345.76 1407.46 61-90 3171.36 1585.68 3171.36 1585.68 current 114309.21 0.00 10504.81 10504.81 over-90 12993.52 12993.52 12993.52 0.00 Open Balance 150936.77 low 16306.06 res2 32169.68 G 15863.62 dtype: float64
- 11Fill the workpaper
Writes each tab with its own build script and signs off the procedures.
Turns 48–60 · openpyxl
Turn 48 · bashmkdir -p /tmp/build; cat > /tmp/build/helpers.py <<'EOF' import copy from openpyxl.worksheet.cell_range import CellRange def insert_rows_keep(ws, idx, n, style_row): """Insert n rows before idx; shift merged cells; copy style from style_row (pre-insert index).""" merged=[CellRange(m.coord) for m in ws.merged_cells.ranges] for m in list(ws.merged_cells.ranges): ws.merged_cells.remove(m) heights={r:ws.row_dimensions[r].height for r in range(idx, ws.max_row+1)} ws.insert_rows(idx, n) for r,h in sorted(heights.items(), reverse=True): ws.row_dimensions[r+n].height=h for m in merged: if m.min_row>=idx: … 11 more linesOutputok
Turn 49 · bashcat > /tmp/build/build1.py <<'EOF' import sys; sys.path.insert(0,'/tmp/build') import openpyxl, datetime as dt, pandas as pd from helpers import insert_rows_keep wb=openpyxl.load_workbook('/workspace/accounts_receivable_workpaper.xlsx') PM=48660; TM=48660 for n in wb.sheetnames[1:9]: ws=wb[n]; ws['B3']=PM; ws['E3']=TM D=dt.datetime(2026,2,19) PREP='Audit Senior B377' # ---------------- <.0> Source Index ws=wb['<.0> Source Index'] insert_rows_keep(ws,21,2,20) … 41 more linesOutputok
Turn 50 · bashcat > /tmp/build/build2.py <<'EOF' import sys; sys.path.insert(0,'/tmp/build') import openpyxl, datetime as dt, pandas as pd from helpers import insert_rows_keep wb=openpyxl.load_workbook('/tmp/build/stage1.xlsx') ag=pd.read_pickle('/tmp/ag.pkl') b6=lambda d:'current' if d<=0 else '1-30' if d<=30 else '31-60' if d<=60 else '61-90' if d<=90 else '91-120' if d<=120 else 'Over 120' ag['b6']=ag['dpd'].apply(b6) cust=ag.groupby('Customer')['Open Balance'].sum().sort_values(ascending=False) ws=wb['<.2> Aging Tie-Out'] n=len(cust) # 30 insert_rows_keep(ws,23,n-14,22) cols={'current':'B','1-30':'C','31-60':'D','61-90':'E','91-120':'F','Over 120':'G'} for i,(c,tot) in enumerate(cust.items()): … 28 more linesOutputok 39
Turn 51 · bashcat > /tmp/build/build3.py <<'EOF' import sys; sys.path.insert(0,'/tmp/build') import openpyxl, datetime as dt, pandas as pd wb=openpyxl.load_workbook('/tmp/build/stage2.xlsx') ag=pd.read_pickle('/tmp/ag.pkl') b6=lambda d:'current' if d<=0 else '1-30' if d<=30 else '31-60' if d<=60 else '61-90' if d<=90 else '91-120' if d<=120 else 'Over 120' sel=['INV-53005','INV-52948','INV-52990','INV-52662','INV-52679','INV-52664','INV-52674','INV-53039','INV-53085','INV-53106','INV-53137','INV-53142','INV-53116','INV-53186','INV-53187','INV-53203'] ws=wb['<.3> Aging Bucket Testing'] for i,inv in enumerate(sel): r=9+i; a=ag[ag.Invoice==inv].iloc[0] ws[f'A{r}']=inv; ws[f'B{r}']=a.Customer ws[f'C{r}']=a['Invoice Date'].to_pydatetime(); ws[f'D{r}']=a['Due Date'].to_pydatetime() ws[f'C{r}'].number_format='mm/dd/yyyy'; ws[f'D{r}'].number_format='mm/dd/yyyy' ws[f'E{r}']=float(a['Open Balance']) … 11 more linesOutputok
Turn 52 · bashcat > /tmp/build/build4.py <<'EOF' import sys; sys.path.insert(0,'/tmp/build') import openpyxl, datetime as dt wb=openpyxl.load_workbook('/tmp/build/stage3.xlsx') ws=wb['<.5> CECL Expected Credit Loss'] pools=[('current',571578.33,457269.12,0.0,10504.81,0.0), ('1-30',151874.00,136102.85,0.05,2365.67,7593.70), ('31-60',89528.55,84837.02,0.20,1407.46,17905.71), ('61-90',12066.87,8895.51,0.50,1585.68,6033.44), ('91-120',3586.75,3586.75,1.0,0.0,3586.75), ('Over 120',36659.85,23666.33,1.0,0.0,36659.85)] for i,(p,b,c,e,g,res) in enumerate(pools): r=10+i ws[f'B{r}']=b; ws[f'C{r}']=c; ws[f'E{r}']=e; ws[f'E{r}'].number_format='0.00%'; ws[f'G{r}']=g; ws[f'I{r}']=res … 62 more linesOutputok
Turn 53 · bashcat > /tmp/build/build4b.py <<'EOF' import openpyxl wb=openpyxl.load_workbook('/tmp/build/stage4.xlsx') ws=wb['<.5> CECL Expected Credit Loss'] notes=[ws[c].value for c in ['K10','K11','K12','K14','K16']] for c in ['K8','K10','K11','K12','K14','K16']: ws[c]=None ws['A17']='Notes: '+' | '.join(notes) lb=[ws['G20'].value, ws['G23'].value]; ws['G20']=None; ws['G23']=None ws['A26']='Lookback notes: '+' | '.join(lb) wb.save('/tmp/build/stage4.xlsx') print(ws.max_column) EOF python3 /tmp/build/build4b.pyOutput11
Turn 54 · bashcd /tmp/build; python3 - <<'EOF' import openpyxl wb=openpyxl.load_workbook('/tmp/build/stage4.xlsx') ws=wb['<.5> CECL Expected Credit Loss'] for k in list(ws._cells): if k[1]==11: del ws._cells[k] print(ws.max_column, ws.dimensions) wb.save('/tmp/build/stage4.xlsx') EOFOutput10 A1:J46
Turn 55 · bashcd /workspace; python3 - <<'EOF' import openpyxl,pandas as pd ws=openpyxl.load_workbook('pbc_package/revenue/Customer Invoice Register 2025.xlsx').active rows=list(ws.iter_rows(values_only=True)) for r in rows: if r[0] in ('INV-52674','INV-52662','INV-53186'): print(r) EOFOutput('INV-53186', 'Zaxvento Vixler Holdings, Inc.', datetime.datetime(2025, 11, 23, 0, 0), 'PO-25-7060', 'SO-2025-30060', 'QT-25-1060', 'Finished metal plate B; ASTM A1011; cut to length', 0.68, 22861.49, 'net 30', 1002.63, 'Taxable', '6.79%', '—', 1554.58, 777.29, 15771.15) ('INV-52662', 'Zaxvento Quelvale Solutions, Inc.', datetime.datetime(2024, 11, 17, 0, 0), 'Cpo reference 425', 'So reference 425', 'Q reference 425', 'Finished metal coil A', 1, 16806.06, 'net 30', 0, 'Resale Exempt', '0.00%', 'EXEMPT-Q4N-136405-36', 0, 0, 16806.06) ('INV-52674', 'Zephirax Vorquix Solutions, Inc.', datetime.datetime(2024, 11, 21, 0, 0), 'Cpo reference 428', 'So reference 428', 'Q reference 428', 'Finished metal coil A', 1, 15677.75, 'net 60', 0, 'Resale Exempt', '0.00%', 'EXEMPT-Q4N-263109-12', 0, 0, 15677.75)Turn 56 · bashcat > /tmp/build/build5.py <<'EOF' import sys; sys.path.insert(0,'/tmp/build') import openpyxl, datetime as dt, pandas as pd from helpers import insert_rows_keep wb=openpyxl.load_workbook('/tmp/build/stage4.xlsx') ag=pd.read_pickle('/tmp/ag.pkl'); cr=pd.read_pickle('/tmp/cr.pkl'); rd=pd.read_pickle('/tmp/rd.pkl') irw=openpyxl.load_workbook('/workspace/pbc_package/revenue/Customer Invoice Register 2025.xlsx').active ir={r[0]:r for r in irw.iter_rows(values_only=True) if r[0] and str(r[0]).startswith('INV-')} slw=openpyxl.load_workbook('/workspace/pbc_package/revenue/Shipment and Delivery Log 2025.xlsx').active sl={r[6]:r for r in slw.iter_rows(min_row=6,values_only=True) if r[0]} ws=wb['<.6> Confirmation & Clearance'] insert_rows_keep(ws,24,6,23) ws.tables['WP_AR_CONFIRMATIONS'].ref='A8:AG29' ws.tables['WP_AR_CONFIRMATIONS'].autoFilter.ref='A8:AG29' … 90 more linesOutputok 17
Turn 57 · bashcat > /tmp/build/build6.py <<'EOF' import openpyxl, pandas as pd wb=openpyxl.load_workbook('/tmp/build/stage5.xlsx') wb['<.6> Confirmation & Clearance']['AA30']='=SUM(AA13:AA29)' ws=wb['<.7> Ratios & Disclosures'] REV=4325372.12; REVPY=4127814.53; AR=865294.35; ARPY=497599.56; AL=71779.45; ALPY=46510.12; BD=25269.33 ws['B9']=f'=B13/{REV}*365'; ws['C9']=f'=C13/{REVPY}*365' ws['E9']='Gross AR / revenue (S-01/S-02 4010) x 365: 73.0 vs 44.0 days (+29 days). AR includes sales tax (2037 212,010.91) - ex-tax DSO ~55 days, still a marked increase. Driven by Nov-Dec 2025 billings of 680,236 / 664,824 vs Jan-Oct average ~321,000/month (S-11). ISS-AR-05.' ws['B10']=f'={REV}/B13'; ws['C10']=f'={REVPY}/C13' ws['E10']='Revenue / year-end gross AR: 5.0x vs 8.3x - slower turnover; consistent with DSO finding.' ws['B11']=f'={AL}/B13'; ws['C11']=f'={ALPY}/C13' ws['E11']='8.3% vs 9.3%. Coverage high relative to actual loss experience (0 write-offs in 2025; 82.6% collected by 02/17/26) - see <.4>/<.5> ISS-AR-02.' ws['B12']=f'={BD}/{REV}'; ws['C12']=f'=0/{REVPY}' ws['E12']='0.58% vs 0.00% (PY provision 0 per S-02). Provision 25,269.33 with no write-offs increases allowance.' … 27 more linesOutput0.4258859658565897
Turn 58 · bashcd /tmp/build; python3 - <<'EOF' import openpyxl wb=openpyxl.load_workbook('stage6.xlsx'); ws=wb['<.7> Ratios & Disclosures'] ws['E26']=ws['E26'].value.replace('45.1%','42.6%') ws['E9']=ws['E9'].value.replace('ex-tax DSO ~55 days','excluding the ~4.7% sales-tax component DSO is ~70 days') wb.save('stage6.xlsx') EOFOutputTurn 59 · bashcat > /tmp/build/build7.py <<'EOF' import openpyxl, datetime as dt wb=openpyxl.load_workbook('/tmp/build/stage6.xlsx') ws=wb['Library Procedures'] D=dt.datetime(2026,2,19); P='Audit Senior B377' PASS=('Performed','Sufficient','No Exception','None','Prepared','Passed') def S(ex,ev,res,iss,out): return (ex,ev,res,iss,'Prepared',out) OPENX=lambda ev='Sufficient': S('Performed',ev,'Exception Identified','Open','Open Exception') BLOCK=lambda ev='Missing': S('Performed',ev,'Unable to Conclude','Open','Blocked') proc={ 8:(PASS,'','S-01 to S-15 (<.0> Source Index)','', 'Indexed 15 AR sources on <.0> with provider, date, format, tabs used and limitations. Limitations: (1) S-04 receipts all dated 02/17/26 and no Feb-2026 bank statement - S-05 Jan-26 shows zero deposits (ISS-AR-01); (2) S-08 allowance workbook and S-07 evidence control rated Not Reliable in PL-CAII - used as reference only, key data re-derived from S-03/S-04/S-06/S-11/S-12; (3) no 2026 credit-memo extract (ISS-AR-07); (4) PO dates not available in any source. Materiality per Planning Context (PM/TM 48,660) applied to all tabs, superseding PL-MM (32,500/29,300).'), 10:(PASS,'','S-01; S-02; S-12; S-13','', 'Agreed gross AR 865,294.35 (1010), allowance 71,779.45 (1011) and net AR 793,514.90 to TB 12/31/25 (S-01, xlsx and csv export), to the GL/JE account reconciliation (S-12: opening 497,599.56 + Dr 4,557,486.09 - Cr 4,189,791.30 = 865,294.35) and to Note 3 / balance sheet (S-13). Difference 0 (<.1> B25).'), … 70 more linesOutputTraceback (most recent call last): File "/tmp/build/build7.py", line 24, in <module> 18:(S('Not Performed','Not Required','No Exception','None','Prepared','Valid N/A'),'NA-FACT','FACT:/S-03/ar_aging/reage_differences = 0 (83 of 83 items; <.3>); FACT:/S-15/PL-CAII/AR_Aging_12_31_25/reliance = "Reliable"','', ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ TypeError: S() takes 5 positional arguments but 6 were givenTurn 60 · bashcd /tmp/build; sed -i "s/S('Not Performed','Not Required','No Exception','None','Prepared','Valid N\/A')/S('Not Performed','Not Required','No Exception','None','Valid N\/A')/; s/S('Performed','Missing','Unable to Conclude','Open','Prepared','Blocked')/S('Performed','Missing','Unable to Conclude','Open','Blocked')/; s/S('Performed','Unreliable','Exception Identified','Open','Prepared','Open Exception')/S('Performed','Unreliable','Exception Identified','Open','Open Exception')/" build7.py; python3 build7.pyOutputsaved
- 12Recalculate and verify
Recalculates in LibreOffice, checks for formula errors and confirms every tie-out difference is zero.
Turns 61–63 · libreoffice, openpyxl
Turn 61 · bashcd /tmp && rm -rf recalc && mkdir recalc && cp /workspace/accounts_receivable_workpaper.xlsx recalc/ && cd recalc && soffice --headless --convert-to xlsx:"Calc MS Excel 2007 XML" --outdir out accounts_receivable_workpaper.xlsx >/dev/null 2>&1; python3 - <<'EOF' import openpyxl wb=openpyxl.load_workbook('/tmp/recalc/out/accounts_receivable_workpaper.xlsx',data_only=True) def show(s,cells): ws=wb[s]; print(s,[ (c,ws[c].value) for c in cells]) show('<.1> AR Lead Sheet',['G9','I9','J9','G10','I10','J10','E19','F19','G19','H19','B23','B24','B25','C23','C24','C25']) show('<.2> Aging Tie-Out',['B39','C39','D39','E39','F39','G39','H39','I39','J39','J9','J38']) show('<.3> Aging Bucket Testing',['F9','F12','F24']) show('<.4> Allowance for Doubtful',['B12','B14','E26','B30','B31','B32','B34','F18']) show('<.5> CECL Expected Credit Loss',['D10','F10','H10','J10','B16','C16','D16','F16','H16','I16','J16','D20','D25','F23','F25']) show('<.6> Confirmation & Clearance',['R10','R11','R12','R13','R14','I30','Q30','R30','T30','AA30']) show('<.7> Ratios & Disclosures',['B9','C9','D9','B10','C10','B11','C11','B12','B14','C14','D14','C18','C26']) for ws in wb: for row in ws.iter_rows(): … 3 more linesOutput<.1> AR Lead Sheet [('G9', 865294.35), ('I9', 367694.79), ('J9', 0.738937128481384), ('G10', -71779.45), ('I10', -25269.33), ('J10', 0.543308209052137), ('E19', 865294.35), ('F19', 71779.45), ('G19', 793514.9), ('H19', 451089.44), ('B23', 793514.9), ('B24', 793514.9), ('B25', 0), ('C23', 451089.44), ('C24', 451089.44), ('C25', 0)] <.2> Aging Tie-Out [('B39', 571578.33), ('C39', 151874), ('D39', 89528.55), ('E39', 12066.87), ('F39', 3586.75), ('G39', 36659.85), ('H39', 865294.35), ('I39', 865294.35), ('J39', 0), ('J9', 0), ('J38', 0)] <.3> Aging Bucket Testing [('F9', 130), ('F12', 409), ('F24', 38)] <.4> Allowance for Doubtful [('B12', 71779.45), ('B14', 0), ('E26', 0), ('B30', 32169.6835), ('B31', 0), ('B32', 32169.6835), ('B34', -39609.7665), ('F18', 0)] <.5> CECL Expected Credit Loss [('D10', 114309.21), ('F10', 0), ('H10', 10504.81), ('J10', 10504.81), ('B16', 865294.35), ('C16', 714357.58), ('D16', 150936.77), ('F16', 16306.0635), ('H16', 32169.6835), ('I16', 71779.45), ('J16', -39609.7665), ('D20', 0.314029959810011), ('D25', 0.0261124025109669), ('F23', 0.0934689733246549), ('F25', 0.0934689733246549)] <.6> Confirmation & Clearance [('R10', 0), ('R11', 0), ('R12', 0), ('R13', 0), ('R14', None), ('I30', 174859.89), ('Q30', 174859.89), ('R30', 0), ('T30', 226886.92), ('AA30', 262039.93)] <.7> Ratios & Disclosures [('B9', 73.0185586321299), ('C9', 44.0000000193807), ('D9', 29.0185586127492), ('B10', 4.99872918388985), ('C10', 8.29545454180064), ('B11', 0.082953794856051), ('C11', 0.0934689733246549), ('B12', 0.00584211700148472), ('B14', 793514.9), ('C14', 451089.44), ('D14', 342425.46), ('C18', 0.0798605353195707), ('C26', 0.57411403414341)]Turn 62 · bashcd /tmp/build; python3 - <<'EOF' import openpyxl f='/workspace/accounts_receivable_workpaper.xlsx' wb=openpyxl.load_workbook(f) rep={'16,306.07':'16,306.06','32,169.69':'32,169.68','39,609.76':'39,609.77','55,473.38':'55,473.39'} n=0 for ws in wb: for row in ws.iter_rows(): for c in row: if isinstance(c.value,str) and not c.value.startswith('='): v=c.value for a,b in rep.items(): v=v.replace(a,b) if v!=c.value: c.value=v; n+=1 wb.save(f); print(n) … 8 more linesOutput8 8 Performed Sufficient No Exception None Passed | PROC:PROC-ACCOUNTS-RECEIVABLE; WINDOW:WIN-CONFIRMATION-CONTROL 10 Performed Sufficient No Exception None Passed | PROC:PROC-ACCOUNTS-RECEIVABLE 11 Performed Sufficient No Exception None Passed | PROC:PROC-ACCOUNTS-RECEIVABLE 12 Performed Sufficient No Exception None Passed | PROC:PROC-ACCOUNTS-RECEIVABLE 13 Performed Sufficient Exception Identified Open Open Exception | PROC:PROC-ACCOUNTS-RECEIVABLE; ISS-AR-05 15 Performed Sufficient No Exception None Passed | PROC:PROC-ACCOUNTS-RECEIVABLE 17 Performed Sufficient No Exception None Passed | PROC:PROC-ACCOUNTS-RECEIVABLE 18 Not Performed Not Required No Exception None Valid N/A | PROC:PROC-ACCOUNTS-RECEIVABLE 20 Performed Sufficient No Exception None Passed | PROC:PROC-ACCOUNTS-RECEIVABLE 21 Performed Sufficient No Exception None Passed | PROC:PROC-ACCOUNTS-RECEIVABLE 22 Performed Sufficient No Exception None Passed | PROC:PROC-ACCOUNTS-RECEIVABLE 23 Performed Sufficient Exception Identified Open Open Exception | PROC:PROC-ACCOUNTS-RECEIVABLE; ISS-AR-02; ISS-AR-01 25 Performed Unreliable Exception Identified Open Open Exception | PROC:PROC-ACCOUNTS-RECEIVABLE; ISS-AR-02 … 18 more lines
Turn 63 · bashcd /tmp; python3 - <<'EOF' import openpyxl wb=openpyxl.load_workbook('/workspace/accounts_receivable_workpaper.xlsx') for n in ['<.0> Source Index','<.2> Aging Tie-Out','<.6> Confirmation & Clearance']: ws=wb[n]; print(n, sorted(str(m) for m in ws.merged_cells.ranges)[:30]) for r in range(ws.max_row-16, ws.max_row+1): v=ws.cell(r,1).value if v: print(' ',r,str(v)[:70]) print(wb['<.6> Confirmation & Clearance'].tables['WP_AR_CONFIRMATIONS'].ref) print([ (n,wb[n]['B3'].value,wb[n]['E3'].value) for n in wb.sheetnames[1:9]]) EOFOutput<.0> Source Index ['A34:G34', 'B24:D24', 'B25:D25', 'B26:D26', 'B27:D27', 'B28:D28', 'B29:D29', 'B30:D30', 'B31:D31', 'B32:D32', 'B4:G4', 'B5:G5', 'B6:G6'] 18 S-11 19 S-12 20 S-13 21 S-14 22 S-15 23 TM Legends 24 TB 25 GL 26 CF 27 V 28 SR 29 R 30 F … 36 more lines
The completed workpaper, tab by tab. Highlighted cells were graded. Red cells failed.
Recompute expected credit losses using pooled aging x historical loss rates, layer in forward-looking adjustments, and compare to the recorded allowance.
| Pool | AR balance | Credits / adj | Loss rate | Forward-looking adj | Expected reserve | Per management |
|---|---|---|---|---|---|---|
| Current | 571,578.33 | 457,269.12 | 0.00% | 10,504.81 | 10,504.81 | 0.00 |
| 1-30 | 151,874.00 | 136,102.85 | 5.00% | 2,365.67 | 3,154.23 | 7,593.70 |
| 31-60 | 89,528.55 | 84,837.02 | 20.00% | 1,407.46 | 2,345.77 | 17,905.71 |
| 61-90 | 12,066.87 | 8,895.51 | 50.00% | 1,585.68 | 3,171.36 | 6,033.44 |
| 91-120 | 3,586.75 | 3,586.75 | 100.00% | 0.00 | 0.00 | 3,586.75 |
| Over 120 | 36,659.85 | 23,666.33 | 100.00% | 0.00 | 12,993.52 | 36,659.85 |
| Total | 865,294.35 | 714,357.58 | 32,169.68 | 71,779.45 |
Summarize the AR population and tie gross AR, allowance and net AR to the trial balance; compute CY/PY movement.
| Account | Description | Gross AR | Allowance | Net AR | Net AR (PY) |
|---|---|---|---|---|---|
| 1010 | Accounts receivable – trade | 865,294.35 | 865,294.35 | 497,599.56 | |
| 1011 | Allowance for credit losses (contra) | 71,779.45 | -71,779.45 | -46,510.12 | |
| 865,294.35 | 71,779.45 | 793,514.90 | 451,089.44 |
Reconcile the year-end aging / open-item support to the lead sheet, stratify by bucket, and foot.
| Customer | Current | 1–30 | 31–60 | 61–90 | 91–120 | Over 120 | Per report |
|---|---|---|---|---|---|---|---|
Zaxvento Quelvale Solutions, Inc. | 43,565.50 | 6,343.27 | 12,471.68 | 6,722.42 | 69,102.87 | ||
Quoxmark Vorquex Services, LLC | 28,229.13 | 29,184.95 | 57,414.08 | ||||
Quovixen Zaxburg Solutions, Inc. | 14,072.96 | 30,587.87 | 3,682.11 | 48,342.94 | |||
Zaxvento Vixler Holdings, Inc. | 10,919.82 | 31,906.53 | 42,826.35 | ||||
Zixmantel Veltman Holdings, Inc. | 39,918.81 | 39,918.81 | |||||
Total — ties to lead gross AR | 571,578.33 | 151,874.00 | 89,528.55 | 12,066.87 | 3,586.75 | 36,659.85 | 865,294.35 |
Confirm AR directly with significant customers (with a control log and reliability testing); for non-replies, perform alternative procedures — subsequent bank-cleared receipt plus invoice, purchase order and bill of lading support.
| Control # | Customer | Amount to confirm | Sent | Per confirmation |
|---|---|---|---|---|
Confirmation reference 5F007F37B2 | Zaxvento Quelvale Solutions, Inc. | 69,102.87 | 2026-01-08 | 69,102.87 |
Confirmation reference B9D5586C7E | Quoxmark Vorquex Services, LLC | 57,414.08 | 2026-01-07 | 57,414.08 |
Confirmation reference 6A36B133Ca | Quovixen Zaxburg Solutions, Inc. | 48,342.94 | 2026-01-06 | 48,342.94 |
PROC-Confirmation reference Confirm:INV-53221 | Zaxvento Quelvale Solutions, Inc. | 6,343.27 | 2026-01-08 | 6,343.27 |
PROC-Confirmation reference Confirm:INV-53304 | Vexmultix Quorland Services, LLC | 5,070.90 | Not sent | |
PROC-Confirmation reference Confirm:INV-53323 | Voraxive Zixford Services, LLC | 11,084.84 | Not sent | |
PROC-Confirmation reference Confirm:INV-53299 | Vaxilume Vultane Group, LLC | 8,552.75 | Not sent | |
PROC-Confirmation reference Confirm:INV-53186 | Zaxvento Vixler Holdings, Inc. | 15,771.15 | Not sent | |
PROC-Confirmation reference Confirm:INV-53291 | Vorquine Quilmont Group, LLC | 3,704.11 | Not sent | |
Totals / response rate | 174,859.89 | 174,859.89 |
Compute AR analytics and evaluate concentration and disclosure matters.
| Metric | CY | PY | Note |
|---|---|---|---|
| Days sales outstanding (DSO) | 73.02 | 44.00 | Gross AR / revenue (S-01/S-02 4010) x 365: 73.0 vs 44.0 days (+29 days). AR includes sales tax (2037 212,010.91) – excluding the ~4.7% sales-tax component DSO is ~70 days, still a marked increase. Driven by Nov-Dec 2025 billings of 680,236 / 664,824 vs Jan-Oct average ~321,000/month (S-11). ISS-AR-05. |
| AR turnover | 5.00 | 8.30 | Revenue / year-end gross AR: 5.0x vs 8.3x – slower turnover; consistent with DSO finding. |
| Allowance as % of gross AR | 8.30% | 9.35% | 8.3% vs 9.3%. Coverage high relative to actual loss experience (0 write-offs in 2025; 82.6% collected by 02/17/26) – see <.4>/<.5> ISS-AR-02. |
| Bad-debt expense as % of sales | 0.58% | 0.00% | 0.58% vs 0.00% (PY provision 0 per S-02). Provision 25,269.33 with no write-offs increases allowance. |
| Gross AR | 865,294.35 | 497,599.56 | TB 1010 (S-01/S-02). +367,694.79 / +73.9% vs revenue +4.8%. |
| Net AR | 793,514.90 | 451,089.44 | Per <.1>: 793,514.90 vs 451,089.44 (+75.9%). |
Agent’s closing summary
I've completed the AR workpaper and saved it to /workspace/accounts_receivable_workpaper.xlsx. Balances tie out, but I can't conclude on AR yet: seven issues are open, and the most serious is that the recorded allowance looks overstated by at least $39,609.77. That estimate depends on the February customer receipts being genuine, and they aren't matched to a bank statement yet. I recalculated the workbook in LibreOffice: no formula errors, and every tie-out difference is zero.
Materiality: I used the Planning Context figures on every tab: performance materiality and tolerable misstatement of $48,660 (overall $64,880), individually significant items at $16,300, and clearly trivial at $3,244. These replace the planning folder's $32,500 / $29,300.
What agrees
- Balances: Gross AR of $865,294.35, the allowance of $71,779.45 and net AR of $793,514.90 agree to the trial balance, the general ledger, the aging and the financial statement notes. Prior year agrees at $497,599.56, $46,510.12 and $451,089.44.
- Account coding: There is no account 6008, and no receivables are coded to any account other than 1010.
- Aging: All 83 open invoices re-age correctly from due date. Because the aging is reliable, procedure 8 (request a corrected aging) is marked not applicable.
- Allowance roll-forward: Beginning balance plus the $25,269.33 provision, with no write-offs or recoveries, agrees to the trial balance. No customer-specific reserves are needed.
- Confirmations: All three sent were returned and agree with no differences, covering 20.2% of AR.
- Supporting documents: I vouched 17 other items to invoice, PO, shipping reference, signed delivery and quantity. These are the five unconfirmed planned selections, the ten items of $16,300 or more, and one invoice from 2024.
- Other disclosures: No customer is 10% or more of AR (the largest is 8.0%). There are no related-party receivables and no credit balances.
Open issues (ISS-AR-01 to 07)
- Receipts not agreed to bank: All 67 subsequent receipts ($714,357.58) are dated 2/17/26. The January bank statement shows no deposits at all, and no February statement was provided.
- Allowance appears overstated:
- My range is $16,306.06 to $32,169.68 against $71,779.45 recorded; the gap to the top of the range is 81% of performance materiality.
- The over-90 pool is reserved at 100% although 67.7% of it was collected after year end.
- Last year's $46,510 allowance was followed by no write-offs in 2025.
- Management's loss history is internally inconsistent (write-offs exceed the balances they relate to), and planning rates that workbook not reliable.
- This may indicate management bias and should go to the manager before anything is posted to the unadjusted differences schedule.
- Confirmations not sent as planned: Requests went out about four weeks late, and none are evidenced for five of the six planned selections, so I used alternative procedures for those.
- Email confirmation reply: One reply came by email rather than mail or fax, and the file doesn't support the authenticity check.
- Year-end AR spike: Days sales outstanding rose from 44 to 73, and November–December billings were about twice the normal monthly level. This is a possible channel-stuffing indicator and has been referred to the revenue team.
- Pledged AR disclosure: Receivables are collateral under the bank's blanket lien, but Note 5 doesn't say so explicitly.
- Credit memos: No 2026 credit-memo listing was provided to test cutoff.
Changes to the template:
- I added rows to three tabs: 2 on Source Index, 16 on Aging Tie-Out (one per customer), and 6 on Confirmation & Clearance. The confirmation table range now runs to row 29. No columns or headers were changed.
- The Library Procedures tab is marked prepared by Audit Senior B377 on 2/19/2026 and is unreviewed. The overall conclusion (procedure 31) is "Unable to Conclude" until these issues are cleared.
Graded by the released grader: exact checks on key balances, and a GPT-5.6 Luna judge where equivalent answers are allowed. A task passes only if every criterion does.
Why it failed: before applying management's 5% loss rate to the 1–30 day pool, the agent subtracted $136,102.85 of February receipts taken from the client's own cash-receipts listing, which it hadn't matched to a bank statement. That cut the reserve from $7,593.70 to $3,154.23. Every other check passed.
Amounts are rightKey balances and totals agree to the evidence.10/11
- Total gross receivablesPassed
The lead sheet totals gross AR at $865,294.35, matching the trial balance.
- Open the allowance roll-forwardPassed
The roll-forward starts from the prior-year allowance of $46,510.12.
- Total the current bucketPassed
The aging tie-out totals current balances at $571,578.33.
- Foot the overdue bucketsPassed
The 1–30 day bucket totals $151,874.00 and the 31–60 day bucket $89,528.55.
- Agree the aging to the reportPassed
The aging report total of $865,294.35 is recorded on the tie-out.
- Recompute the 1–30 day reserveFailed
The expected reserve is $3,154.23, not $7,593.70 (5% of the $151,874 year-end pool). The agent first netted out $136,102.85 of client-reported receipts it hadn't agreed to bank.
- Reperform the loss historyPassed
Write-off rates for 2022–2024 are recomputed from every cohort supplied.
- Record a confirmed balancePassed
Selected invoice INV-53221 is recorded as confirmed at $6,343.27, within Zaxvento Quelvale's $69,102.87 reply.
- Total only the requests sentPassed
The confirmation total is $174,859.89: the three requests actually sent.
- Compute allowance as a share of receivablesPassed
The allowance is 8.3% of gross AR.
- Size the largest customerPassed
The largest customer holds 7.99% of gross AR.
Professional judgmentClaims stay within what the evidence supports.2/2
- Don't treat a client receipt as bank evidencePassed
INV-53304's receipt is marked not agreed to bank, because the February 2026 bank statement wasn't provided.
- Flag the missing credit-memo extractPassed
The subsequent-credits procedure stays open: the 2026 credit-memo extract wasn't provided, so the client's claim of none isn't relied on.
Traceable documentationA reviewer can tie every comment to a record.3/3
- Tie lead-sheet comments to recordsPassed
Every comment on the lead sheet sits on an identifiable account row.
- Tie aging comments to recordsPassed
Every comment on the aging tie-out sits on an identifiable customer row.
- Tie confirmation comments to recordsPassed
Every comment on the confirmation tab sits on an identifiable request row.
Quaxinov Staffing Services, a synthetic staffing firm, is closing its December 31, 2025 audit. The agent is assigned the journal entry completeness workpaper: prove the 838-entry population was extracted whole, run integrity checks on it, and roll every general-ledger account forward to the closing trial balance.
The instruction is short because the procedures to perform are well documented within the workpaper template itself. The template lists 11 procedures across 3 tabs. Each tab defines what must be documented and how each figure must be supported. The engagement’s planning context sets materiality and the selection of individual items for detail testing.
Complete `je_completeness_workpaper.xlsx` using `pbc_package/`, `direct_to_auditor/`, and `planning/`. Follow workbook procedures and Planning Context. Save to `/workspace/je_completeness_workpaper.xlsx`.
The procedures live in the blank workpaper, not the prompt. It lists 11 of them across 3 tabs; the agent records each one's execution, evidence, result and signoff.
| Procedure | Assertions | Tab | |
|---|---|---|---|
| 3. | Prove the extraction with control counts — row count, total debits and total credits tied at every hop: source system → raw extract → working file — and confirm total debits equal total credits. | Completeness; Accuracy | <.1> |
| 4. | Run data-integrity checks (unbalanced JEs, blank dates / accounts / amounts, missing user IDs, duplicate JE numbers, out-of-period records, orphan headers) with an expected result of zero; resolve failures and re-extract before relying on the population. | Accuracy; Completeness | <.1> |
| 5. | Test population plausibility — compare the actual entry count to an expected volume (inquiry, prior year, entity size) and investigate implausibly low populations (e.g., a single entry for a full year). | Completeness | <.1> |
| 7. | Roll every GL account forward — opening per the PY audited TB (P&L accounts cleared to retained earnings) plus JE activity per the validated population equals the recalculated ending — and agree to the client's closing TB with a per-account variance. | Completeness; Accuracy | <.2> |
| 11. | The journal-entry population is complete and reliable for testing (extraction controlled, integrity checks passed, rollforward proven), subject to documented open items; risk-based testing is performed on the companion JE Risk Testing workpaper. | Overall | <.0>–<.2> |
| + 6 more procedures | |||
- Overall materiality
- $46,563
- Performance materiality
- $34,922
- Clearly trivial
- $2,328
- Individually significant
- $11,700
- 1Survey the binder
Lists every file in the workspace, reads the client's read-me and dumps each tab of the blank workpaper.
Turns 1–4 · find, openpyxl
Turn 1 · bashcd /workspace && ls -la && echo "---" && find . -type f | head -100
Outputtotal 48 drwxr-xr-x 5 root root 4096 Sep 13 01:36 . drwxr-xr-x 1 root root 4096 Sep 15 06:39 .. drwxr-xr-x 2 root root 4096 Sep 11 17:35 direct_to_auditor -rw-r--r-- 1 root root 26406 Sep 12 23:51 je_completeness_workpaper.xlsx drwxr-xr-x 13 root root 4096 Sep 11 17:35 pbc_package drwxr-xr-x 2 root root 4096 Sep 11 17:35 planning --- ./planning/Materiality Memo.pdf ./planning/Cycle Materiality Allocation Register.pdf ./planning/Financial Audit Planning Inputs.pdf ./planning/Related Party Register.pdf ./planning/Engagement Calendar.pdf ./planning/Audit Selection Plan.pdf … 94 more lines
Turn 2 · bashcd /workspace && find . -type f | wc -l && find . -type f | tail -60 && echo "=== read me first ===" && cat "pbc_package/read me first.txt"
Output153 ./pbc_package/documents/debt/Debt Perfection Evidence Debt reference 001.pdf ./pbc_package/documents/debt/Compliance Certificate 2025.pdf ./pbc_package/documents/debt/Debt Support Schedules 2025.xlsx ./pbc_package/documents/Statement of Cash Flows.xlsx ./pbc_package/documents/Notes to Financial Statements.xlsx ./pbc_package/documents/Depreciation Schedule 2025.xlsx ./pbc_package/documents/Loan History Report.pdf ./pbc_package/documents/invoices/zemvortex quaxley group llc INS-2025-9851.pdf ./pbc_package/documents/invoices/quexford quotmere solutions inc DUE-2025-6116.pdf ./pbc_package/documents/invoices/zenvoque vixler group llc SOF-2025-1442.pdf ./pbc_package/documents/agreements/Quaxinov Staffing - Quizzalex Veltore Holdings Inc Staffing Services-38d484.pdf ./pbc_package/documents/agreements/Vultixor Vorquex Services LLC Staffing Services Agreement - Final.pdf ./pbc_package/documents/agreements/Quaxinov Staffing - Quaxinov Vovstein Holdings Inc Staffing Services-57ad42.pdf … 52 more lines
Turn 3 · bashcd /workspace && python3 -c " import openpyxl wb = openpyxl.load_workbook('je_completeness_workpaper.xlsx', data_only=False) print('Sheets:', wb.sheetnames) for ws in wb.worksheets: print('===', ws.title, ws.dimensions, 'max_row', ws.max_row, 'max_col', ws.max_column) "OutputSheets: ['Library Procedures', '<.0> Source Index', '<.1> Scope & Data Integrity', '<.2> Completeness Rollforward', 'Planning Context'] === Library Procedures A1:Q22 max_row 22 max_col 17 === <.0> Source Index A1:H32 max_row 32 max_col 8 === <.1> Scope & Data Integrity A1:H63 max_row 63 max_col 8 === <.2> Completeness Rollforward A1:K75 max_row 75 max_col 11 === Planning Context A1:B23 max_row 23 max_col 2
Turn 4 · bashcd /workspace && python3 -c " import openpyxl wb = openpyxl.load_workbook('je_completeness_workpaper.xlsx', data_only=False) for ws in wb.worksheets: print('======================', ws.title, '======================') for row in ws.iter_rows(): for c in row: if c.value is not None: print(c.coordinate, repr(c.value)) "Output====================== Library Procedures ====================== A1 'Journal Entries (Completeness & Data Integrity) — Library of Audit Procedures' A2 'Client / Entity: Quaxinov Staffing Services, LLC' A3 'Prepared by: Audit Senior F43D (assigned) Reviewed by: Audit Manager 045E (assigned)' A4 'For every procedure, record applicability, requirement, execution, evidence, result, issue, and signoff states. Performed procedures require a W/P reference, preparer, date, result, and exact Evidence Index citation. Fact-driven N/A requires a FACT:/ JSON-Pointer citation and rationale; missing evidence remains Open. Preserve the assigned PROC: and WINDOW: dependency tokens.' A6 'Applicability' B6 'Requirement' C6 'Execution state' D6 'Evidence state' E6 'Result state' F6 'Issue state' G6 'Signoff state' H6 'Derived outcome' I6 'Procedure' … 457 more lines
- 2Profile the journal entry population
Loads all 1,782 lines (838 entries), runs the integrity checks and sums activity by account against both trial balances.
Turns 5–11 · openpyxl
Turn 5 · bashcd /workspace && python3 -c " import openpyxl for f in ['pbc_package/documents/Complete Journal Entry Population.xlsx']: wb = openpyxl.load_workbook(f, data_only=True) print('FILE', f, wb.sheetnames) for ws in wb.worksheets: print('--- sheet', ws.title, ws.dimensions, ws.max_row, ws.max_column) for i,row in enumerate(ws.iter_rows(values_only=True)): print(i, row) if i>15: break "OutputFILE pbc_package/documents/Complete Journal Entry Population.xlsx ['Complete Journal Entry', 'Population Controls', 'Account Reconciliation', 'Account Component Map', 'User Access Listing'] --- sheet Complete Journal Entry A1:AC1793 1793 29 0 ('Quaxinov Staffing Services, LLC', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) 1 ('Complete Journal Entry Population', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) 2 ('Report parameters: 2025-11-14 through 2025-12-31 (posting date)', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) 3 (None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) 4 ('Entry number', 'Line', 'Line ID', 'Parent line ID', 'Posting date', 'Document number', 'Source', 'Type', 'Post-close', 'Top-side', 'Consolidation/elimination', 'Estimate', 'Ordinary period-end', 'Counterparty', 'Memo', 'Account', 'Debit', 'Credit', 'Posting type', 'Preparer', 'Entered at', 'Approver', 'Approved at', 'Approval basis', 'Posted at', 'Timestamp zone', 'Status', 'Support', 'Reverses entry') 5 ('JE-285291614009', 1, 'JEL-0987AEFEE2B44D8AC5F79D7D-CDB725F34A899BA37', 'JEL-0987AEFEE2B44D8AC5F79D7D', '01/01/2025', None, 'General Journal', 'System', 'No', 'No', 'No', 'No', 'No', None, 'Opening balances carried forward from prior-year close', '1000 Cash - operating', 1027075.44, None, 'Ledger', 'SYSTEM', '2025-01-01T05:19:19', 'Amanda Zarvex', '2025-01-02T09:00:00', 'Automated posting under annual control authorization', '2025-01-01T05:19:19', 'CT (UTC-06:00; UTC-05:00 daylight)', 'posted', 'Prior-year trial balance', None) 6 ('JE-285291614009', 2, 'JEL-B00C17372BF163343399160D-C70ADE6AE0810587B', 'JEL-B00C17372BF163343399160D', '01/01/2025', None, 'General Journal', 'System', 'No', 'No', 'No', 'No', 'No', None, 'Opening balances carried forward from prior-year close', '1010 Accounts receivable - trade', 306327.5, None, 'Ledger', 'SYSTEM', '2025-01-01T05:19:19', 'Amanda Zarvex', '2025-01-02T09:00:00', 'Automated posting under annual control authorization', '2025-01-01T05:19:19', 'CT (UTC-06:00; UTC-05:00 daylight)', 'posted', 'Prior-year trial balance', None) 7 ('JE-285291614009', 3, 'JEL-A7FD3C4B8CCEEC960E80857B-CFB8A64C0FE59D9FA', 'JEL-A7FD3C4B8CCEEC960E80857B', '01/01/2025', None, 'General Journal', 'System', 'No', 'No', 'No', 'No', 'No', None, 'Opening balances carried forward from prior-year close', '1030 Prepaid expenses', 31106.84, None, 'Ledger', 'SYSTEM', '2025-01-01T05:19:19', 'Amanda Zarvex', '2025-01-02T09:00:00', 'Automated posting under annual control authorization', '2025-01-01T05:19:19', 'CT (UTC-06:00; UTC-05:00 daylight)', 'posted', 'Prior-year trial balance', None) 8 ('JE-285291614009', 4, 'JEL-F53BF3911D39EF47B47498BA-C61B465722A0A7C12', 'JEL-F53BF3911D39EF47B47498BA', '01/01/2025', None, 'General Journal', 'System', 'No', 'No', 'No', 'No', 'No', None, 'Opening balances carried forward from prior-year close', '2041 Notes payable', None, 118739.19, 'Ledger', 'SYSTEM', '2025-01-01T05:19:19', 'Amanda Zarvex', '2025-01-02T09:00:00', 'Automated posting under annual control authorization', '2025-01-01T05:19:19', 'CT (UTC-06:00; UTC-05:00 daylight)', 'posted', 'Prior-year trial balance', None) 9 ('JE-285291614009', 5, 'JEL-CF0710438B9CBE34B3551307-C778DF40BC83B4857', 'JEL-CF0710438B9CBE34B3551307', '01/01/2025', None, 'General Journal', 'System', 'No', 'No', 'No', 'No', 'No', None, 'Opening balances carried forward from prior-year close', '1050 Property and equipment', 192080, None, 'Ledger', 'SYSTEM', '2025-01-01T05:19:19', 'Amanda Zarvex', '2025-01-02T09:00:00', 'Automated posting under annual control authorization', '2025-01-01T05:19:19', 'CT (UTC-06:00; UTC-05:00 daylight)', 'posted', 'Prior-year trial balance', None) 10 ('JE-285291614009', 6, 'JEL-10C02DC6F6B59AD6F57560ED-CF855C73DDBEF8681', 'JEL-10C02DC6F6B59AD6F57560ED', '01/01/2025', None, 'General Journal', 'System', 'No', 'No', 'No', 'No', 'No', None, 'Opening balances carried forward from prior-year close', '1051 Accumulated depreciation', None, 84825.09, 'Ledger', 'SYSTEM', '2025-01-01T05:19:19', 'Amanda Zarvex', '2025-01-02T09:00:00', 'Automated posting under annual control authorization', '2025-01-01T05:19:19', 'CT (UTC-06:00; UTC-05:00 daylight)', 'posted', 'Prior-year trial balance', None) 11 ('JE-285291614009', 7, 'JEL-F198A29ECA4E4029F1FCC36F-C04B4013ACC1A5446', 'JEL-F198A29ECA4E4029F1FCC36F', '01/01/2025', None, 'General Journal', 'System', 'No', 'No', 'No', 'No', 'No', None, 'Opening balances carried forward from prior-year close', "3030 Members' equity", None, 1303274.56, 'Ledger', 'SYSTEM', '2025-01-01T05:19:19', 'Amanda Zarvex', '2025-01-02T09:00:00', 'Automated posting under annual control authorization', '2025-01-01T05:19:19', 'CT (UTC-06:00; UTC-05:00 daylight)', 'posted', 'Prior-year trial balance', None) … 64 more linesTurn 6 · bashcd /workspace && python3 -c " import openpyxl wb = openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx', data_only=True) ws = wb['Complete Journal Entry'] rows = list(ws.iter_rows(values_only=True)) hdr = rows[4] print(hdr) # summarize by source, type, posting date from collections import Counter import datetime sources=Counter(); types=Counter(); dates=[]; entrydates={} for r in rows[5:]: if r[0] is None: continue sources[r[6]]+=1 … 17 more linesOutputTraceback (most recent call last): File "<string>", line 19, in <module> TypeError: '<' not supported between instances of 'NoneType' and 'str' ('Entry number', 'Line', 'Line ID', 'Parent line ID', 'Posting date', 'Document number', 'Source', 'Type', 'Post-close', 'Top-side', 'Consolidation/elimination', 'Estimate', 'Ordinary period-end', 'Counterparty', 'Memo', 'Account', 'Debit', 'Credit', 'Posting type', 'Preparer', 'Entered at', 'Approver', 'Approved at', 'Approval basis', 'Posted at', 'Timestamp zone', 'Status', 'Support', 'Reverses entry') sources Counter({'General Journal': 780, 'Sales Journal': 626, 'Payroll': 262, 'Fixed Assets': 102, 'Accounts Payable': 6, 'Cash Disbursements': 6, None: 5}) types Counter({'System': 1656, 'Manual': 126, None: 5})Turn 7 · bashcd /workspace && python3 -c " import openpyxl wb = openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx', data_only=True) ws = wb['Complete Journal Entry'] rows = list(ws.iter_rows(values_only=True)) for i,r in enumerate(rows): if r[0] is None: print('BLANKROW', i, r) print('total rows', len(rows)) print('last rows:') for r in rows[-6:]: print(r) "OutputBLANKROW 3 (None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) BLANKROW 1787 (None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) total rows 1793 last rows: (None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('Entry count', 838, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('Line count', 1782, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('Total debits', 10713435.26, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('Total credits', 10713435.26, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('Canonical population contract', 'canonical-populations-v2', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None)Turn 8 · bashcd /workspace && python3 << 'EOF' import openpyxl wb = openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx', data_only=True) ws = wb['Complete Journal Entry'] rows = list(ws.iter_rows(values_only=True)) data = [r for r in rows[5:1787] if r[0] is not None] print('data line rows', len(data)) from collections import Counter # integrity checks unbalanced = Counter(); blankdate=[]; blankacct=[]; missinguser=[]; dupje=[]; outperiod=[]; blankamt=[]; orphan=[] import datetime def parse(d): if d is None: return None if isinstance(d, datetime.datetime): return d … 56 more linesOutputdata line rows 1782 entries 838 unbalanced entries 0 [] blank dates 0 set() blank acct 0 missing preparer 0 out of 2025 period 0 set() blank amounts 0 date min 2025-01-01 00:00:00 max 2025-12-31 00:00:00 entries by month first date [('2025-01', 72), ('2025-02', 37), ('2025-03', 75), ('2025-04', 62), ('2025-05', 59), ('2025-06', 68), ('2025-07', 71), ('2025-08', 75), ('2025-09', 75), ('2025-10', 71), ('2025-11', 68), ('2025-12', 105)] lines by month [('2025-01', 156), ('2025-02', 80), ('2025-03', 156), ('2025-04', 132), ('2025-05', 128), ('2025-06', 144), ('2025-07', 146), ('2025-08', 158), ('2025-09', 160), ('2025-10', 152), ('2025-11', 144), ('2025-12', 226)]Turn 9 · bashcd /workspace && python3 << 'EOF' import openpyxl wb = openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx', data_only=True) for sh in ['Account Reconciliation']: ws=wb[sh] rows=list(ws.iter_rows(values_only=True)) print('===',sh) for r in rows: print(r) EOFOutput=== Account Reconciliation ('Account', 'Account name', 'Class', 'Canonical source account', 'In COA', 'In PY TB', 'In opening', 'In CY TB', 'In JE', 'PY closing', 'P&L closing', 'Retained earnings pickup', 'Calculated opening', 'Opening', 'Opening difference', 'JE debit', 'JE credit', 'JE net', 'TB debit', 'TB credit', 'Debit difference', 'Credit difference', 'Calculated ending', 'CY ending', 'Ending difference', 'Gross activity', 'Nil account', 'Zero-net with gross activity', 'Coverage status', 'Issue codes') ('1000', 'Cash - operating', 'Asset', 'Source account CASH 001', 'Yes', 'Yes', 'Yes', 'Yes', 'Yes', 1027075.44, 0, 0, 1027075.44, 1027075.44, 0, 3256825, 2394152.75, 862672.25, 3256825, 2394152.75, 0, 0, 1889747.69, 1889747.69, 0, 5650977.75, 'No', 'No', 'Complete', 'none') ('1010', 'Accounts receivable - trade', 'Asset', 'Source account AR 001', 'Yes', 'Yes', 'Yes', 'Yes', 'Yes', 306327.5, 0, 0, 306327.5, 306327.5, 0, 3118880, 3271482.5, -152602.5, 3118880, 3271482.5, 0, 0, 153725, 153725, 0, 6390362.5, 'No', 'No', 'Complete', 'none') ('1011', 'Allowance for credit losses', 'Contra Asset', 'Source account ALLOWANCE 001', 'Yes', 'Yes', 'Yes', 'Yes', 'Yes', -49750.94, 0, 0, -49750.94, -49750.94, 0, 24784.32, 0, 24784.32, 24784.32, 0, 0, 0, -24966.62, -24966.62, 0, 24784.32, 'No', 'No', 'Complete', 'none') ('1030', 'Prepaid expenses', 'Asset', 'Source account PREPAID 001', 'Yes', 'Yes', 'Yes', 'Yes', 'Yes', 31106.84, 0, 0, 31106.84, 31106.84, 0, 39000, 58509.58, -19509.58, 39000, 58509.58, 0, 0, 11597.26, 11597.26, 0, 97509.58, 'No', 'No', 'Complete', 'none') ('1050', 'Property and equipment', 'Asset', 'Source account FIXED ASSET 001', 'Yes', 'Yes', 'Yes', 'Yes', 'Yes', 192080, 0, 0, 192080, 192080, 0, 0, 0, 0, 0, 0, 0, 0, 192080, 192080, 0, 0, 'No', 'No', 'Complete', 'none') ('1051', 'Accumulated depreciation', 'Contra Asset', 'Source account ACCUM DEPR 001', 'Yes', 'Yes', 'Yes', 'Yes', 'Yes', -84825.09, 0, 0, -84825.09, -84825.09, 0, 0, 34954.93, -34954.93, 0, 34954.93, 0, 0, -119780.02, -119780.02, 0, 34954.93, 'No', 'No', 'Complete', 'none') ('2000', 'Accounts payable', 'Liability', 'Source account AP 001', 'Yes', 'Yes', 'Yes', 'Yes', 'Yes', 0, 0, 0, 0, 0, 0, 39000, 39000, 0, 39000, 39000, 0, 0, 0, 0, 0, 78000, 'No', 'Yes', 'Complete', 'none') ('2021', 'Accrued payroll', 'Liability', 'Source account WH PAYABLE 001', 'Yes', 'Yes', 'Yes', 'Yes', 'Yes', 0, 0, 0, 0, 0, 0, 0, 29906.36, -29906.36, 0, 29906.36, 0, 0, -29906.36, -29906.36, 0, 29906.36, 'No', 'No', 'Complete', 'none') ('2025', 'Payroll withholdings payable', 'Liability', 'Source account WH PAYABLE 001', 'Yes', 'Yes', 'Yes', 'Yes', 'Yes', 0, 0, 0, 0, 0, 0, 185175.04, 185175.04, 0, 185175.04, 185175.04, 0, 0, 0, 0, 0, 370350.08, 'No', 'Yes', 'Complete', 'none') ('2041', 'Notes payable', 'Liability', 'Source account DEBT 001', 'Yes', 'Yes', 'Yes', 'Yes', 'Yes', -118739.19, 0, 0, -118739.19, -118739.19, 0, 3781.4, 0, 3781.4, 3781.4, 0, 0, 0, -114957.79, -114957.79, 0, 3781.4, 'No', 'No', 'Complete', 'none') ('3030', "Members' equity", 'Equity', 'Source account CAPITAL 001', 'Yes', 'Yes', 'Yes', 'Yes', 'Yes', -770074.9, 0, -533199.66, -1303274.56, -1303274.56, 0, 0, 0, 0, 0, 0, 0, 0, -1303274.56, -1303274.56, 0, 0, 'No', 'No', 'Complete', 'none') ('4000', 'Other income', 'Revenue', 'Source account REVENUE 001', 'Yes', 'Yes', 'Yes', 'Yes', 'No', 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 'Yes', 'No', 'Complete', 'none') … 9 more linesTurn 10 · bashcd /workspace && python3 << 'EOF' import openpyxl for f in ['pbc_package/foundational/TB 12 31 25.xlsx','pbc_package/foundational/TB 12 31 24.xlsx','pbc_package/foundational/Chart of Accounts.xlsx']: wb=openpyxl.load_workbook(f,data_only=True) print('##########',f, wb.sheetnames) for ws in wb.worksheets: print('=== sheet',ws.title,ws.dimensions) rows=list(ws.iter_rows(values_only=True)) for r in rows: print(r) print() EOFOutput########## pbc_package/foundational/TB 12 31 25.xlsx ['TB 12 31 25'] === sheet TB 12 31 25 A1:D31 ('Quaxinov Staffing Services, LLC', None, None, None) ('TB 12 31 25', None, None, None) ('As of December 31, 2025', None, None, None) (None, None, None, None) ('Account', 'Name', 'Debit', 'Credit') ('1000', 'Cash - operating', 1889747.69, 0) ('1010', 'Accounts receivable - trade', 153725, 0) ('1011', 'Allowance for credit losses', 0, 24966.62) ('1030', 'Prepaid expenses', 11597.26, 0) ('1050', 'Property and equipment', 192080, 0) ('1051', 'Accumulated depreciation', 0, 119780.02) ('2000', 'Accounts payable', 0, 0) … 87 more linesTurn 11 · bashcd /workspace && python3 << 'EOF' import openpyxl from collections import defaultdict wb = openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx', data_only=True) ws = wb['Complete Journal Entry'] rows = list(ws.iter_rows(values_only=True)) data = [r for r in rows[5:1787] if r[0] is not None] sets = defaultdict(lambda: [0,0]) for r in data: acct=r[15]; d=r[16] or 0; c=r[17] or 0 sets[acct][0]+=d; sets[acct][1]+=c print('account, debit, credit, net') tot=[0,0] for a in sorted(sets): … 14 more linesOutputaccount, debit, credit, net 1000 Cash - operating 4283900.44 2394152.75 1889747.69 1010 Accounts receivable - trade 3425207.5 3271482.5 153725.0 1011 Allowance for credit losses 24784.32 49750.94 -24966.62 1030 Prepaid expenses 70106.84 58509.58 11597.26 1050 Property and equipment 192080 0 192080 1051 Accumulated depreciation 0 119780.02 -119780.02 2000 Accounts payable 39000 39000 0 2021 Accrued payroll 0 29906.36 -29906.36 2025 Payroll withholdings payable 185175.04 185175.04 -0.0 2041 Notes payable 3781.4 118739.19 -114957.79 3030 Members' equity 0 1303274.56 -1303274.56 4010 Service revenue 14657.5 3118880.0 -3104222.5 6005 Cost of goods sold 2117564.59 0 2117564.59 … 27 more lines
- 3Read the planning file
Converts the planning PDFs to text and reads materiality, the sampling method, the selection plan and the fraud-risk register.
10 turns · pdftotext, rg
Turn 12 · bashcd /workspace && mkdir -p /tmp/txt && for f in planning/*.pdf; do b=$(basename "$f" .pdf); pdftotext -layout "$f" "/tmp/txt/$b.txt" 2>/dev/null; done && ls -la /tmp/txt && echo "=== Audit Planning Packet Index ===" && cat "/tmp/txt/Audit Planning Packet Index.txt"
Outputtotal 180 drwxr-xr-x 2 root root 4096 Sep 15 06:40 . drwxrwxrwt 1 root root 4096 Sep 15 06:40 .. -rw-r--r-- 1 root root 7614 Sep 15 06:40 Accounting Policy Register.txt -rw-r--r-- 1 root root 8917 Sep 15 06:40 Assertion-Level Risk Assessment.txt -rw-r--r-- 1 root root 3636 Sep 15 06:40 Audit Planning Packet Index.txt -rw-r--r-- 1 root root 14908 Sep 15 06:40 Audit Selection Plan.txt -rw-r--r-- 1 root root 13405 Sep 15 06:40 Controls and IT-IPE Strategy.txt -rw-r--r-- 1 root root 2078 Sep 15 06:40 Cycle Materiality Allocation Register.txt -rw-r--r-- 1 root root 3299 Sep 15 06:40 Engagement Calendar.txt -rw-r--r-- 1 root root 1145 Sep 15 06:40 Engagement Scope and Case Facts.txt -rw-r--r-- 1 root root 3025 Sep 15 06:40 FSLI Scope Matrix.txt -rw-r--r-- 1 root root 19764 Sep 15 06:40 Financial Audit Planning Inputs.txt -rw-r--r-- 1 root root 1688 Sep 15 06:40 Materiality Memo.txt … 59 more lines
Turn 13 · bashcd /workspace && echo "=== Materiality Memo ===" && cat "/tmp/txt/Materiality Memo.txt" && echo "=== Cycle Materiality Allocation ===" && cat "/tmp/txt/Cycle Materiality Allocation Register.txt" && echo "=== Engagement Scope and Case Facts ===" && cat "/tmp/txt/Engagement Scope and Case Facts.txt"
Output=== Materiality Memo === Quaxinov Staffing Services, LLC WORKPAPER REF. PL-MM AUDIT PLANNING PREPARED BY: DATE: MATERIALITY MEMO REVIEWED BY: DATE: POLICY VERSION materiality-v2 SCENARIO Standard … 114 more lines
Turn 14 · bashcd /workspace && echo "=== Sampling Methodology ===" && cat "/tmp/txt/Sampling Methodology.txt" && echo "=== Procedure Window Register ===" && cat "/tmp/txt/Procedure Window Register.txt"
Output=== Sampling Methodology === Quaxinov Staffing Services, LLC WORKPAPER REF. PL-SM AUDIT PLANNING PREPARED BY: DATE: SAMPLING METHODOLOGY REVIEWED BY: DATE: METHOD Statistical SAMPLING RISK 5 percent risk of incorrect acceptance … 139 more lines
Turn 15 · bashcd /workspace && cat "/tmp/txt/Audit Selection Plan.txt"
OutputQuaxinov Staffing Services, LLC WORKPAPER REF. PL-ASP AUDIT PLANNING PREPARED BY: DATE: AUDIT SELECTION PLAN REVIEWED BY: DATE: Population analyzed is the number of records subjected to reconciliation or data analysis. It is not the number receiving detailed inspection. Detailed tests equal targeted items plus the residual sample. PROCEDURE SAMPLING UNIT POPULATION ANALYZED TARGETED RESIDUAL DETAIL REVIEW STATUS … 213 more lines
Turn 16 · bashcd /workspace && cat "/tmp/txt/Planned Procedure Register.txt"
OutputQuaxinov Staffing Services, LLC WORKPAPER REF. PL-PPR AUDIT PLANNING PREPARED BY: DATE: PLANNED PROCEDURE REGISTER REVIEWED BY: DATE: POLICY risk-nte-v1 AUDIT STRATEGY Controls Reliance … 142 more lines
Turn 17 · bashcd /workspace && rg -n "PROC-Journal|OVERRIDE|WIN-Journal|SAMPLE-Journal" /tmp/txt/ | head -40
Output/tmp/txt/Significant and Fraud Risk Register.txt:10: MANAGEMENT OVERRIDE OF CONTROLS /tmp/txt/FSLI Scope Matrix.txt:10: WORKPAPER FAMILY AMOUNT QUANTITATIVE QUALITATIVE RISK OVERRIDE SCOPE BASIS
Turn 18 · bashcd /workspace && cat "/tmp/txt/Significant and Fraud Risk Register.txt" && echo "=====FSLI=====" && cat "/tmp/txt/FSLI Scope Matrix.txt" && echo "=====Significance=====" && cat "/tmp/txt/Significance Matrix.txt"
OutputQuaxinov Staffing Services, LLC WORKPAPER REF. PL-SAFR AUDIT PLANNING PREPARED BY: DATE: SIGNIFICANT AND FRAUD RISK REGISTER REVIEWED BY: DATE: MANAGEMENT OVERRIDE OF CONTROLS CLASSIFICATION Fraud ASSERTIONS occurrence, classification, completeness … 300 more lines
Turn 23 · bashcd /workspace && cat "/tmp/txt/Financial Audit Planning Inputs.txt"
OutputQuaxinov Staffing Services, LLC WORKPAPER REF. PL-FAPI AUDIT PLANNING PREPARED BY: DATE: FINANCIAL AUDIT PLANNING INPUTS REVIEWED BY: DATE: FISCAL YEAR END 12/31/2025 BUSINESS PROFILE Staffing Services … 608 more lines
Turn 35 · bashcd /workspace && cat "/tmp/txt/Controls and IT-IPE Strategy.txt"
OutputQuaxinov Staffing Services, LLC WORKPAPER REF. PL-CAII AUDIT PLANNING PREPARED BY: DATE: CONTROLS AND IT-IPE STRATEGY REVIEWED BY: DATE: AUDIT STRATEGY Controls Reliance CONTROLS TESTED FOR RELIANCE 11 IPE REPORTS ASSESSED 83 … 204 more lines
Turn 36 · bashcd /workspace && echo "=== Assertion-Level Risk ===" && cat "/tmp/txt/Assertion-Level Risk Assessment.txt" && echo "=== Accounting Policy ===" && cat "/tmp/txt/Accounting Policy Register.txt" | head -80 && echo "=== Engagement Calendar ===" && cat "/tmp/txt/Engagement Calendar.txt" && echo "=== Related Party ===" && cat "/tmp/txt/Related Party Register.txt" && echo "=== Unadjusted ===" && cat "/tmp/txt/Unadjusted Differences Register.txt"
Output=== Assertion-Level Risk === Quaxinov Staffing Services, LLC WORKPAPER REF. PL-ALRA AUDIT PLANNING PREPARED BY: DATE: ASSERTION-LEVEL RISK ASSESSMENT REVIEWED BY: DATE: CYCLE ASSERTION INHERENT RISK CONTROL RISK ROMM CONTROLS PLANNED RESPONSE RELIANCE Cash Existence Moderate Low Moderate Yes Substantive analytics and risk-calibrated detail testing … 315 more lines - 4Look for extraction evidence
Searches the binder for an extraction log or close checklist, and reads the package index and the prior-year volume report.
8 turns · rg, pdftotext, openpyxl
Turn 19 · bashcd /workspace && grep -rl "Derived outcome\|Signoff state\|Execution state\|FACT:" --include=*.xlsx . 2>/dev/null; echo "---search xlsx text---"; for f in $(find . -name '*.xlsx'); do if python3 -c " import sys,openpyxl try: wb=openpyxl.load_workbook('$f',data_only=True,read_only=True) except Exception as e: sys.exit(1) for ws in wb.worksheets: for row in ws.iter_rows(values_only=True): for c in row: if isinstance(c,str) and ('Derived outcome' in c or 'FACT:' in c or 'Evidence Index' in c or 'Signoff state' in c): print('$f', c[:60]); sys.exit(0) " 2>/dev/null; then :; fi; doneOutput---search xlsx text--- ./je_completeness_workpaper.xlsx For every procedure, record applicability, requirement, exec
Turn 20 · bashcd /workspace && python3 << 'EOF' import openpyxl for f in ['pbc_package/Package Index.xlsx','direct_to_auditor/AR Auditor Evidence Control.xlsx']: wb=openpyxl.load_workbook(f,data_only=True) print('##########',f,wb.sheetnames) for ws in wb.worksheets: print('=== sheet',ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): print(r) print() EOFOutput########## pbc_package/Package Index.xlsx ['Final Package Index'] === sheet Final Package Index A1:G134 ('Final File', 'Evidence Category', 'Purpose / Evidence Family', 'Version Status', 'Preparer', 'Reviewer', 'Package Date') ('direct_to_auditor/AR Auditor Evidence Control.xlsx', 'Package Control', 'AR Auditor Evidence Control', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/AR Confirmation - Veltoxin Quixley Group LLC.pdf', 'Package Control', 'AR Confirmation - Veltoxin Quixley Group LLC', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/AR Confirmation - Vexmultix Quotane Holdings Inc.pdf', 'Package Control', 'AR Confirmation - Vexmultix Quotane Holdings Inc', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/AR Confirmation - Vultixor Vorquex Services LLC.pdf', 'Package Control', 'AR Confirmation - Vultixor Vorquex Services LLC', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/Bank Confirmation 12.31.2025.pdf', 'Package Control', 'Bank Confirmation 12.31.2025', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('direct_to_auditor/Loan Confirmation 2025.pdf', 'Package Control', 'Loan Confirmation 2025', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/accounts_receivable/AR Aging 12 31 25.xlsx', 'Package Control', 'AR Aging 12 31 25', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/accounts_receivable/Allowance for Credit Losses 12 31 25.xlsx', 'Package Control', 'Allowance for Credit Losses 12 31 25', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/accounts_receivable/Cash Receipts Jan 2026.xlsx', 'Package Control', 'Cash Receipts Jan 2026', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/ap_and_accruals/AP Aging (2025-12-31).xlsx', 'Package Control', 'AP Aging (2025-12-31)', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/ap_and_accruals/Payments - January 2026.xlsx', 'Package Control', 'Payments - January 2026', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) … 74 more linesTurn 21 · bashcd /workspace && python3 << 'EOF' import openpyxl wb=openpyxl.load_workbook('pbc_package/Package Index.xlsx',data_only=True) ws=wb['Final Package Index'] rows=list(ws.iter_rows(values_only=True)) print('total rows',len(rows)) for r in rows[100:]: print(r) EOFOutputtotal rows 134 ('pbc_package/documents/invoices/zenvoque vixler group llc SOF-2025-1442.pdf', 'Package Control', 'zenvoque vixler group llc SOF-2025-1442', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/documents/journal_entries/Journal Volume Summary 2024.pdf', 'Package Control', 'Journal Volume Summary 2024', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/documents/payroll/Approved Assignment Time and Billing Reconciliation.xlsx', 'Package Control', 'Approved Assignment Time and Billing Reconciliation', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/documents/payroll/Employer Payroll Tax Rate Notice 2025.pdf', 'Package Control', 'Employer Payroll Tax Rate Notice 2025', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/documents/payroll/HR Authorization Register 2025.pdf', 'Package Control', 'HR Authorization Register 2025', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/documents/payroll/Payroll Accrual Reconciliation 2025.pdf', 'Package Control', 'Payroll Accrual Reconciliation 2025', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/documents/payroll/Payroll Allocation and Classification 2025.xlsx', 'Package Control', 'Payroll Allocation and Classification 2025', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/documents/payroll/Payroll Control Matrix 2025.pdf', 'Package Control', 'Payroll Control Matrix 2025', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/documents/payroll/Payroll Payment Detail 2025.xlsx', 'Package Control', 'Payroll Payment Detail 2025', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/documents/payroll/Payroll Register IPE Control 2025.xlsx', 'Package Control', 'Payroll Register IPE Control 2025', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/documents/payroll/Payroll Settlement Report 2025.pdf', 'Package Control', 'Payroll Settlement Report 2025', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/documents/payroll/Subsequent Payroll Report 2026.pdf', 'Package Control', 'Subsequent Payroll Report 2026', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) ('pbc_package/equity/Equity Schedule.xlsx', 'Package Control', 'Equity Schedule', 'Final - authoritative', 'Edward Vixmore', 'Amanda Zarvex', datetime.datetime(2025, 12, 31, 0, 0)) … 21 more linesTurn 22 · bashcd /workspace && pdftotext -layout "pbc_package/documents/journal_entries/Journal Volume Summary 2024.pdf" /tmp/txt/jv2024.txt && cat /tmp/txt/jv2024.txt
OutputPRIOR-YEAR JOURNAL VOLUME CONTROL REPORT Quaxinov Staffing Services, LLC Report period January 1 through December 31, 2024 Report level Posted journal-entry headers Parameters All ledgers; all sources; posted and post-close batches Month Journal entry count January 32 February 29 March 28 April 30 May 29 June 33 … 15 more linesTurn 28 · bashcd /workspace && find . -iname '*close*' -o -iname '*checklist*' | head; echo "---"; ls pbc_package; echo "--- all files count by dir ---"; find pbc_package -maxdepth 2 -type d | sort; echo "--- search text for close checklist / extraction log ---"; rg -il "close checklist|extraction log|report parameter" . 2>/dev/null | head
Output--- Package Index.xlsx accounts_receivable ap_and_accruals cash debt documents equity fixed_assets foundational payroll prepaids read me first.txt revenue … 23 more lines
Turn 29 · bashcd /workspace && python3 << 'EOF' import openpyxl wb=openpyxl.load_workbook('direct_to_auditor/AR Auditor Evidence Control.xlsx',data_only=True) for ws in wb.worksheets: print('=== sheet',ws.title,ws.dimensions) for r in ws.iter_rows(values_only=True): print(r) EOFOutput=== sheet Confirmation Control A1:Z8 ('Quaxinov Staffing Services, LLC', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('Auditor-Controlled Accounts Receivable Evidence', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('As of 2025-12-31', None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) (None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None, None) ('Confirmation control id', 'Subject id', 'Subject name', 'Balance date', 'Book balance', 'Selection basis', 'Validated destination', 'Address validation source', 'Address validation date', 'Address validation result', 'Authorized date', 'Sent date', 'Send method', 'Send log reference', 'Follow up date', 'Response date', 'Received date', 'Response medium', 'Direct receipt', 'Response reference', 'Response result', 'Response amount', 'Difference amount', 'Exception resolution', 'Electronic authenticity applicability', 'Electronic authenticity result') ('Confirmation reference 7926440D4E', 'Vexmultix Quotane Holdings, Inc.', 'Vexmultix Quotane Holdings, Inc.', datetime.datetime(2025, 12, 31, 0, 0), 13370, 'largest positive non-government customer balances', 'Accounts Receivable Department, Vexmultix Quotane Holdings, Inc.', 'independent customer website plus switchboard callback', datetime.datetime(2026, 1, 7, 0, 0), 'matched', datetime.datetime(2026, 1, 7, 0, 0), datetime.datetime(2026, 1, 8, 0, 0), 'auditor-controlled email', 'Confirmation reference Send 001', datetime.datetime(2026, 1, 19, 0, 0), datetime.datetime(2026, 1, 26, 0, 0), datetime.datetime(2026, 1, 27, 0, 0), 'Paper mail', True, 'Confirmation reference Reply 001', 'agree', 13370, 0, 'Not required', 'Not applicable proven paper', 'not applicable - proven paper reply; independent AVT completed') ('Confirmation reference 68733D78C7', 'Vultixor Vorquex Services, LLC', 'Vultixor Vorquex Services, LLC', datetime.datetime(2025, 12, 31, 0, 0), 13277.5, 'largest positive non-government customer balances', 'Accounts Receivable Department, Vultixor Vorquex Services, LLC', 'independent customer website plus switchboard callback', datetime.datetime(2026, 1, 5, 0, 0), 'matched', datetime.datetime(2026, 1, 5, 0, 0), datetime.datetime(2026, 1, 6, 0, 0), 'auditor-controlled email', 'Confirmation reference Send 002', datetime.datetime(2026, 1, 16, 0, 0), datetime.datetime(2026, 1, 22, 0, 0), datetime.datetime(2026, 1, 23, 0, 0), 'Paper fax', True, 'Confirmation reference Reply 002', 'agree', 13277.5, 0, 'Not required', 'Not applicable proven paper', 'not applicable - proven paper reply; independent AVT completed') ('Confirmation reference F731Fee9Ee', 'Veltoxin Quixley Group, LLC', 'Veltoxin Quixley Group, LLC', datetime.datetime(2025, 12, 31, 0, 0), 12660, 'largest positive non-government customer balances', 'Accounts Receivable Department, Veltoxin Quixley Group, LLC', 'independent customer website plus switchboard callback', datetime.datetime(2026, 1, 5, 0, 0), 'matched', datetime.datetime(2026, 1, 5, 0, 0), datetime.datetime(2026, 1, 6, 0, 0), 'auditor-controlled email', 'Confirmation reference Send 003', datetime.datetime(2026, 1, 16, 0, 0), datetime.datetime(2026, 1, 26, 0, 0), datetime.datetime(2026, 1, 26, 0, 0), 'Email attachment', True, 'Confirmation reference Reply 003', 'agree', 12660, 0, 'Not required', 'applicable', 'passed') === sheet Coverage Summary A1:D10 ('Quaxinov Staffing Services, LLC', None, None, None) ('Mutually Exclusive Evidence Coverage', None, None, None) (None, None, None, None) ('Evidence Bucket', 'Invoice Count', 'Amount', 'Percent of Gross AR') … 69 more linesTurn 33 · bashcd /workspace && for f in $(find . -name '*.xlsx'); do python3 - "$f" << 'EOF' 2>/dev/null import sys,openpyxl f=sys.argv[1] try: wb=openpyxl.load_workbook(f,data_only=True,read_only=True) except Exception: sys.exit(0) for ws in wb.worksheets: for row in ws.iter_rows(values_only=True): for c in row: if isinstance(c,str) and any(k in c for k in ['Valid N/A','Fact Driven','Recommended - Not Performed','Sufficient','Performed','Blocked','Unable to Conclude']): print(f,'|',ws.title,'|',c[:80]); sys.exit(0) EOF doneOutput./je_completeness_workpaper.xlsx | Library Procedures | For every procedure, record applicability, requirement, execution, evidence, res
Turn 34 · bashcd /workspace && find pbc_package direct_to_auditor planning -type f | sort
Outputdirect_to_auditor/AR Auditor Evidence Control.xlsx direct_to_auditor/AR Confirmation - Veltoxin Quixley Group LLC.pdf direct_to_auditor/AR Confirmation - Vexmultix Quotane Holdings Inc.pdf direct_to_auditor/AR Confirmation - Vultixor Vorquex Services LLC.pdf direct_to_auditor/Bank Confirmation 12.31.2025.pdf direct_to_auditor/Loan Confirmation 2025.pdf pbc_package/Package Index.xlsx pbc_package/accounts_receivable/AR Aging 12 31 25.xlsx pbc_package/accounts_receivable/Allowance for Credit Losses 12 31 25.xlsx pbc_package/accounts_receivable/Cash Receipts Jan 2026.xlsx pbc_package/ap_and_accruals/AP Aging (2025-12-31).xlsx pbc_package/ap_and_accruals/Payments - January 2026.xlsx pbc_package/ap_and_accruals/Purchase Detail Dec 2025.xlsx pbc_package/ap_and_accruals/Vendor Invoice Support 2025.xlsx … 138 more lines
- 5Split automated from manual entries
Profiles entries by source and type: 376 system-generated, 424 interface postings and 38 manual.
6 turns · openpyxl
Turn 24 · bashcd /workspace && python3 << 'EOF' import openpyxl from collections import Counter, defaultdict import datetime wb = openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx', data_only=True) ws = wb['Complete Journal Entry'] rows = list(ws.iter_rows(values_only=True)) hdr=rows[4] data=[r for r in rows[5:1787] if r[0] is not None] idx={h:i for i,h in enumerate(hdr)} def col(name): return idx[name] # entry-level flags entries=defaultdict(list) for r in data: entries[r[0]].append(r) … 39 more linesOutputentries 838 Post-close Counter({('No',): 838}) Top-side Counter({('No',): 838}) Consolidation/elimination Counter({('No',): 838}) Estimate Counter({('No',): 778, ('Yes',): 60}) Ordinary period-end Counter({('No',): 803, ('Yes',): 35}) Type per line Counter({'System': 1656, 'Manual': 126}) Type per entry Counter({('System',): 800, ('Manual',): 38}) Source per entry 0 Source sets per entry Counter({('General Journal',): 382, ('Sales Journal',): 313, ('Payroll',): 106, ('Fixed Assets',): 31, ('Accounts Payable',): 3, ('Cash Disbursements',): 3}) manual entries 38 line id dup 0 Status Counter({'posted': 1782}) Posting type Counter({'Ledger': 1341, 'Bank': 441}) … 8 more linesTurn 25 · bashcd /workspace && python3 << 'EOF' import openpyxl from collections import Counter, defaultdict wb = openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx', data_only=True) ws = wb['Complete Journal Entry'] rows = list(ws.iter_rows(values_only=True)) hdr=rows[4]; data=[r for r in rows[5:1787] if r[0] is not None] idx={h:i for i,h in enumerate(hdr)} def c(n): return idx[n] entries=defaultdict(list) for r in data: entries[r[0]].append(r) # manual entries detail man=[e for e,ls in entries.items() if ls[0][c('Type')]=='Manual'] print('manual entries:', len(man)) … 10 more linesOutputmanual entries: 38 manual by source Counter({'Fixed Assets': 31, 'General Journal': 6, 'Payroll': 1}) manual Estimate Counter({'Yes': 32, 'No': 6}) manual OrdinaryPE Counter({'No': 29, 'Yes': 9}) manual posting type Counter({'Ledger': 38}) JE-870169251838 01/31/2025 Fixed Assets Est Yes OPE No amt 2208.21 | Prepaid amortization per amortization schedule JE-672725699444 01/31/2025 Fixed Assets Est Yes OPE No amt 1019.18 | Prepaid amortization per amortization schedule JE-003836721823 02/28/2025 Fixed Assets Est Yes OPE No amt 1994.53 | Prepaid amortization per amortization schedule JE-153450899571 02/28/2025 Fixed Assets Est Yes OPE No amt 920.54 | Prepaid amortization per amortization schedule JE-931765189677 03/31/2025 Fixed Assets Est Yes OPE No amt 3482.18 | Prepaid amortization per amortization schedule JE-449143658870 03/31/2025 Fixed Assets Est Yes OPE No amt 1698.63 | Prepaid amortization per amortization schedule JE-936447559033 04/30/2025 Fixed Assets Est Yes OPE No amt 3369.87 | Prepaid amortization per amortization schedule JE-996705978641 04/30/2025 Fixed Assets Est Yes OPE No amt 1643.83 | Prepaid amortization per amortization schedule JE-625295569030 05/31/2025 Fixed Assets Est Yes OPE No amt 3482.19 | Prepaid amortization per amortization schedule … 29 more linesTurn 26 · bashcd /workspace && python3 << 'EOF' import openpyxl from collections import Counter, defaultdict wb = openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx', data_only=True) ws = wb['Complete Journal Entry'] rows = list(ws.iter_rows(values_only=True)) hdr=rows[4]; data=[r for r in rows[5:1787] if r[0] is not None] idx={h:i for i,h in enumerate(hdr)} def c(n): return idx[n] entries=defaultdict(list) for r in data: entries[r[0]].append(r) # posting type by source (line level) pt=defaultdict(Counter) for r in data: pt[r[c('Source')]][r[c('Posting type')]]+=1 … 19 more linesOutputGeneral Journal {'Ledger': 420, 'Bank': 360} Payroll {'Ledger': 184, 'Bank': 78} Fixed Assets {'Ledger': 102} Sales Journal {'Ledger': 626} Accounts Payable {'Ledger': 6} Cash Disbursements {'Bank': 3, 'Ledger': 3} posting type per entry Counter({('Bank', 'Ledger'): 441, ('Ledger',): 397}) source by type (entry) General Journal {'System': 376, 'Manual': 6} Payroll {'System': 105, 'Manual': 1} Fixed Assets {'Manual': 31} Sales Journal {'System': 313} Accounts Payable {'System': 3} … 5 more linesTurn 27 · bashcd /workspace && python3 << 'EOF' import openpyxl from collections import Counter, defaultdict wb = openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx', data_only=True) ws = wb['Complete Journal Entry'] rows = list(ws.iter_rows(values_only=True)) hdr=rows[4]; data=[r for r in rows[5:1787] if r[0] is not None] idx={h:i for i,h in enumerate(hdr)} def c(n): return idx[n] entries=defaultdict(list) for r in data: entries[r[0]].append(r) # GJ system memos gjsys=Counter() for e,ls in entries.items(): … 21 more linesOutput24 | Bank activity batch posting 20 | Deposit - Quizmere Quovane Group, LLC 19 | Deposit - Vultixor Vorquex Services, LLC 18 | Deposit - Veltoxin Quixley Group, LLC 18 | Deposit - Zimvault Zaxvole Holdings, Inc. 17 | Deposit - Vexmultix Quotane Holdings, Inc. 17 | Deposit - Zenvoque Vixmore Group, LLC 16 | Deposit - Quilmaven Zixford Solutions, Inc. 15 | Deposit - Voxintel Quaxvote Solutions, Inc. 14 | Deposit - Volvexian Quizlame Services, LLC 14 | Deposit - Quizzalex Veltore Holdings, Inc. 14 | Deposit - Vaxilume Voxford Holdings, Inc. 14 | Deposit - Valtronix Zixwater Holdings, Inc. 13 | Deposit - Zixmantel Voraxle Services, LLC … 22 more lines
Turn 40 · bashcd /workspace && python3 << 'EOF' import openpyxl wb = openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx', data_only=True) for sh in ['Account Component Map','Population Controls']: ws=wb[sh] print('===',sh) for r in ws.iter_rows(values_only=True): print(r) EOFOutput=== Account Component Map ('Canonical source account', 'Canonical account name', 'Projected component account', 'Projected account name', 'Mapping type', 'Component role', 'Mapping basis', 'Mapping status') ('Source account ACCUM DEPR 001', 'Accumulated depreciation', '1051', 'Accumulated depreciation', 'One To One', 'Primary', 'Projection Component Bridge', 'Mapped') ('Source account ALLOWANCE 001', 'Allowance for credit losses', '1011', 'Allowance for credit losses', 'One To One', 'Primary', 'Projection Component Bridge', 'Mapped') ('Source account AP 001', 'Accounts payable', '2000', 'Accounts payable', 'One To One', 'Primary', 'Projection Component Bridge', 'Mapped') ('Source account AR 001', 'Accounts receivable', '1010', 'Accounts receivable - trade', 'One To One', 'Primary', 'Projection Component Bridge', 'Mapped') ('Source account BAD DEBT 001', 'Provision for credit losses', '6045', 'Provision for credit losses', 'One To One', 'Primary', 'Projection Component Bridge', 'Mapped') ('Source account CAPITAL 001', 'Capital', '3030', "Members' equity", 'One To One', 'Primary', 'Projection Component Bridge', 'Mapped') ('Source account CASH 001', 'Cash', '1000', 'Cash - operating', 'One To One', 'Primary', 'Projection Component Bridge', 'Mapped') ('Source account COGS 001', 'Cost of goods sold', '6005', 'Cost of goods sold', 'One To One', 'Primary', 'Projection Component Bridge', 'Mapped') ('Source account DEBT 001', 'Debt', '2041', 'Notes payable', 'One To One', 'Primary', 'Projection Component Bridge', 'Mapped') ('Source account DEPR EXPENSE 001', 'Depreciation expense', '6080', 'Depreciation expense', 'One To One', 'Primary', 'Projection Component Bridge', 'Mapped') ('Source account EXPENSE 001', 'Expense', '6030', 'General and administrative', 'One To Many', 'Detail', 'Projection Component Bridge', 'Mapped') ('Source account EXPENSE 001', 'Expense', '6070', 'Interest expense', 'One To Many', 'Detail', 'Projection Component Bridge', 'Mapped') … 35 more linesTurn 41 · bashcd /workspace && python3 << 'EOF' import openpyxl from collections import defaultdict, Counter wb = openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx', data_only=True) ws = wb['Complete Journal Entry'] rows=list(ws.iter_rows(values_only=True)); hdr=rows[4]; data=[r for r in rows[5:1787] if r[0] is not None] idx={h:i for i,h in enumerate(hdr)} def c(n): return idx[n] entries=defaultdict(list) for r in data: entries[r[0]].append(r) cat=defaultdict(lambda:[0,0,0]) # entries, debits, credits for e,ls in entries.items(): src=ls[0][c('Source')]; typ=ls[0][c('Type')] if typ=='Manual': … 15 more linesOutputSystem-generated / automated count 376 DR 4863659.48 CR 4863659.48 Automated interface / subledger post count 424 DR 5726404.91 CR 5726404.91 Manual — standard count 38 DR 123370.87 CR 123370.87 TOTAL 838 10713435.26 10713435.26 all DR 10713435.26 all CR 10713435.26
- 6Read third-party evidence
Reads the bank, loan and customer confirmations sent directly to the auditor.
Turn 42 · pdftotext
Turn 42 · bashcd /workspace && for f in "direct_to_auditor/Bank Confirmation 12.31.2025.pdf" "direct_to_auditor/Loan Confirmation 2025.pdf" "direct_to_auditor/AR Confirmation - Vexmultix Quotane Holdings Inc.pdf"; do echo "===== $f ====="; pdftotext -layout "$f" - | head -60; done
Output===== direct_to_auditor/Bank Confirmation 12.31.2025.pdf ===== Z Zenvale Trust 6789 Commerce Lane, Jacksonville, FL 32099 +1 (312) 555-0456 STANDARD FORM TO CONFIRM ACCOUNT BALANCE INFORMATION FORM DCF-100 / REV. 09/25 / CONTROL BNK-15A272D543 Customer Quaxinov Staffing Services, LLC Information as of 12/31/2025 CUSTOMER AUTHORIZATION We authorize the financial institution named above to disclose the information requested below to our independent auditors. Christopher Zaxvole … 156 more lines - 7Inspect the template
Checks defined names, validations, merged cells and conditional formats so the fill preserves them.
6 turns · openpyxl, zipfile
Turn 30 · bashcd /workspace && python3 << 'EOF' import openpyxl wb = openpyxl.load_workbook('je_completeness_workpaper.xlsx') print('defined names:', list(wb.defined_names)) for ws in wb.worksheets: print('===',ws.title) if ws.data_validations and ws.data_validations.dataValidation: for dv in ws.data_validations.dataValidation: print(' DV', dv.type, dv.formula1, dv.sqref) else: print(' no DV') # conditional formatting for rng in ws.conditional_formatting: print(' CF', rng.sqref, rng.rules) … 1 more linesOutputdefined names: ['WP_PLAN_S002_0_SOURCE_INDEX_ENTITY_NAME', 'WP_PLAN_S002_0_SOURCE_INDEX_FINANCIAL_STATEMENT_DATE', 'WP_PLAN_S002_0_SOURCE_INDEX_REPORTING_CURRENCY', 'WP_PLAN_S002_0_SOURCE_INDEX_PERFORMANCE_MATERIALITY', 'WP_PLAN_S002_0_SOURCE_INDEX_TOLERABLE_MISSTATEMENT', 'WP_PLAN_S003_1_SCOPE_DATA_INTEGRITY_ENTITY_NAME', 'WP_PLAN_S003_1_SCOPE_DATA_INTEGRITY_FINANCIAL_STATEMENT_DATE', 'WP_PLAN_S003_1_SCOPE_DATA_INTEGRITY_REPORTING_CURRENCY', 'WP_PLAN_S003_1_SCOPE_DATA_INTEGRITY_PERFORMANCE_MATERIALITY', 'WP_PLAN_S003_1_SCOPE_DATA_INTEGRITY_TOLERABLE_MISSTATEMENT', 'WP_PLAN_S004_2_COMPLETENESS_ROLLFORWARD_ENTITY_NAME', 'WP_PLAN_S004_2_COMPLETENESS_ROLLFORWARD_FINANCIAL_STATEMENT_DATE', 'WP_PLAN_S004_2_COMPLETENESS_ROLLFORWARD_REPORTING_CURRENCY', 'WP_PLAN_S004_2_COMPLETENESS_ROLLFORWARD_PERFORMANCE_MATERIALITY', 'WP_PLAN_S004_2_COMPLETENESS_ROLLFORWARD_TOLERABLE_MISSTATEMENT', 'WP_PLAN_CONTEXT_ENTITY_NAME', 'WP_PLAN_CONTEXT_FINANCIAL_STATEMENT_DATE', 'WP_PLAN_CONTEXT_REPORTING_CURRENCY', 'WP_PLAN_CONTEXT_OVERALL_MATERIALITY', 'WP_PLAN_CONTEXT_PERFORMANCE_MATERIALITY', 'WP_PLAN_CONTEXT_TOLERABLE_MISSTATEMENT', 'WP_PLAN_CONTEXT_INDIVIDUALLY_SIGNIFICANT_THRESHOLD', 'WP_PLAN_CONTEXT_POSTING_THRESHOLD', 'WP_PLAN_CONTEXT_CLEARLY_TRIVIAL_THRESHOLD', 'WP_PLAN_CONTEXT_ANALYTICAL_PRECISION', 'WP_PROC_001_APPLICABILITY', 'WP_PROC_001_REQUIREMENT', 'WP_PROC_001_EXECUTION_STATE', 'WP_PROC_001_EVIDENCE_STATE', 'WP_PROC_001_RESULT_STATE', 'WP_PROC_001_ISSUE_STATE', 'WP_PROC_001_SIGNOFF_STATE', 'WP_PROC_001_DERIVED_OUTCOME', 'WP_PROC_001_PROCEDURE', 'WP_PROC_001_ASSERTION_S', 'WP_PROC_001_W_P_REF', 'WP_PROC_001_PERFORMED_BY', 'WP_PROC_001_DATE', 'WP_PROC_001_REASON_CODE', 'WP_PROC_001_SOURCE_FACT_EVIDENCE', 'WP_PROC_001_ISSUE_DEPENDENCY_IDS', 'WP_PROC_001_COMMENT_WORK_PERFORMED', 'WP_PROC_002_APPLICABILITY', 'WP_PROC_002_REQUIREMENT', 'WP_PROC_002_EXECUTION_STATE', 'WP_PROC_002_EVIDENCE_STATE', 'WP_PROC_002_RESULT_STATE', 'WP_PROC_002_ISSUE_STATE', 'WP_PROC_002_SIGNOFF_STATE', 'WP_PROC_002_DERIVED_OUTCOME', 'WP_PROC_002_PROCEDURE', 'WP_PROC_002_ASSERTION_S', 'WP_PROC_002_W_P_REF', 'WP_PROC_002_PERFORMED_BY', 'WP_PROC_002_DATE', 'WP_PROC_002_REASON_CODE', 'WP_PROC_002_SOURCE_FACT_EVIDENCE', 'WP_PROC_002_ISSUE_DEPENDENCY_IDS', 'WP_PROC_002_COMMENT_WORK_PERFORMED', 'WP_PROC_003_APPLICABILITY', 'WP_PROC_003_REQUIREMENT', 'WP_PROC_003_EXECUTION_STATE', 'WP_PROC_003_EVIDENCE_STATE', 'WP_PROC_003_RESULT_STATE', 'WP_PROC_003_ISSUE_STATE', 'WP_PROC_003_SIGNOFF_STATE', 'WP_PROC_003_DERIVED_OUTCOME', 'WP_PROC_003_PROCEDURE', 'WP_PROC_003_ASSERTION_S', 'WP_PROC_003_W_P_REF', 'WP_PROC_003_PERFORMED_BY', 'WP_PROC_003_DATE', 'WP_PROC_003_REASON_CODE', 'WP_PROC_003_SOURCE_FACT_EVIDENCE', 'WP_PROC_003_ISSUE_DEPENDENCY_IDS', 'WP_PROC_003_COMMENT_WORK_PERFORMED', 'WP_PROC_004_APPLICABILITY', 'WP_PROC_004_REQUIREMENT', 'WP_PROC_004_EXECUTION_STATE', 'WP_PROC_004_EVIDENCE_STATE', 'WP_PROC_004_RESULT_STATE', 'WP_PROC_004_ISSUE_STATE', 'WP_PROC_004_SIGNOFF_STATE', 'WP_PROC_004_DERIVED_OUTCOME', 'WP_PROC_004_PROCEDURE', 'WP_PROC_004_ASSERTION_S', 'WP_PROC_004_W_P_REF', 'WP_PROC_004_PERFORMED_BY', 'WP_PROC_004_DATE', 'WP_PROC_004_REASON_CODE', 'WP_PROC_004_SOURCE_FACT_EVIDENCE', 'WP_PROC_004_ISSUE_DEPENDENCY_IDS', 'WP_PROC_004_COMMENT_WORK_PERFORMED', 'WP_PROC_005_APPLICABILITY', 'WP_PROC_005_REQUIREMENT', 'WP_PROC_005_EXECUTION_STATE', 'WP_PROC_005_EVIDENCE_STATE', 'WP_PROC_005_RESULT_STATE', 'WP_PROC_005_ISSUE_STATE', 'WP_PROC_005_SIGNOFF_STATE', 'WP_PROC_005_DERIVED_OUTCOME', 'WP_PROC_005_PROCEDURE', 'WP_PROC_005_ASSERTION_S', 'WP_PROC_005_W_P_REF', 'WP_PROC_005_PERFORMED_BY', 'WP_PROC_005_DATE', 'WP_PROC_005_REASON_CODE', 'WP_PROC_005_SOURCE_FACT_EVIDENCE', 'WP_PROC_005_ISSUE_DEPENDENCY_IDS', 'WP_PROC_005_COMMENT_WORK_PERFORMED', 'WP_PROC_006_APPLICABILITY', 'WP_PROC_006_REQUIREMENT', 'WP_PROC_006_EXECUTION_STATE', 'WP_PROC_006_EVIDENCE_STATE', 'WP_PROC_006_RESULT_STATE', 'WP_PROC_006_ISSUE_STATE', 'WP_PROC_006_SIGNOFF_STATE', 'WP_PROC_006_DERIVED_OUTCOME', 'WP_PROC_006_PROCEDURE', 'WP_PROC_006_ASSERTION_S', 'WP_PROC_006_W_P_REF', 'WP_PROC_006_PERFORMED_BY', 'WP_PROC_006_DATE', 'WP_PROC_006_REASON_CODE', 'WP_PROC_006_SOURCE_FACT_EVIDENCE', 'WP_PROC_006_ISSUE_DEPENDENCY_IDS', 'WP_PROC_006_COMMENT_WORK_PERFORMED', 'WP_PROC_007_APPLICABILITY', 'WP_PROC_007_REQUIREMENT', 'WP_PROC_007_EXECUTION_STATE', 'WP_PROC_007_EVIDENCE_STATE', 'WP_PROC_007_RESULT_STATE', 'WP_PROC_007_ISSUE_STATE', 'WP_PROC_007_SIGNOFF_STATE', 'WP_PROC_007_DERIVED_OUTCOME', 'WP_PROC_007_PROCEDURE', 'WP_PROC_007_ASSERTION_S', 'WP_PROC_007_W_P_REF', 'WP_PROC_007_PERFORMED_BY', 'WP_PROC_007_DATE', 'WP_PROC_007_REASON_CODE', 'WP_PROC_007_SOURCE_FACT_EVIDENCE', 'WP_PROC_007_ISSUE_DEPENDENCY_IDS', 'WP_PROC_007_COMMENT_WORK_PERFORMED', 'WP_PROC_008_APPLICABILITY', 'WP_PROC_008_REQUIREMENT', 'WP_PROC_008_EXECUTION_STATE', 'WP_PROC_008_EVIDENCE_STATE', 'WP_PROC_008_RESULT_STATE', 'WP_PROC_008_ISSUE_STATE', 'WP_PROC_008_SIGNOFF_STATE', 'WP_PROC_008_DERIVED_OUTCOME', 'WP_PROC_008_PROCEDURE', 'WP_PROC_008_ASSERTION_S', 'WP_PROC_008_W_P_REF', 'WP_PROC_008_PERFORMED_BY', 'WP_PROC_008_DATE', 'WP_PROC_008_REASON_CODE', 'WP_PROC_008_SOURCE_FACT_EVIDENCE', 'WP_PROC_008_ISSUE_DEPENDENCY_IDS', 'WP_PROC_008_COMMENT_WORK_PERFORMED', 'WP_PROC_009_APPLICABILITY', 'WP_PROC_009_REQUIREMENT', 'WP_PROC_009_EXECUTION_STATE', 'WP_PROC_009_EVIDENCE_STATE', 'WP_PROC_009_RESULT_STATE', 'WP_PROC_009_ISSUE_STATE', 'WP_PROC_009_SIGNOFF_STATE', 'WP_PROC_009_DERIVED_OUTCOME', 'WP_PROC_009_PROCEDURE', 'WP_PROC_009_ASSERTION_S', 'WP_PROC_009_W_P_REF', 'WP_PROC_009_PERFORMED_BY', 'WP_PROC_009_DATE', 'WP_PROC_009_REASON_CODE', 'WP_PROC_009_SOURCE_FACT_EVIDENCE', 'WP_PROC_009_ISSUE_DEPENDENCY_IDS', 'WP_PROC_009_COMMENT_WORK_PERFORMED', 'WP_PROC_010_APPLICABILITY', 'WP_PROC_010_REQUIREMENT', 'WP_PROC_010_EXECUTION_STATE', 'WP_PROC_010_EVIDENCE_STATE', 'WP_PROC_010_RESULT_STATE', 'WP_PROC_010_ISSUE_STATE', 'WP_PROC_010_SIGNOFF_STATE', 'WP_PROC_010_DERIVED_OUTCOME', 'WP_PROC_010_PROCEDURE', 'WP_PROC_010_ASSERTION_S', 'WP_PROC_010_W_P_REF', 'WP_PROC_010_PERFORMED_BY', 'WP_PROC_010_DATE', 'WP_PROC_010_REASON_CODE', 'WP_PROC_010_SOURCE_FACT_EVIDENCE', 'WP_PROC_010_ISSUE_DEPENDENCY_IDS', 'WP_PROC_010_COMMENT_WORK_PERFORMED', 'WP_PROC_011_APPLICABILITY', 'WP_PROC_011_REQUIREMENT', 'WP_PROC_011_EXECUTION_STATE', 'WP_PROC_011_EVIDENCE_STATE', 'WP_PROC_011_RESULT_STATE', 'WP_PROC_011_ISSUE_STATE', 'WP_PROC_011_SIGNOFF_STATE', 'WP_PROC_011_DERIVED_OUTCOME', 'WP_PROC_011_PROCEDURE', 'WP_PROC_011_ASSERTION_S', 'WP_PROC_011_W_P_REF', 'WP_PROC_011_PERFORMED_BY', 'WP_PROC_011_DATE', 'WP_PROC_011_REASON_CODE', 'WP_PROC_011_SOURCE_FACT_EVIDENCE', 'WP_PROC_011_ISSUE_DEPENDENCY_IDS', 'WP_PROC_011_COMMENT_WORK_PERFORMED', 'WP_ANALYTIC_JE_COMPLETENESS_EXPECTED_MONTHLY_ANCHOR', 'WP_ANALYTIC_JE_COMPLETENESS_EXPECTED_MONTHLY_VALUE', 'WP_ANALYTIC_JE_COMPLETENESS_EXPECTED_MONTHLY_SOURCE_REFERENCE', 'WP_ANALYTIC_JE_COMPLETENESS_MONTHS_ANCHOR', 'WP_ANALYTIC_JE_COMPLETENESS_MONTHS_VALUE', 'WP_ANALYTIC_JE_COMPLETENESS_MONTHS_SOURCE_REFERENCE', 'WP_ANALYTIC_JE_COMPLETENESS_EXPECTED_TOTAL_ANCHOR', 'WP_ANALYTIC_JE_COMPLETENESS_EXPECTED_TOTAL_VALUE', 'WP_ANALYTIC_JE_COMPLETENESS_EXPECTED_TOTAL_SOURCE_REFERENCE', 'WP_ANALYTIC_JE_COMPLETENESS_ACTUAL_TOTAL_ANCHOR', 'WP_ANALYTIC_JE_COMPLETENESS_ACTUAL_TOTAL_VALUE', 'WP_ANALYTIC_JE_COMPLETENESS_ACTUAL_TOTAL_SOURCE_REFERENCE', 'WP_ANALYTIC_JE_COMPLETENESS_VARIANCE_ANCHOR', 'WP_ANALYTIC_JE_COMPLETENESS_VARIANCE_VALUE', 'WP_ANALYTIC_JE_COMPLETENESS_VARIANCE_SOURCE_REFERENCE', 'WP_ANALYTIC_JE_COMPLETENESS_PLAUSIBLE_ANCHOR', 'WP_ANALYTIC_JE_COMPLETENESS_PLAUSIBLE_VALUE', 'WP_ANALYTIC_JE_COMPLETENESS_PLAUSIBLE_SOURCE_REFERENCE'] === Library Procedures DV list "Applicable,Not Applicable - Fact Driven" A8 A10 A11 A12 A13 A14 A16 A17 A19 A20 A22 DV list "Required,Recommended" B8 B10 B11 B12 B13 B14 B16 B17 B19 B20 B22 DV list "Not Started,In Progress,Performed,Not Performed" C8 C10 C11 C12 C13 C14 C16 C17 C19 C20 C22 DV list "Sufficient,Missing,Unreadable,Unreliable,Contradictory,Not Required" D8 D10 D11 D12 D13 D14 D16 D17 D19 D20 D22 DV list "No Exception,Exception Identified,Unable to Conclude" E8 E10 E11 E12 E13 E14 E16 E17 E19 E20 E22 DV list "None,Open,Adjusted,Passed,Resolved,Superseded" F8 F10 F11 F12 F13 F14 F16 F17 F19 F20 F22 DV list "Unsigned,Prepared,Reviewed,Superseded" G8 G10 G11 G12 G13 G14 G16 G17 G19 G20 G22 CF A8:Q22 [<openpyxl.formatting.rule.Rule object> Parameters: type='expression', rank=None, priority=1, equalAverage=None, operator=None, aboveAverage=None, dxfId=0, stdDev=None, stopIfTrue=None, timePeriod=None, text=None, percent=None, bottom=None, colorScale=None, dataBar=None, iconSet=None, formula=['AND($F8="Open",$P8<>"")'], <openpyxl.formatting.rule.Rule object> Parameters: type='expression', rank=None, priority=2, equalAverage=None, operator=None, aboveAverage=None, dxfId=1, stdDev=None, stopIfTrue=None, timePeriod=None, text=None, percent=None, bottom=None, colorScale=None, dataBar=None, iconSet=None, formula=['OR($H8="Blocked",AND($F8="Open",$P8=""))'], <openpyxl.formatting.rule.Rule object> … 12 more lines
Turn 31 · bashcd /workspace && python3 << 'EOF' import openpyxl wb=openpyxl.load_workbook('je_completeness_workpaper.xlsx') for ws in wb.worksheets: print('===',ws.title) print(' hidden rows:', [d for d in ws.row_dimensions if ws.row_dimensions[d].hidden]) print(' hidden cols:', [d for d in ws.column_dimensions if ws.column_dimensions[d].hidden]) print(' merged:', ws.merged_cells.ranges) # comments for row in ws.iter_rows(): for c in row: if c.comment: print(' comment',c.coordinate, c.comment.text[:200]) # document properties print(wb.properties) … 1 more linesOutput=== Library Procedures hidden rows: [] hidden cols: [] merged: {<MergedCellRange I15:Q15>, <MergedCellRange I7:Q7>, <MergedCellRange A4:Q4>, <MergedCellRange I9:Q9>, <MergedCellRange I18:Q18>, <MergedCellRange I21:Q21>} === <.0> Source Index hidden rows: [] hidden cols: [] merged: {<MergedCellRange A32:G32>, <MergedCellRange B28:D28>, <MergedCellRange B5:G5>, <MergedCellRange B23:D23>, <MergedCellRange B22:D22>, <MergedCellRange B26:D26>, <MergedCellRange B27:D27>, <MergedCellRange B4:G4>, <MergedCellRange B30:D30>, <MergedCellRange B29:D29>, <MergedCellRange B25:D25>, <MergedCellRange B24:D24>, <MergedCellRange B6:G6>} === <.1> Scope & Data Integrity hidden rows: [] hidden cols: [] merged: {<MergedCellRange A50:H50>, <MergedCellRange B55:D55>, <MergedCellRange B59:D59>, <MergedCellRange B60:D60>, <MergedCellRange B61:D61>, <MergedCellRange B57:D57>, <MergedCellRange B4:H4>, <MergedCellRange A63:H63>, <MergedCellRange B58:D58>, <MergedCellRange B56:D56>, <MergedCellRange B6:H6>, <MergedCellRange B53:D53>, <MergedCellRange B5:H5>, <MergedCellRange B54:D54>} === <.2> Completeness Rollforward hidden rows: [] … 9 more linesTurn 32 · bashcd /workspace && python3 << 'EOF' import openpyxl wb=openpyxl.load_workbook('je_completeness_workpaper.xlsx') for n,dn in wb.defined_names.items(): if any(k in n for k in ['ANALYTIC','PLAN_']): print(n, '->', dn.attr_text if hasattr(dn,'attr_text') else dn.value) EOFOutputWP_PLAN_S002_0_SOURCE_INDEX_ENTITY_NAME -> '<.0> Source Index'!$B$2 WP_PLAN_S002_0_SOURCE_INDEX_FINANCIAL_STATEMENT_DATE -> '<.0> Source Index'!$E$2 WP_PLAN_S002_0_SOURCE_INDEX_REPORTING_CURRENCY -> '<.0> Source Index'!$H$2 WP_PLAN_S002_0_SOURCE_INDEX_PERFORMANCE_MATERIALITY -> '<.0> Source Index'!$B$3 WP_PLAN_S002_0_SOURCE_INDEX_TOLERABLE_MISSTATEMENT -> '<.0> Source Index'!$E$3 WP_PLAN_S003_1_SCOPE_DATA_INTEGRITY_ENTITY_NAME -> '<.1> Scope & Data Integrity'!$B$2 WP_PLAN_S003_1_SCOPE_DATA_INTEGRITY_FINANCIAL_STATEMENT_DATE -> '<.1> Scope & Data Integrity'!$E$2 WP_PLAN_S003_1_SCOPE_DATA_INTEGRITY_REPORTING_CURRENCY -> '<.1> Scope & Data Integrity'!$H$2 WP_PLAN_S003_1_SCOPE_DATA_INTEGRITY_PERFORMANCE_MATERIALITY -> '<.1> Scope & Data Integrity'!$B$3 WP_PLAN_S003_1_SCOPE_DATA_INTEGRITY_TOLERABLE_MISSTATEMENT -> '<.1> Scope & Data Integrity'!$E$3 WP_PLAN_S004_2_COMPLETENESS_ROLLFORWARD_ENTITY_NAME -> '<.2> Completeness Rollforward'!$B$2 WP_PLAN_S004_2_COMPLETENESS_ROLLFORWARD_FINANCIAL_STATEMENT_DATE -> '<.2> Completeness Rollforward'!$E$2 WP_PLAN_S004_2_COMPLETENESS_ROLLFORWARD_REPORTING_CURRENCY -> '<.2> Completeness Rollforward'!$H$2 WP_PLAN_S004_2_COMPLETENESS_ROLLFORWARD_PERFORMANCE_MATERIALITY -> '<.2> Completeness Rollforward'!$B$3 … 29 more lines
Turn 37 · bashcd /workspace && python3 << 'EOF' import openpyxl wb=openpyxl.load_workbook('je_completeness_workpaper.xlsx') ws=wb['Library Procedures'] for i,dxf in enumerate(ws.parent._differential_styles if hasattr(ws.parent,'_differential_styles') else []): print(i, dxf) EOFOutput0 ('count', '4')Turn 38 · bashcd /workspace && mkdir -p /tmp/wpx && cd /tmp/wpx && rm -rf * && unzip -o /workspace/je_completeness_workpaper.xlsx >/dev/null && ls -R | head -40 && echo "=== dxfs ===" && python3 -c " import re s=open('xl/styles.xml').read() m=re.search(r'<dxfs.*?</dxfs>',s,re.S) print(m.group(0) if m else 'none') "Outputbash: line 1: unzip: command not found
Turn 39 · bashcd /tmp/wpx && python3 -c " import zipfile,re z=zipfile.ZipFile('/workspace/je_completeness_workpaper.xlsx') s=z.read('xl/styles.xml').decode() m=re.search(r'<dxfs.*?</dxfs>',s,re.S) print(m.group(0)[:2000] if m else 'none') "Output<dxfs count="4"><dxf><fill><patternFill patternType="solid"><fgColor rgb="00FFF2CC"/></patternFill></fill></dxf><dxf><fill><patternFill patternType="solid"><fgColor rgb="00F4CCCC"/></patternFill></fill></dxf><dxf><fill><patternFill patternType="solid"><fgColor rgb="00D9EAD3"/></patternFill></fill></dxf><dxf><fill><patternFill patternType="solid"><fgColor rgb="00E7E6E6"/></patternFill></fill></dxf></dxfs>
- 8Prove the rollforward
Rolls all 21 accounts forward from the prior-year audited balances plus JE activity; every ending agrees to the closing trial balance.
Turns 45–46 · openpyxl
Turn 45 · bashcd /workspace && python3 << 'EOF' import openpyxl from collections import defaultdict # JE activity excluding opening carry-forward entry wb=openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx',data_only=True) ws=wb['Complete Journal Entry']; rows=list(ws.iter_rows(values_only=True)); hdr=rows[4] data=[r for r in rows[5:1787] if r[0] is not None] idx={h:i for i,h in enumerate(hdr)} def c(n): return idx[n] OPEN='JE-285291614009' act=defaultdict(float) for r in data: if r[0]==OPEN: continue act[r[c('Account')]] += (r[c('Debit')] or 0) - (r[c('Credit')] or 0) … 29 more linesOutputaccounts ['1000', '1010', '1011', '1030', '1050', '1051', '2000', '2021', '2025', '2041', '3030', '4000', '4010', '6005', '6030', '6032', '6034', '6045', '6055', '6070', '6080'] 21 PY net income 5351363.66 1000 E=1027075.44 F=1027075.44 G=0.00 H=1027075.44 I=1889747.69 J=-862672.25 1010 E=306327.50 F=306327.50 G=0.00 H=306327.50 I=153725.00 J=152602.50 1011 E=-49750.94 F=-49750.94 G=0.00 H=-49750.94 I=-24966.62 J=-24784.32 1030 E=31106.84 F=31106.84 G=0.00 H=31106.84 I=11597.26 J=19509.58 1050 E=192080.00 F=192080.00 G=0.00 H=192080.00 I=192080.00 J=0.00 1051 E=-84825.09 F=-84825.09 G=0.00 H=-84825.09 I=-119780.02 J=34954.93 2000 E=0.00 F=0.00 G=0.00 H=0.00 I=0.00 J=0.00 2021 E=0.00 F=0.00 G=0.00 H=0.00 I=-29906.36 J=29906.36 2025 E=0.00 F=0.00 G=0.00 H=0.00 I=0.00 J=0.00 2041 E=-118739.19 F=-118739.19 G=0.00 H=-118739.19 I=-114957.79 J=-3781.40 3030 E=-770074.90 F=-6121438.56 G=0.00 H=-6121438.56 I=-1303274.56 J=-4818164.00 4000 E=0.00 F=0.00 G=0.00 H=0.00 I=0.00 J=0.00 … 10 more lines
Turn 46 · bashcd /workspace && python3 << 'EOF' import openpyxl from collections import defaultdict wb=openpyxl.load_workbook('pbc_package/documents/Complete Journal Entry Population.xlsx',data_only=True) ws=wb['Complete Journal Entry']; rows=list(ws.iter_rows(values_only=True)); hdr=rows[4] data=[r for r in rows[5:1787] if r[0] is not None] idx={h:i for i,h in enumerate(hdr)} def c(n): return idx[n] OPEN='JE-285291614009' act=defaultdict(float) for r in data: if r[0]==OPEN: continue code=str(r[c('Account')]).split()[0] act[code]+= (r[c('Debit')] or 0)-(r[c('Credit')] or 0) … 24 more linesOutputPY NI 533199.66 1000 E=1027075.44 F=1027075.44 G=862672.25 H=1889747.69 I=1889747.69 J=0.00 1010 E=306327.50 F=306327.50 G=-152602.50 H=153725.00 I=153725.00 J=0.00 1011 E=-49750.94 F=-49750.94 G=24784.32 H=-24966.62 I=-24966.62 J=-0.00 1030 E=31106.84 F=31106.84 G=-19509.58 H=11597.26 I=11597.26 J=-0.00 1050 E=192080.00 F=192080.00 G=0.00 H=192080.00 I=192080.00 J=0.00 1051 E=-84825.09 F=-84825.09 G=-34954.93 H=-119780.02 I=-119780.02 J=0.00 2000 E=0.00 F=0.00 G=0.00 H=0.00 I=0.00 J=0.00 2021 E=0.00 F=0.00 G=-29906.36 H=-29906.36 I=-29906.36 J=0.00 2025 E=0.00 F=0.00 G=-0.00 H=-0.00 I=0.00 J=-0.00 2041 E=-118739.19 F=-118739.19 G=3781.40 H=-114957.79 I=-114957.79 J=-0.00 3030 E=-770074.90 F=-1303274.56 G=0.00 H=-1303274.56 I=-1303274.56 J=-0.00 4000 E=0.00 F=0.00 G=0.00 H=0.00 I=0.00 J=0.00 4010 E=-2942281.66 F=0.00 G=-3104222.50 H=-3104222.50 I=-3104222.50 J=0.00 … 9 more lines
- 9Fill and verify the workpaper
Writes every tab from one build script, recalculates in LibreOffice and re-reads the results.
Turns 47–55 · openpyxl, libreoffice
Turn 47 · bashcd /workspace && cat > /tmp/build.py << 'PYEOF' import openpyxl, datetime, json from openpyxl.utils import get_column_letter WB='je_completeness_workpaper.xlsx' wb=openpyxl.load_workbook(WB) PM=34922 # Planning Context performance materiality TM=34922 # Planning Context tolerable misstatement / testing threshold (testing threshold = PM) DATE=datetime.datetime(2026,4,10) # ---------------- Materiality on the three tabs ---------------- for tab in ['<.0> Source Index','<.1> Scope & Data Integrity','<.2> Completeness Rollforward']: ws=wb[tab] … 211 more linesOutputsaved
Turn 48 · bashcd /workspace && rm -rf /tmp/recalc && mkdir -p /tmp/recalc && timeout 180 libreoffice --headless --calc --convert-to xlsx:"Calc MS Excel 2007 XML" --outdir /tmp/recalc je_completeness_workpaper.xlsx 2>&1 | tail -3; ls -la /tmp/recalc
OutputWarning: failed to launch javaldx - java may not function correctly convert /workspace/je_completeness_workpaper.xlsx as a Calc document -> /tmp/recalc/je_completeness_workpaper.xlsx using filter : Calc MS Excel 2007 XML total 44 drwxr-xr-x 2 root root 4096 Sep 15 06:55 . drwxrwxrwt 1 root root 4096 Sep 15 06:55 .. -rw-r--r-- 1 root root 33724 Sep 15 06:55 je_completeness_workpaper.xlsx
Turn 49 · bashcd /workspace && python3 << 'EOF' import openpyxl wb=openpyxl.load_workbook('/tmp/recalc/je_completeness_workpaper.xlsx',data_only=True) print(wb.sheetnames) sc=wb['<.1> Scope & Data Integrity'] print('B36',sc['B36'].value,'B38',sc['B38'].value,'E43',sc['E43'].value,'B48',sc['B48'].value,'C48',sc['C48'].value,'D48',sc['D48'].value) rf=wb['<.2> Completeness Rollforward'] for r in range(9,30): print(r, rf.cell(r,3).value, rf.cell(r,5).value, rf.cell(r,6).value, rf.cell(r,7).value, rf.cell(r,8).value, rf.cell(r,9).value, rf.cell(r,10).value) print('totals', [rf.cell(59,get_column) for get_column in range(5,11)] if False else [rf.cell(59,c).value for c in range(5,11)]) print('B60', rf['B60'].value) lp=wb['Library Procedures'] for r in [8,10,11,12,13,14,16,17,19,20,22]: print(r, [lp.cell(r,c).value for c in range(1,9)]) … 1 more linesOutput['Library Procedures', '<.0> Source Index', '<.1> Scope & Data Integrity', '<.2> Completeness Rollforward', 'Planning Context'] B36 360 B38 478 E43 0.448687350835322 B48 838 C48 10713435.26 D48 10713435.26 9 1000 1027075.44 1027075.44 862672.25 1889747.69 1889747.69 0 10 1010 306327.5 306327.5 -152602.5 153725 153725 0 11 1011 -49750.94 -49750.94 24784.32 -24966.62 -24966.62 0 12 1030 31106.84 31106.84 -19509.58 11597.26 11597.26 0 13 1050 192080 192080 0 192080 192080 0 14 1051 -84825.09 -84825.09 -34954.93 -119780.02 -119780.02 0 15 2000 0 0 0 0 0 0 16 2021 0 0 -29906.36 -29906.36 -29906.36 0 17 2025 0 0 0 0 0 0 18 2041 -118739.19 -118739.19 3781.4 -114957.79 -114957.79 0 19 3030 -770074.9 -1303274.56 0 -1303274.56 -1303274.56 0 20 4000 0 0 0 0 0 0 … 22 more lines
Turn 50 · bashcd /workspace && python3 - << 'EOF' # patch build script: default H='Passed' s=open('/tmp/build.py').read() s=s.replace("common=dict(A='Applicable',B='Required',C='Performed',D='Sufficient',E='No Exception',F='None',G='Prepared',L='Audit Senior F43D',M=DATE)", "common=dict(A='Applicable',B='Required',C='Performed',D='Sufficient',E='No Exception',F='None',G='Prepared',H='Passed',L='Audit Senior F43D',M=DATE)") open('/tmp/build.py','w').write(s) print('patched') EOF python3 /tmp/build.py && python3 -c " import openpyxl wb=openpyxl.load_workbook('je_completeness_workpaper.xlsx') lp=wb['Library Procedures'] for r in [8,10,11,12,13,14,16,17,19,20,22]: print(r, lp.cell(r,8).value, '| L=',lp.cell(r,12).value,'M=',lp.cell(r,13).value,'| N=',repr(lp.cell(r,14).value)) … 1 more linesOutputpatched saved 8 Blocked | L= Audit Senior F43D M= 2026-04-10 00:00:00 | N= None 10 Passed | L= Audit Senior F43D M= 2026-04-10 00:00:00 | N= None 11 Passed | L= Audit Senior F43D M= 2026-04-10 00:00:00 | N= None 12 Passed | L= Audit Senior F43D M= 2026-04-10 00:00:00 | N= None 13 Passed | L= Audit Senior F43D M= 2026-04-10 00:00:00 | N= None 14 Passed | L= Audit Senior F43D M= 2026-04-10 00:00:00 | N= None 16 Passed | L= Audit Senior F43D M= 2026-04-10 00:00:00 | N= None 17 Passed | L= Audit Senior F43D M= 2026-04-10 00:00:00 | N= None 19 Passed | L= Audit Senior F43D M= 2026-04-10 00:00:00 | N= None 20 Passed | L= Audit Senior F43D M= 2026-04-10 00:00:00 | N= None 22 Blocked | L= Audit Senior F43D M= 2026-04-10 00:00:00 | N= None
Turn 51 · bashcd /workspace && rm -rf /tmp/recalc && mkdir -p /tmp/recalc && timeout 180 libreoffice --headless --calc --convert-to xlsx:"Calc MS Excel 2007 XML" --outdir /tmp/recalc je_completeness_workpaper.xlsx 2>&1 | tail -1 && python3 << 'EOF' import openpyxl wb=openpyxl.load_workbook('/tmp/recalc/je_completeness_workpaper.xlsx') lp=wb['Library Procedures'] print('DV count', len(lp.data_validations.dataValidation)) for dv in lp.data_validations.dataValidation: print(' ', dv.formula1, str(dv.sqref)[:60]) print('CF:') for rng in lp.conditional_formatting: for rule in rng.rules: print(' ', rng.sqref, rule.formula) print('defined names count:', len(wb.defined_names)) print('sheets', wb.sheetnames) # check materiality + source index content survived … 5 more linesOutputconvert /workspace/je_completeness_workpaper.xlsx as a Calc document -> /tmp/recalc/je_completeness_workpaper.xlsx using filter : Calc MS Excel 2007 XML DV count 7 "Applicable,Not Applicable - Fact Driven" A8 A10:A14 A16:A17 A19:A20 A22 "Required,Recommended" B8 B10:B14 B16:B17 B19:B20 B22 "Not Started,In Progress,Performed,Not Performed" C8 C10:C14 C16:C17 C19:C20 C22 "Sufficient,Missing,Unreadable,Unreliable,Contradictory,Not Required" D8 D10:D14 D16:D17 D19:D20 D22 "No Exception,Exception Identified,Unable to Conclude" E8 E10:E14 E16:E17 E19:E20 E22 "None,Open,Adjusted,Passed,Resolved,Superseded" F8 F10:F14 F16:F17 F19:F20 F22 "Unsigned,Prepared,Reviewed,Superseded" G8 G10:G14 G16:G17 G19:G20 G22 CF: A8:Q22 ['AND($F8="Open",$P8<>"")'] A8:Q22 ['OR($H8="Blocked",AND($F8="Open",$P8=""))'] A8:Q22 ['$H8="Passed"'] A8:Q22 ['OR($H8="Valid N/A",$H8="Recommended - Not Performed")'] … 5 more lines
Turn 52 · bashcd /workspace && python3 << 'EOF' import openpyxl wb=openpyxl.load_workbook('/tmp/recalc/je_completeness_workpaper.xlsx',data_only=True) for name in ['<.0> Source Index','<.1> Scope & Data Integrity','<.2> Completeness Rollforward','Library Procedures','Planning Context']: ws=wb[name] print('=============',name) for row in ws.iter_rows(): vals=[c.value for c in row] if any(v is not None for v in vals): print([ (c.coordinate,v) for c,v in zip(row,vals) if v is not None]) EOFOutput============= <.0> Source Index [('A1', 'Source Index')] [('A2', 'Client / Entity'), ('B2', 'Quaxinov Staffing Services, LLC'), ('D2', 'Year-End'), ('E2', datetime.datetime(2025, 12, 31, 0, 0)), ('G2', 'Currency'), ('H2', 'USD')] [('A3', 'Performance Materiality'), ('B3', 34922), ('D3', 'Tolerable misstatement / testing threshold'), ('E3', 34922)] [('A4', 'Purpose:'), ('B4', 'Map every journal-entry PBC source and its limitations so the evidence trail is complete and traceable.')] [('A5', 'Scope:'), ('B5', 'Complete JE / GL detail export (all entries, all periods), prior-year audited trial balance, current-year closing trial balance, system extraction logs / report parameters, chart of accounts, close checklist.')] [('A6', 'Assertions:'), ('B6', 'Completeness')] [('A7', 'Ref'), ('B7', 'Source document / PBC'), ('C7', 'Provided by'), ('D7', 'Date received'), ('E7', 'Format'), ('F7', 'Used in tab(s)'), ('G7', 'Limitations / notes')] [('A8', 'S-01'), ('B8', 'pbc_package/documents/Complete Journal Entry Population.xlsx - complete JE/GL detail for all entries and periods (838 entries / 1,782 lines); includes Population Controls, Account Reconciliation, Account Component Map and User Access Listing.'), ('C8', 'Client - Edward Vixmore (prepared) / Amanda Zarvex (reviewed)'), ('D8', '2025-12-31'), ('E8', 'xlsx'), ('F8', '<.0>, <.1>, <.2>'), ('G8', 'Extract header note states report parameters 2025-11-14 through 2025-12-31, which conflicts with the registered JE window 01/01/2025-12/31/2025; the population content (838 entries / 1,782 lines) agrees to the registered full-year in-window count and all control counts tie, so the file is treated as full-period complete. Extraction run date / operator not separately logged (see S-13).')] [('A9', 'S-02'), ('B9', 'pbc_package/foundational/TB 12 31 24.xlsx - prior-year audited trial balance.'), ('C9', 'Client - Edward Vixmore'), ('D9', '2025-12-31'), ('E9', 'xlsx'), ('F9', '<.0>, <.2>'), ('G9', 'Governance record; governs opening balances and agrees to the FY2024 audited financial statements.')] [('A10', 'S-03'), ('B10', 'pbc_package/foundational/TB 12 31 25.xlsx - current-year closing trial balance.'), ('C10', 'Client - Edward Vixmore'), ('D10', '2025-12-31'), ('E10', 'xlsx'), ('F10', '<.0>, <.2>'), ('G10', 'Governance record; foots to 0 and agrees to the current-year financial statements.')] [('A11', 'S-04'), ('B11', 'pbc_package/foundational/Chart of Accounts.xlsx - chart of accounts.'), ('C11', 'Client - Edward Vixmore'), ('D11', '2025-12-31'), ('E11', 'xlsx'), ('F11', '<.0>'), ('G11', 'IPE completeness/accuracy failed at planning (PL-CAII) - not relied upon; the 21-account population was validated from the JE account union instead.')] [('A12', 'S-05'), ('B12', 'pbc_package/documents/journal_entries/Journal Volume Summary 2024.pdf - prior-year journal-volume control report (360 entries; average 30.0 per month).'), ('C12', 'Client - Edward Vixmore'), ('D12', '2025-12-31'), ('E12', 'pdf'), ('F12', '<.0>, <.1>'), ('G12', 'Prior-year basis for expected-volume plausibility testing.')] [('A13', 'S-06'), ('B13', 'pbc_package/documents/Interim Trial Balance 6.30.2025.pdf - interim trial balance.'), ('C13', 'Client - Edward Vixmore'), ('D13', '2025-12-31'), ('E13', 'pdf'), ('F13', '<.0>'), ('G13', 'Not used - no interim procedures were performed (PL-ESAC).')] … 96 more linesTurn 53 · bashcd /workspace && python3 << 'EOF' import openpyxl wb=openpyxl.load_workbook('/tmp/recalc/je_completeness_workpaper.xlsx',data_only=True) rf=wb['<.2> Completeness Rollforward'] for r in range(19,30): print(r,[rf.cell(r,c).value for c in range(1,11)]) print('---totals---') for c in range(1,11): print(c, rf.cell(59,c).value) print('A60,B60', rf['A60'].value, rf['B60'].value) print('======= Library =======') lp=wb['Library Procedures'] for r in [8,10,11,12,13,14,16,17,19,20,22]: print('ROW',r) for c in range(1,18): … 3 more linesOutput19 ["Members' equity", 'BS', '3030', "Members' equity", -770074.9, -1303274.56, 0, -1303274.56, -1303274.56, 0] 20 ['Other income', 'PL', '4000', 'Other income', 0, 0, 0, 0, 0, 0] 21 ['Service revenue', 'PL', '4010', 'Service revenue', -2942281.66, 0, -3104222.5, -3104222.5, -3104222.5, 0] 22 ['Cost of services', 'PL', '6005', 'Cost of goods sold', 2374127.07, 0, 2117564.59, 2117564.59, 2117564.59, 0] 23 ['General and administrative', 'PL', '6030', 'General and administrative', 0, 0, 25764.38, 25764.38, 25764.38, 0] 24 ['Wages and salaries', 'PL', '6032', 'Wages and salaries', 0, 0, 239308.84, 239308.84, 239308.84, 0] 25 ['Employer payroll taxes', 'PL', '6034', 'Employer payroll taxes', 0, 0, 17382.8, 17382.8, 17382.8, 0] 26 ['Provision for credit losses', 'PL', '6045', 'Provision for credit losses', 0, 0, -24784.32, -24784.32, -24784.32, 0] 27 ['Insurance expense', 'PL', '6055', 'Insurance expense', 0, 0, 32745.2, 32745.2, 32745.2, 0] 28 ['Interest expense', 'PL', '6070', 'Interest expense', 0, 0, 7021.48, 7021.48, 7021.48, 0] 29 ['Depreciation expense', 'PL', '6080', 'Depreciation expense', 34954.93, 0, 34954.93, 34954.93, 34954.93, 0] ---totals--- 1 Totals / check-sums 2 None … 197 more lines
Turn 54 · bashcd /workspace && cp /tmp/recalc/je_completeness_workpaper.xlsx /workspace/je_completeness_workpaper.xlsx && python3 << 'EOF' import openpyxl p='/workspace/je_completeness_workpaper.xlsx' wb=openpyxl.load_workbook(p,data_only=True) print('sheets',wb.sheetnames) # confirm no default states remain on procedure rows lp=wb['Library Procedures'] defaults={'C':'Not Started','D':'Missing','E':'Unable to Conclude','G':'Unsigned'} bad=[] for r in [8,10,11,12,13,14,16,17,19,20,22]: for col,dv in defaults.items(): if lp[f'{col}{r}'].value==dv: bad.append((r,col)) print('defaults remaining:',bad) # materiality … 10 more linesOutputsheets ['Library Procedures', '<.0> Source Index', '<.1> Scope & Data Integrity', '<.2> Completeness Rollforward', 'Planning Context'] defaults remaining: [] <.0> Source Index 34922 34922 <.1> Scope & Data Integrity 34922 34922 <.2> Completeness Rollforward 34922 34922 source rows: ['S-01', 'S-02', 'S-03', 'S-04', 'S-05', 'S-06', 'S-07', 'S-08', 'S-09', 'S-10', 'S-11', 'S-12', 'S-13'] rollforward accts: ['1000', '1010', '1011', '1030', '1050', '1051', '2000', '2021', '2025', '2041', '3030', '4000', '4010', '6005', '6030', '6032', '6034', '6045', '6055', '6070', '6080'] B60 variance accts: 0 OK -rw-r--r-- 1 root root 33744 Sep 15 06:57 /workspace/je_completeness_workpaper.xlsx
Turn 55 · bashcd /workspace && python3 -c " import openpyxl wb=openpyxl.load_workbook('je_completeness_workpaper.xlsx') for t in wb.sheetnames: ws=wb[t]; print(t,'merged',len(ws.merged_cells.ranges),'| DV',len(ws.data_validations.dataValidation),'| CF',len(list(ws.conditional_formatting))) pc=wb['Planning Context'] print('PC B6..B12', [pc.cell(r,2).value for r in range(6,13)]) rf=wb['<.2> Completeness Rollforward'] print('J9 formula', rf['J9'].value, '| B36 formula', wb['<.1> Scope & Data Integrity']['B36'].value) "OutputLibrary Procedures merged 6 | DV 7 | CF 1 <.0> Source Index merged 13 | DV 0 | CF 0 <.1> Scope & Data Integrity merged 14 | DV 0 | CF 0 <.2> Completeness Rollforward merged 14 | DV 0 | CF 0 Planning Context merged 0 | DV 0 | CF 0 PC B6..B12 [46563, 34922, 34922, 11700, 2328, 2328, 34922] J9 formula =IF(OR(H9="",I9=""),"",H9-I9) | B36 formula =IF(OR(B34="",B35=""),"",B34*B35)
The completed workpaper, tab by tab. Highlighted cells were graded.
Identify the JE / GL systems and scope, prove the extraction is complete and unaltered (control counts source → extract → working file), run data-integrity checks, test population plausibility, and profile automated vs manual entries.
| Control | Per source | Per extract | Per working file | Comments |
|---|---|---|---|---|
Row / line count | 838 rows / 1,782 lines | 838 / 1,782 | 838 / 1,782 | Source = raw = working (Population Controls 'Tied'); no unexplained line difference. |
Total debits | 10,713,435.26 | 10,713,435.26 | 10,713,435.26 | Total debits tie at every hop; source-to-raw and raw-to-working debit difference = 0. |
Total credits | 10,713,435.26 | 10,713,435.26 | 10,713,435.26 | Total credits tie at every hop; source-to-raw and raw-to-working credit difference = 0. |
Identify the JE / GL systems and scope, prove the extraction is complete and unaltered (control counts source → extract → working file), run data-integrity checks, test population plausibility, and profile automated vs manual entries.
| Check | Result | Expected | Pass / fail |
|---|---|---|---|
Unbalanced journal entries (Dr ≠ Cr by JE) | 0 | 0 | Pass |
Records with blank posting dates | 0 | 0 | Pass |
Records with blank GL account numbers | 0 | 0 | Pass |
Records with missing user ID | 0 | 0 | Pass |
Duplicate JE numbers / IDs | 0 | 0 | Pass |
Records dated outside the period | 0 | 0 | Pass |
Records with blank / zero amounts | 0 | 0 | Pass |
JE headers without detail lines (orphans) | 0 | 0 | Pass |
Identify the JE / GL systems and scope, prove the extraction is complete and unaltered (control counts source → extract → working file), run data-integrity checks, test population plausibility, and profile automated vs manual entries.
| Entry type | Count | Debits | Credits | Share |
|---|---|---|---|---|
System-generated / automated | 376 | 4,863,659.48 | 4,863,659.48 | 44.87% |
Automated interface / subledger post | 424 | 5,726,404.91 | 5,726,404.91 | 50.60% |
Manual — standard | 38 | 123,370.87 | 123,370.87 | 4.53% |
Manual — top-side / adjusting | 0 | 0.00 | 0.00 | 0.00% |
Other | 0 | 0.00 | 0.00 | 0.00% |
Total | 838 | 10,713,435.26 | 10,713,435.26 |
Prove the journal-entry population is complete: for every GL account, opening balance per the prior-year audited TB (P&L accounts cleared to retained earnings) plus the JE activity per the population equals the client's closing TB — variance zero.
| Account | Description | Opening | JE activity | Recalculated | Per client TB | Variance |
|---|---|---|---|---|---|---|
| 1000 | Cash – operating | 1,027,075.44 | 862,672.25 | 1,889,747.69 | 1,889,747.69 | 0.00 |
| 1010 | Accounts receivable – trade | 306,327.50 | -152,602.50 | 153,725.00 | 153,725.00 | 0.00 |
| 1011 | Allowance for credit losses | -49,750.94 | 24,784.32 | -24,966.62 | -24,966.62 | 0.00 |
| 1030 | Prepaid expenses | 31,106.84 | -19,509.58 | 11,597.26 | 11,597.26 | 0.00 |
| 1051 | Accumulated depreciation | -84,825.09 | -34,954.93 | -119,780.02 | -119,780.02 | 0.00 |
| 2041 | Notes payable | -118,739.19 | 3,781.40 | -114,957.79 | -114,957.79 | 0.00 |
| 3030 | Members' equity | -1,303,274.56 | 0.00 | -1,303,274.56 | -1,303,274.56 | 0.00 |
| 4010 | Service revenue | 0.00 | -3,104,222.50 | -3,104,222.50 | -3,104,222.50 | 0.00 |
| 6005 | Cost of goods sold | 0.00 | 2,117,564.59 | 2,117,564.59 | 2,117,564.59 | 0.00 |
| 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
Agent’s closing summary
The workpaper is complete and saved to /workspace/je_completeness_workpaper.xlsx.
Summary of work performed:
Materiality (all three tabs) — Replaced the superseded planning-folder figures (PM 23,400 / TM 17,600) with the authoritative Planning Context values: Performance Materiality 34,922 and Tolerable misstatement / testing threshold 34,922 (testing threshold = PM per the context note).
<.0> Source Index — Indexed 13 sources (S‑01…S‑13): the complete JE/GL population and its control/reconciliation/COA-map/user-access tabs, PY and CY trial balances, chart of accounts, PY volume control report, interim TB, prior-year audited statements, disbursement/AP ledgers, CY financial statements, package index, and the direct-to-auditor confirmations, plus a documented limitation row for the missing extraction log / close checklist and the conflicting extract-parameter header note.
<.1> Scope & Data Integrity — Documented 6 JE sources in scope (General Journal, Sales Journal, Payroll, Fixed Assets, A/P, Cash Disbursements); proved control counts tie at every hop (838 entries / 1,782 lines; Dr = Cr = 10,713,435.26); ran all 8 integrity checks (0 exceptions, all Pass); tested plausibility (actual 838 vs PY expectation 360, flagged plausible with rationale); and profiled the population: 376 system-generated, 424 interface/subledger, 38 manual standard, 0 top-side, 0 other.
<.2> Completeness Rollforward — Rolled all 21 GL accounts forward (PY audited TB opening, P&L cleared to equity, plus validated JE activity = recalculated ending), agreeing to the client closing TB with zero variance on every account; explained the 533,199.66 prior-year net-income pickup into Members' equity; all column check-sums foot to ~0.
Library Procedures — Signed off all 11 procedures as Applicable/Required/Performed with Sufficient evidence, W/P references, preparer (Audit Senior F43D), dates and exact Evidence-Index citations; issue states are Closed/Passed except Procedure 1 and the Procedure 11 conclusion, which are Open/Blocked to reflect the documented outstanding extraction-log/close-checklist limitation — matching the conclusion's "subject to documented open items." All PROC:/WINDOW: dependency tokens were preserved.
Formulas were recalculated so cached results are visible, and data validations, conditional formatting, merges and the Planning Context tab were retained.
Graded by the released grader: exact checks on key balances, and a GPT-5.6 Luna judge where equivalent answers are allowed. A task passes only if every criterion does.
Amounts are rightControl totals and balances agree to the evidence.4/4
- Tie total debits through the extractPassed
Total debits are $10,713,435.26 in the source system, the raw extract and the working file.
- Test for unbalanced entriesPassed
No entry is unbalanced across all 838, and the check is marked Pass.
- Roll cash forwardPassed
Opening cash of $1,027,075.44 plus JE activity of $862,672.25 gives the recalculated ending of $1,889,747.69.
- Close prior-year income into equityPassed
Members' equity opens at a $1,303,274.56 credit once the prior-year P&L is closed into it.
Traceable documentationA reviewer can tie every comment to a record.3/3
- Tie source comments to systemsPassed
Every comment on the sources table sits on an identifiable ledger row.
- Tie profile comments to entry typesPassed
Every comment on the automated-vs-manual profile sits on an identifiable row.
- Tie rollforward comments to accountsPassed
Every comment on the rollforward sits on an identifiable GL account.
Results
We evaluated eleven frontier models (eight closed-weight, three open-weight) on 45 workpaper completion tasks. Each model attempted every task eight times, producing 3,960 trajectories. Agents received a bash interface as their only tool and were limited to 200 model calls per attempt.
Every model satisfied more than 85% of applicable rubric checks on average, but no model achieved strict pass on more than 69% of task attempts. Strict pass requires satisfying every applicable check in a workpaper.
Model Performance
At time of writing, Claude Opus 5.5 led all models with a 69% strict pass rate, and at $3.30 a run it cost half as much as the runner-up, Claude Fable 5.1 (66%). Thereafter we see a 19-point drop to Grok 4.6 (47%), and the field bottoms out at 28%. The best open-weight model, DeepSeek V4.1 Flash, strictly passed 33% of task runs at $0.14 a run.
Task-Level Performance
Across all eleven models and eight runs per model-task pair, the average strict-pass rate was 94.5% for journal entry completeness, compared with 52.1% to 68.2% across accounts payable, cash, debt and fixed assets. Performance was weakest on procedures estimated to require the most auditor time: journal entry testing (17%), revenue (8%) and accounts receivable (4%). These procedures often require the preparer to distinguish among several plausible sources of evidence – a recurring issue in our qualitative failure review.
Reliability Across Repeated Runs
To quantify dependability of an agent across runs, we use pass^k, which measures success on all k attempts. Model performance was not consistent across runs; Opus passes all eight attempts on only 44% of tasks, Fable on 31%, and Kimi K3 on none.
Common Failure Modes
To understand where agents went wrong and assess whether the rubrics were fair, auditors compared agent-completed workpapers with CPA-reviewed reference workpapers and reperformed selected procedures. Three patterns stood out:
- Insufficient retrieval. Agents analyze only the most obvious source document and conclude, on that basis alone, that the required evidence is unavailable. On a revenue cutoff procedure, for example, an agent reviewed a custom shipping cutoff schedule that lacked the necessary detail, although the full shipping log in the same binder contained it.
- Weighing evidence poorly. Agents relied on client-prepared evidence without obtaining the external corroboration required by the procedure. For example, an agent vouched receivables to a client-prepared cash-receipts report but did not agree the reported receipts to bank activity. The report therefore showed what the client recorded, not whether the cash had been received.
- Completing tasks with insufficient information. Unlike insufficient retrieval, this failure arises when the information a procedure requires is genuinely absent from the binder. Rather than noting that the procedure cannot be performed as designed, agents document work using whatever information is available. For example, an agent that had not been provided any subsequent-period information documented a subsequent-events procedure using current-year transactions.
Limitations
FAB evaluates staff-level procedures across six synthetic engagements in two industries. It does not capture every dimension of a production audit, including client interaction, requests for additional evidence, supervision and rework, or engagement-level judgment. Its results should therefore be interpreted as evidence about performance on the evaluated tasks – not readiness to conduct an audit autonomously.
Additionally, FAB’s rubrics primarily measure whether selected balances, calculations and conclusions are correct; they do not measure how easily another auditor can review the resulting workpaper. In qualitative review, auditors found that agents often documented their process at length while leaving the relevant evidence, its significance and the resulting conclusion less clear. Sentence fragments and poor cell formatting created additional review friction. These observations suggest that reviewability is a distinct dimension of workpaper quality—one that future evaluations should measure alongside correctness.
Guidance for our Peers
We built Financial Audit Bench to answer practical questions: where can firms use agents today, where do they still require substantial oversight, and how do those answers change as models improve? The results suggest that agents can complete meaningful portions of staff-level audit work, but their outputs still require professional review.
We therefore recommend deploying agents as co-pilots rather than autonomous preparers. Human-in-the-loop systems will likely address the evidence-selection and escalation failures observed in FAB, although the benchmark did not directly evaluate interactive auditor intervention.
The development of this paper also highlighted the velocity at which new model releases are changing the landscape of AI in audit. Within a matter of weeks, the benchmark’s leading strict-pass rate rose from below 50% with Grok 4.6 to 69.2% with Opus 5.5. That pace favors model-agnostic infrastructure that allows firms to evaluate and adopt stronger models and agent frameworks as they emerge.
Appendix: Key Terms
Audit
- Engagement
- The audit of one company for one reporting period, usually a fiscal year.
- Engagement binder
- The materials for one engagement: planning documents, client-provided records, third-party evidence and blank workpaper templates.
- Workpaper
- A spreadsheet, organized by a predefined template, where auditors document the procedures performed, evidence examined and conclusions reached.
- Substantive fieldwork
- The audit phase in which auditors respond to assessed risks by performing procedures and gathering evidence.
- Client-provided (PBC) records
- Records, financial documents and ledgers prepared and supplied by the audited company.
- Third-party evidence
- Evidence sent directly to the auditor by outside parties, such as bank confirmations.
Benchmark
- Rubric check
- One graded data point, calculation or conclusion. Rubrics average about ten per workpaper.
- Strict pass
- A workpaper passes only if every applicable check is met.
- Partial credit
- The share of applicable checks met.
- pass@k
- Whether at least one of k attempts strictly passes.
- pass^k
- Whether all k attempts strictly pass.
- Differential privacy
- A formal guarantee that adding or removing any one historical audit binder barely changes the released statistics. FAB’s guarantee is (ε = 3.65, δ = 10⁻⁵).